LLM Enhancements
BellowsKV: Rethinking the KV Cache Across Transformer Layers
BellowsKV compresses KV caches across layers. Its accuracy results are promising, but serving gains still need measurement.
KV-cache compression is usually framed as a question of how much information each transformer layer can afford to lose. BellowsKV asks a different question: how much information do neighboring layers need to store independently?
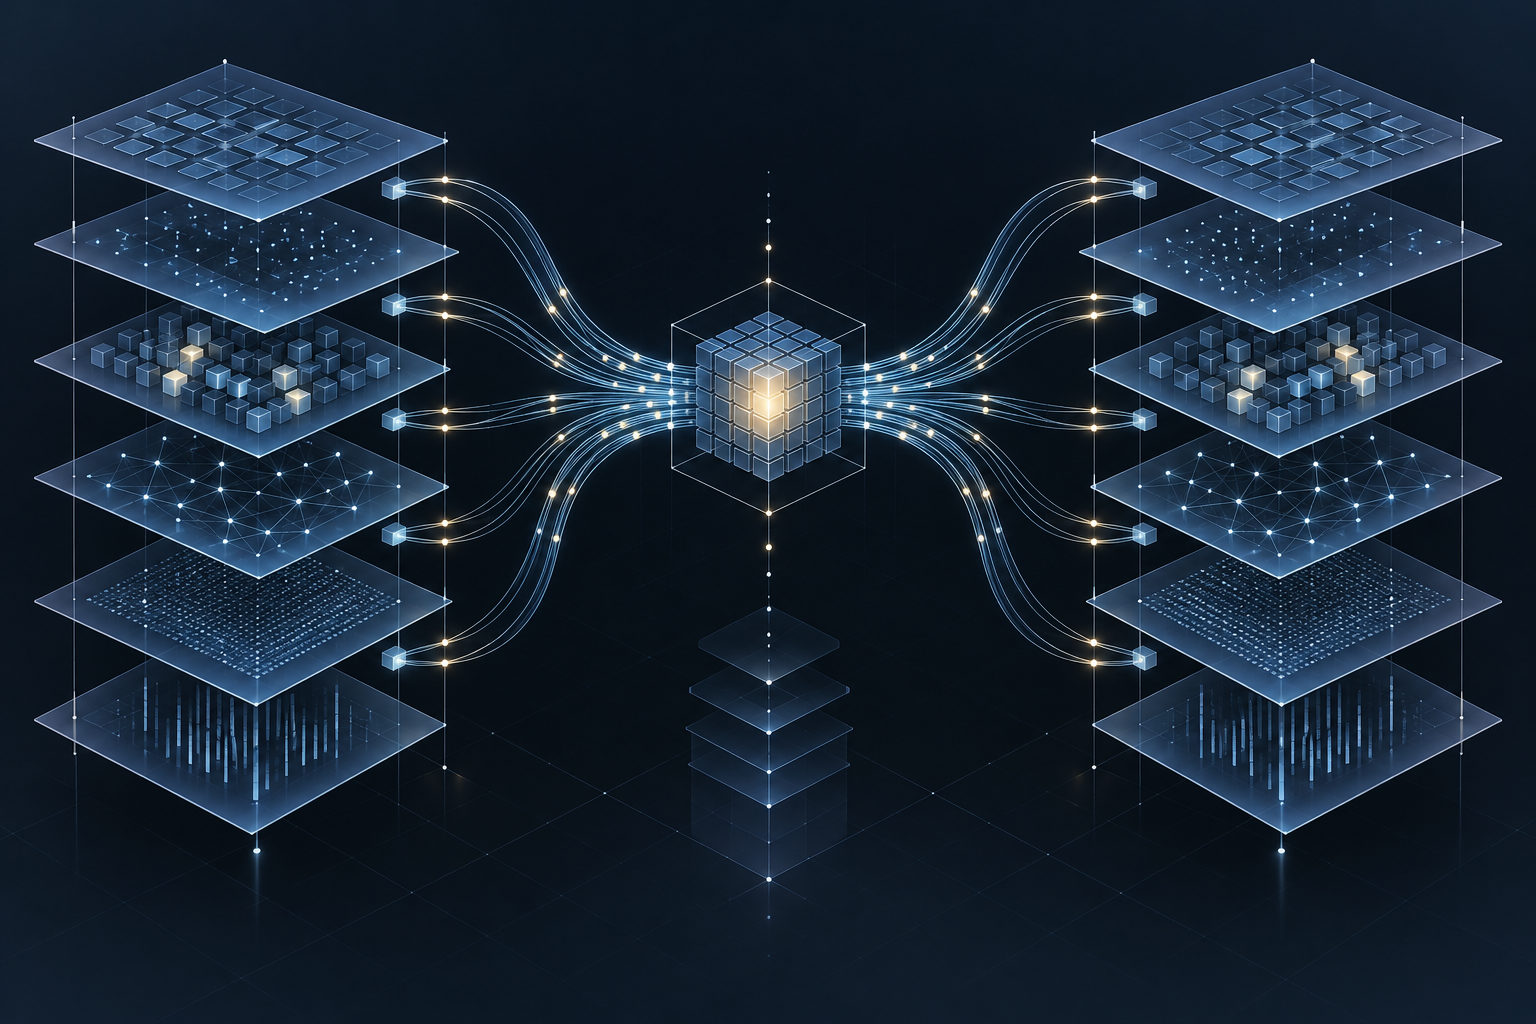
That shift matters because autoregressive inference maintains historical keys and values across both tokens and layers. Longer sequences increase the cache, but so does the number of layers maintaining their own representations. BellowsKV targets this second dimension by storing a shared latent representation across adjacent layers and reconstructing each layer’s attention inputs when needed.[3]
The headline result is substantial. Across Llama-3.1-8B, Mistral-7B, and Qwen2.5-7B, the quantized variant, BellowsKV-Quant, reportedly retains approximately 99% of full-cache accuracy at 3.6× compression, and 97% to 98% at 13× to 14× compression.[3]
For infrastructure teams, those numbers justify attention, not an immediate deployment conclusion. The available evidence describes an accuracy and compression trade-off. It does not establish faster decoding, lower request costs, or greater production throughput. Understanding the difference requires separating the method’s storage design from the systems work needed to make that design useful.
1. The bottleneck is not just context length
During autoregressive inference, the KV cache preserves keys and values for previously processed tokens. Later decoding steps can use that history without recomputing the full context. The memory cost grows as the sequence grows, while each transformer layer normally maintains its own cache.[3]
This makes cache capacity a constraint on how a serving system uses GPU memory. A larger cache leaves less room for concurrent requests and can push the system toward smaller batches, cache eviction, or offloading. The BellowsKV authors identify KV-cache memory as a potential main bottleneck for GPU serving.[3]
The important architectural detail is that layers do not necessarily need completely independent stored representations. Adjacent layers process the same token sequence and may contain correlated information. BellowsKV attempts to exploit that redundancy rather than treating every layer’s cache as a separate compression problem.[3]
This distinguishes two questions that can otherwise become conflated. One is how precisely to store a tensor. The other is how many independently stored representations are necessary. Low-bit KV quantization addresses the first. BellowsKV addresses the second, while its quantized variant combines the two approaches.[3]
For engineers, this expands the design space beyond choosing a numerical format. For infrastructure buyers, it also changes what a compression claim needs to explain. A smaller representation may create capacity headroom, but the system must still recover the information each layer needs. Storage savings and the cost of consuming that storage belong in the same evaluation.
2. One latent for adjacent layers, expanded when needed
The paper, “BellowsKV: One Latent for Many Layers, Expanded on Demand,” was submitted to arXiv on October 26, 2026, and updated on October 27, 2026. It describes a training-free method that maps the hidden states of multiple adjacent layers to one shared latent per token.[3]
At inference time, each layer uses its own projection to reconstruct key and value information from that latent. The stored object is shared across the layer group, while the information consumed by attention remains layer-specific.[3]
The mechanism can be understood as three steps:
- Combine information across adjacent layers. Instead of preserving each layer’s KV tensors independently, represent their information through a shared latent.
- Store the shared representation. Keep one latent per token for the participating group of layers.
- Expand for each consumer. Use a layer-specific projection to recover the key and value information required by that layer.[3]
The separation between storage and consumption is the central contribution. The cache no longer has to mirror the layer-by-layer organization of its consumers. That creates an opportunity to remove redundant stored information without relying exclusively on lower numerical precision.
“Training-free” means the cache-compression procedure does not require retraining the base model.[3] It should not be read as “integration-free” or “compute-free.” The method explicitly introduces reconstruction through projections, and the available source does not quantify the additional work those projections require.
BellowsKV-Quant adds quantization to the cross-layer representation.[3] This is important when interpreting the reported results: the strongest figures in the brief belong to the quantized variant. They should not be presented as an isolated measurement of the benefit from cross-layer sharing alone.
3. What the reported accuracy results establish
BellowsKV’s strongest evidence is its reported preservation of accuracy under substantial cache compression. The available source covers three model families: Llama-3.1-8B, Mistral-7B, and Qwen2.5-7B.[3]
| Reported setting | Compression | Accuracy retained relative to a full cache |
|---|---|---|
| BellowsKV-Quant | 3.6× | Approximately 99% |
| BellowsKV-Quant, more aggressive setting | 13× to 14× | 97% to 98% |
| Strongest competing cross-layer method cited by the paper | 16× | At most 84% |
These figures suggest that cross-layer compression can extend beyond modest reductions while preserving much of the measured accuracy. The aggressive BellowsKV-Quant setting is particularly relevant to memory-constrained serving because it targets a much smaller stored cache representation.[3]
The baseline comparison needs care. BellowsKV’s 13× to 14× result and the competing method’s 16× result are not measurements at identical compression ratios. They indicate a promising accuracy and compression trade-off in a similar high-compression regime, not a controlled comparison at the same storage budget.[3]
“99% of full-cache accuracy” also describes relative retention, not an absolute task score of 99%. The available abstract does not identify the exact evaluation tasks or define the accuracy metric. Without those details, readers cannot determine how the aggregate result maps to a particular production workload.[3]
That limitation matters for adoption. A team needs to know whether the evaluations exercise the behaviors its users depend on and whether the observed degradation is acceptable. The reported percentages provide a reason to reproduce the result, but they do not replace workload-specific quality testing.
The model scope is similarly bounded. Evidence from the three named families does not establish equivalent behavior on larger or newer models. BellowsKV should be assessed as a demonstrated research direction within the reported scope, rather than a universal compression guarantee.
4. Compression is not yet a complete memory or performance result
A compression ratio describes the relationship between representations under a particular accounting method. It does not automatically describe the reduction in total GPU memory consumed by a serving deployment.
For BellowsKV, the available source does not specify whether the ratios include metadata, projection parameters, indexing structures, or temporary reconstruction buffers. It also does not report before-and-after GPU memory consumption in gigabytes.[3] These omissions leave an important gap between the paper’s headline ratio and the capacity a deployment could actually recover.
A useful systems evaluation should therefore distinguish three measurements:
- Stored cache size: the memory occupied by the compressed representation and its associated structures.
- Peak runtime memory: the footprint when reconstruction and other serving activity are included.
- Usable serving capacity: the workload the system can sustain within its memory and latency constraints.
The reconstruction path creates a second accounting problem: compute. Each layer must recover its key and value information through a projection, but the available evidence does not quantify that overhead or report decode latency and throughput at each compression setting.[3]
The central systems question is whether the benefit of storing a smaller cache outweighs the cost of reconstructing its contents. That balance depends on GPU arithmetic throughput, memory bandwidth, sequence length, batch size, and implementation details. The available BellowsKV results do not resolve it.[3]
Consequently, teams should not translate 3.6× cache compression into 3.6× throughput, or 13× to 14× compression into an equivalent reduction in serving cost. Those are different quantities. The same caution applies to time to first token and energy per token, neither of which is established by the reported accuracy results.
This does not diminish the compression result. It identifies the next measurement needed to turn it into an infrastructure claim.
5. Where a smaller cache could help serving
The most direct potential benefit is concurrent request capacity. If each active sequence requires less cache memory, more sequences may fit within the same GPU memory budget. Whether that headroom produces useful throughput depends on reconstruction overhead and the behavior of the serving workload.
Long-context operation is another candidate. A smaller representation may allow longer contexts before memory exhaustion. However, the available evidence does not describe BellowsKV’s behavior across long-context lengths and large batch sizes, so this remains a deployment hypothesis rather than a measured result.[3]
Cache residency could also improve. Keeping more active requests on GPU may reduce the need for eviction or transfers to host memory. Again, the source does not report measured changes in eviction behavior, offloading, or transfer volume.
Distributed inference introduces an additional possibility: fewer stored bytes might mean fewer bytes to move between devices or serving stages. But that depends on how the representation is integrated into the distributed system. The available source provides no measured communication results and does not establish compatibility with tensor, pipeline, or expert parallelism.[3]
These possibilities are best treated as separate evaluation targets:
- Does the method admit more concurrent requests within a fixed memory budget?
- Does it support the required context length while preserving acceptable quality?
- Does it reduce eviction or offloading under the target workload?
- Does its distributed implementation reduce data movement after reconstruction costs are included?
Continuous batching and multi-tenant serving also need direct testing because neither is characterized in the available evidence.[3] A quality result on the named models cannot answer how the method behaves under those operating conditions.
The practical distinction is between capacity made available and capacity productively used. BellowsKV’s representation creates a plausible route to the first. A serving implementation must demonstrate the second.
6. Representation compression and runtime orchestration solve different problems
BellowsKV sits alongside research that changes how caches are managed rather than how they are represented. One example is MCF, described in “MCF: A Memory- and Communication-Aware Co-Designed Framework for Long-Context LLM Inference.”[2]
MCF uses communication-aware, stage-adaptive KV-cache layout transitions. Its Memory-Aware Replication and Scheduling mechanism, MARS, selectively replicates highly reused KV blocks during early chunked prefill, when memory headroom is available. As memory pressure increases, it drains redundant replicas and converges toward a sharded layout suitable for decoding.[2]
For decoding, MCF keeps KV shards stationary and routes query tensors across workers. The source reports improvements in time to first token, throughput, and scalability over distributed inference systems, with larger benefits as context length and cluster size increase.[2]
The distinction is straightforward: BellowsKV changes the representation stored for each token across layers. MCF changes where KV data resides, when it is replicated, and how execution moves around it. Their available evidence also differs. BellowsKV emphasizes compression and accuracy retention, while MCF reports serving performance improvements.[2][3]
Morph, presented in “Request-Adaptive Execution for Efficient Hybrid LLM Inference,” targets another dimension. It co-designs model architecture and runtime for request-adaptive hybrid inference, using selective batching to preserve batching efficiency despite divergent layer choices. It also supports hybrid-aware context caching for prefix reuse.[1]
These directions should not be collapsed into one category of interchangeable cache optimization. They address persistent representation, distributed placement, and request-adaptive execution, respectively. BellowsKV could potentially complement orchestration techniques such as MCF, but the brief provides no combined implementation or measured result. Complementarity is a research opportunity, not an established deployment outcome.
7. What this means for teams running their own inference infrastructure
BellowsKV gives self-hosted inference teams a concrete reason to look beyond per-layer KV quantization. Its reported results suggest that adjacent-layer redundancy can support substantial compression while preserving much of the measured full-cache accuracy.[3]
The right next step is a bounded evaluation, not a blanket assumption of lower serving costs. Start with the constraint that matters in the current deployment: concurrent sequence capacity, long-context feasibility, cache residency, or distributed data movement. That determines which outcome would make the method valuable.
Then evaluate quality and systems behavior together. Quality testing should use the workloads the deployment must support, with the full-cache configuration as a reference. Systems testing should account for the complete memory footprint, projection overhead, latency, and throughput at each candidate compression level. A setting is useful only if its quality and operational trade-offs are acceptable together.
Infrastructure buyers should ask for the same evidence. A cache compression ratio is not a substitute for measured capacity under a stated workload. Claims should identify the model, context lengths, batch conditions, memory accounting, hardware configuration, and latency or throughput outcome. Those details are not supplied by the available BellowsKV abstract.[3]
The broader lesson is architectural: the KV cache need not be treated as an immutable collection of independent per-layer tensors. Shared representations offer another way to manage its footprint. BellowsKV makes that possibility credible through its reported accuracy results. Whether it becomes a practical serving optimization depends on demonstrating that the memory and capacity benefits exceed the cost of expanding the latent when each layer needs it.
Sources
- [1]Request-Adaptive Execution for Efficient Hybrid LLM Inference
- [2]MCF: A Memory- and Communication-Aware Co-Designed Framework for Long-Context LLM Inference
- [3]BellowsKV: One Latent for Many Layers, Expanded on Demand
- [4]Green Code or Costly Code? Evaluating the Energy Costs of Iterative LLM-Based Code Optimizations
- [5]MemoraX AI Researchers and Collaborators Have 10 Papers
- [6]LLMs in Cloud: A Discussion on Architecture, Orchestration, and Inference
- [7]Data Optimization for LLMs: A Survey
- [8]Context or Knowledge: How LLMs Attribute Their Own Answers
- [9]phase/notes/2026-10-speculative-decoding.md at main ... - GitHub
- [10]LLM Daily: October 23, 2026 • Buttondown
Researched from the sources above and fact-checked against them before publishing.
See what this means for your infrastructure.
Book a discovery call and get a benchmark projection for your hardware and model.
SCHEDULE A CALL