
LLM Enhancements
D-REAL and the Case for Training Speculative Drafters Around Acceptance Length
D-REAL reports up to 9.4% higher serving throughput by training speculative drafters directly for acceptance length.
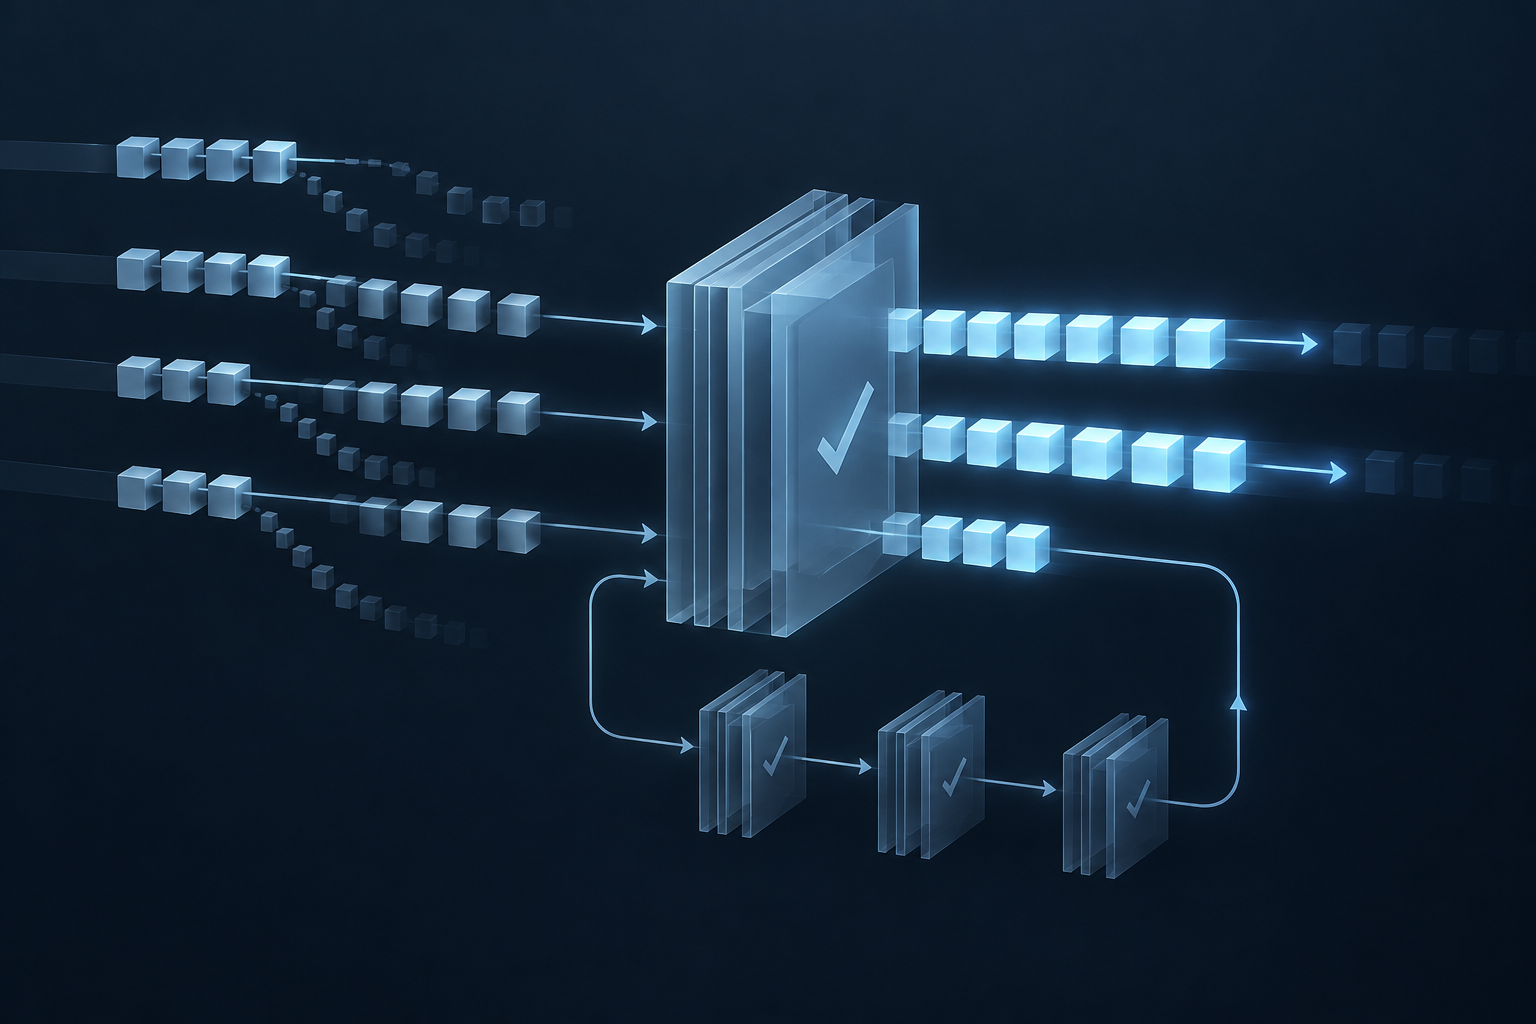
Speculative decoding creates an opportunity to accelerate inference by separating token proposal from token verification. A smaller drafter proposes several tokens, and a larger target model checks them. The serving benefit depends on how much of that proposed sequence the target accepts, relative to the work required to draft and verify it.
That makes acceptance length an important training target, not just a useful evaluation statistic. D-REAL, short for Drafter Reinforcement of Expected Acceptance Length, takes this approach directly. Submitted to arXiv on November 7, 2026, it is described as a post-training method that optimizes expected acceptance length for a fixed decoding context. The supplied report attributes up to 0.23 additional tokens in benchmark-averaged mean acceptance length and up to 9.4% higher end-to-end serving throughput to the method.[3]
For engineers and infrastructure buyers, the interesting development is the connection between the training objective and serving behavior. The results suggest an opportunity to improve a speculative-decoding system by changing what its drafter learns to optimize. They also leave important deployment questions unanswered.
1. Acceptance Length Connects Drafter Training to Serving Work
In speculative decoding, the drafter proposes a sequence rather than asking the target model to generate every token individually. The target verifies the proposal and can accept a prefix in one verification pass. The length of that accepted prefix determines how much draft work contributes to the output before another target verification round is required.
This creates a distinction between being a good language model and being a useful drafter. A drafter can perform well as a standalone model while proposing sequences that its target frequently rejects. Training it to match the target's next-token distribution may improve acceptance, but a conventional token-level objective does not necessarily optimize the number of consecutive tokens accepted during a verification cycle.
D-REAL makes that sequence-level outcome explicit. Its stated objective is expected acceptance length for a fixed decoding context, rather than a general task score or a conventional language-modeling objective.[3] The objective is closely connected to the execution pattern that speculative decoding is intended to exploit.
The motivation is particularly relevant when a system has already captured the easier gains. The D-REAL report describes evaluation from baselines whose mean acceptance length had plateaued. Its question is therefore not simply whether speculative decoding helps, but whether targeted post-training can extract additional useful work from a drafter after baseline improvements have leveled off.[3]
For operators, this changes the evaluation question. Instead of asking only whether a drafter is more accurate or more capable, teams should ask whether it produces longer accepted prefixes for the target and decoding settings they actually serve. Acceptance length is not the final business metric, but it is a more direct measure of the drafter's contribution to this execution strategy.
2. What D-REAL Reports, and How to Read the Numbers
The principal reported result is an improvement of up to 0.23 tokens in benchmark-averaged mean acceptance length after one epoch of post-training. The evaluation covers both architectures examined in the paper and includes greedy decoding at temperature T = 0.0 and stochastic sampling at T = 1.0.[3]
Those conditions matter. Acceptance behavior can change when sampling is introduced, so a result limited to greedy decoding would support a narrower deployment case. Including both settings broadens the reported evaluation, although it does not establish performance at other temperatures or across every serving configuration.
The report also associates the acceptance-length improvement with up to 9.4% higher end-to-end serving throughput.[3] This is the more operationally relevant result. It indicates that the reported improvement was not confined to an offline training or acceptance metric: the evaluated serving system also processed work faster.
These figures need careful interpretation:
- The acceptance improvement is absolute. An additional 0.23 tokens is not a 23% improvement. Without the baseline acceptance lengths, the supplied material does not support a relative percentage calculation.
- The throughput result is a maximum. “Up to 9.4%” describes the largest reported gain, not an expected improvement for every workload.
- The training statement describes epochs, not cost. One epoch does not establish the number of examples, elapsed training time, or hardware required.
- Coverage is not uniformity. Evaluation across two architectures and two decoding settings does not mean that every condition achieved the maximum reported result.
The supplied report does not include the detailed measurements needed to reconstruct how acceptance changes translated into throughput changes across individual configurations. Consequently, the two headline numbers should be presented together as reported results, not treated as a universal conversion rule between accepted tokens and serving performance.[3]
The evidence supports a focused conclusion: acceptance-aware post-training improved a serving-relevant metric and produced a measured end-to-end benefit under the evaluated conditions.
3. Why More Accepted Tokens Do Not Guarantee a Fixed Speedup
Acceptance length helps explain speculative-decoding performance, but it does not describe the whole system. Draft generation consumes resources. Verification also has a cost. Batching, memory traffic, and runtime implementation influence whether a longer accepted prefix translates into higher throughput.
The operational objective is therefore not simply to maximize acceptance length in isolation. It is to obtain more useful output relative to the total cost of drafting and verification. A training objective can move the acceptance metric in the right direction without determining the size of the final serving gain.
D-REAL's end-to-end result is valuable precisely because it extends beyond that intermediate metric. The report links acceptance-aware post-training to up to 9.4% higher serving throughput, rather than stopping at a change in mean acceptance length.[3] That makes the result worth investigating for infrastructure teams, while still requiring workload-specific validation.
The supplied material does not state whether the maximum throughput gain was measured at a fixed latency requirement, under fixed throughput demand, or with a particular workload mix. It also omits batch size, request concurrency, sequence length, and the hardware and inference framework used. Those omissions prevent a direct mapping from the headline figure to a production capacity plan.
A useful evaluation should consequently keep two questions separate. First, does the trained drafter improve acceptance length in the intended deployment context? Second, does that improvement increase end-to-end throughput under the team's operating constraints?
Measuring both helps avoid two errors: dismissing a fractional acceptance-length improvement as necessarily insignificant, or assuming that any acceptance improvement must deliver a proportional serving gain. D-REAL's report shows why the first assumption can be wrong. The missing deployment details explain why the second remains unsafe.
4. REAL Loss Addresses the Objective Behind the Method
A related paper, REAL Loss: Optimizing Real Expected Acceptance Length for Speculative Decoding, was submitted to arXiv on November 10, 2026. It addresses how to construct the training loss for expected acceptance length, describing path weights for unbiased estimation and Rao-Blackwellization for variance reduction.[6]
The distinction from D-REAL is important. D-REAL is presented as a post-training method intended to improve expected acceptance length. REAL Loss focuses on estimating that objective through a loss construction designed to avoid the bias associated with alternative approximations.[3][6] The supplied sources do not establish that they are the same implementation or provide a direct head-to-head comparison.
Their reported evaluation evidence is also different. REAL Loss uses a Qwen3.6-35B-A3B target and a Domino drafter. In a controlled loss-level comparison, it reportedly outperformed WTV, VSD, DBLast, and the static LK baseline on probabilistic-serving acceptance length across nine task subsets and five evaluation seeds.[6]
That scope adds useful detail. Multiple task subsets provide a broader comparison than a single aggregate result, while repeated seeds introduce repeated evaluation rather than relying on one random run. However, those details should not be transferred to D-REAL. The supplied material does not identify D-REAL's target and drafter models, nor does it establish that its experiments used the same task subsets or seeds.
Likewise, REAL Loss's acceptance-length comparison should not be presented as an independent confirmation of D-REAL's 9.4% throughput figure. The reports support different claims: one provides a post-training result with an end-to-end throughput measurement, while the other provides a comparison between loss formulations.[3][6]
Together, they point toward acceptance-aware optimization as a research direction. One emphasizes improving drafter behavior through post-training; the other emphasizes the fidelity of the objective used to train that behavior. Both make expected acceptance length a design target rather than merely a statistic collected after training.
5. The Missing Details That Matter for Deployment
The available evidence is enough to motivate an evaluation, but not enough to reproduce the reported serving result from the brief alone. Several missing details are essential to deciding whether the approach fits a particular infrastructure environment.
Model and workload identity. D-REAL is reported across two architectures, but the supplied material does not name its target or drafter models. It also does not identify the benchmark tasks or provide their count. Teams therefore cannot establish how closely the tested model pairings and inputs resemble their own deployment.[3]
Serving configuration. Hardware, inference framework, batch size, sequence length, and request concurrency are not provided. Without these, the throughput number cannot be interpreted as a capacity estimate for another stack.
Baseline measurements. The report gives the maximum acceptance-length improvement but not the baseline and post-training acceptance lengths. Those values would help establish the relative size of the change and clarify what “plateaued” meant in each evaluated configuration.
Variability. Confidence intervals and the statistical variability of D-REAL's improvements are not available in the supplied report. The maximum reported gain therefore does not reveal how consistent the improvement was across repeated measurements or evaluated conditions.
Training effort. One epoch is a useful description of the reported procedure, but it is not a complete measure of the investment required. Training-example count, wall-clock time, and training hardware are not stated.
These gaps do not invalidate the reported results. They limit the decisions those results can support. In particular, the headline throughput gain should not be used by itself to forecast hardware savings, establish a purchasing requirement, or promise a production service improvement. It is evidence of potential under evaluated conditions, not a general performance guarantee.
6. Turning the Research into a Local Evaluation
For a team already using speculative decoding, the most useful next step is a controlled comparison that separates acceptance improvements from serving improvements. The recommendations below are evaluation guidance, not additional claims about D-REAL's published experiments.
Start with the existing target, drafter, workload, and runtime configuration. Record baseline mean acceptance length and end-to-end throughput, along with the latency conditions under which that throughput is measured. Also record the decoding settings, batch behavior, request concurrency, and sequence lengths needed to interpret the result.
Then compare the post-trained drafter against that baseline while keeping the surrounding evaluation conditions consistent. This makes the central question easier to answer: did the drafter change improve the system, or did another configuration change influence the measurement?
Where relevant to the deployment, evaluate greedy and stochastic decoding separately. D-REAL's reported coverage includes T = 0.0 and T = 1.0, but teams should test their actual serving settings rather than assume those results cover every sampling configuration.[3]
Acceptance length and throughput should appear together in the evaluation report. If acceptance improves without a useful throughput gain, investigate drafting cost, verification cost, batching, memory traffic, and runtime behavior. If throughput improves, retain the workload and configuration details necessary to establish where the gain holds.
Finally, measure the post-training effort locally. The reported one-epoch result makes training scope a worthwhile question, but it does not answer the economic question. Teams need their own training cost and serving measurements before deciding whether the improvement justifies adopting and maintaining the trained drafter.
7. What This Means for Teams Running Their Own Inference Infrastructure
D-REAL presents a concrete reason to examine drafter training as part of inference optimization. Its reported gains come from directly targeting expected acceptance length, including on baselines described as having reached an acceptance-length plateau. The result is up to 0.23 additional accepted tokens in benchmark-averaged mean acceptance length after one epoch, associated with up to 9.4% higher end-to-end serving throughput.[3]
For teams operating their own infrastructure, the practical implication is not that a particular throughput improvement is now available everywhere. It is that the training objective deserves scrutiny alongside the serving configuration. A drafter's general quality is not a sufficient explanation of how much useful work it contributes to speculative decoding.
The related REAL Loss results reinforce that direction while addressing a different part of the problem: constructing an acceptance-length objective with unbiased estimation and variance reduction, then comparing it against alternative losses.[6] Teams should keep that evidence distinct from D-REAL's serving result rather than combine the two into a broader claim than either supports.
For infrastructure buyers, the corresponding diligence question is straightforward: can an acceptance-aware approach demonstrate an end-to-end benefit on the model pairing, workload, and operating constraints that matter to the purchase? Reported maxima are useful signals for investigation, but local measurements must establish the deployment case.
The strongest takeaway is therefore methodological. Train toward the behavior the serving system needs, measure that behavior directly, and verify the benefit at the system level. D-REAL provides evidence that this alignment can produce meaningful throughput gains. The remaining work for operators is to determine whether those gains survive the conditions of their own inference stack.
Sources
- [1]Private LLM Inference: Optimizing Tricycle | Proceedings of the 3rd ACM Workshop on Large AI Systems and Models with Privacy and Safety Analysis
- [2]MOSAIC: Efficient Collaborative Inference for Multi-Modal Large Language Models with Distributed Edge Computing | Proceedings of the Twenty-seventh International Symposium on Theory, Algorithmic Foundations, and Protocol Design for Mobile Networks and Mobile Computing
- [3]D-REAL: Acceptance-Length Optimization with Unbiased Gradients for Speculative Decoding - Scholar Inbox
- [4]Memory-Decoupled Layer-Wise Fine-Tuning for Efficient On-Device LLM Adaptation | Proceedings of the 2026 ACM Symposium on Cloud Computing Volume 1
- [5]On Evaluating Performance of LLM Inference Systems | Proceedings of the 2026 ACM Symposium on Cloud Computing Volume 1
- [6]REAL Loss: Optimizing Real Expected Acceptance Length for Speculative Decoding - Scholar Inbox
- [7]Shan Zhou on alphaXiv
- [8]Same Request, Different Answer: Quantization Amplifies Cache-Induced Divergence in LLM Serving
- [9]No Request Left Behind: Tackling Heterogeneity in Long-Context LLM Inference with Medha | Proceedings of the 2026 ACM Symposium on Cloud Computing Volume 1
- [10]mini-infer
Researched from the sources above and fact-checked against them before publishing.
See what this means for your infrastructure.
Book a discovery call and get a benchmark projection for your hardware and model.
SCHEDULE A CALL