
LLM Enhancements
IgniteServe Moves LLM Cold Starts Off the Serial Path
IgniteServe treats LLM startup as state-aware orchestration, reporting lower latency for both fully cold and cache-resident starts.
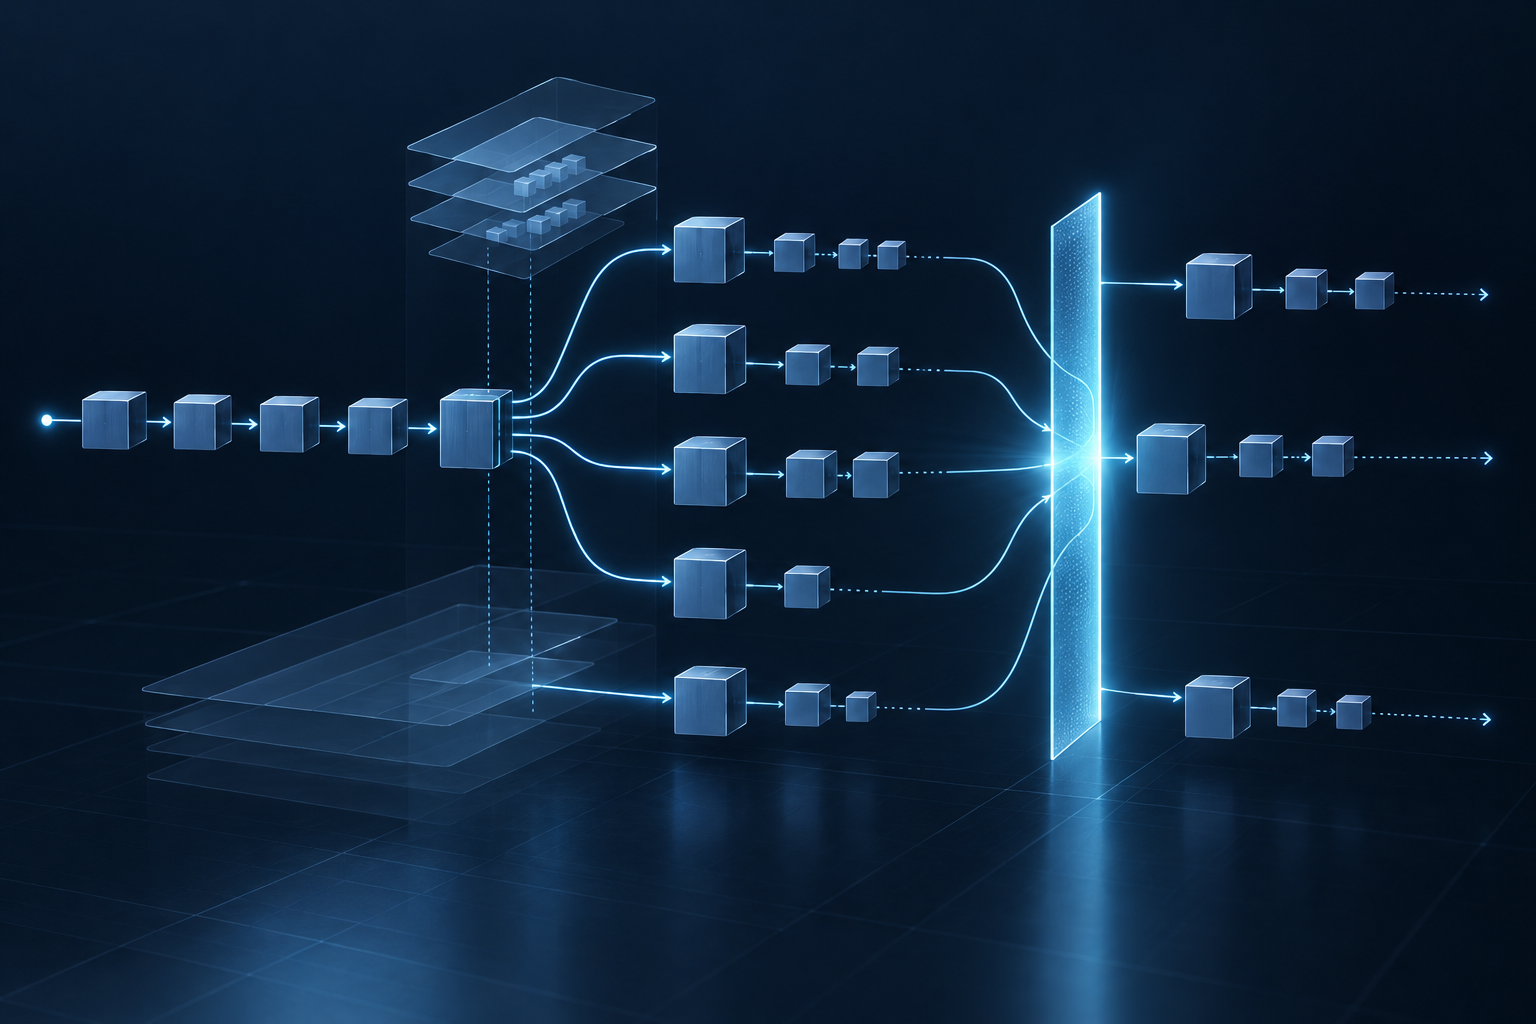
A serving engine can generate tokens efficiently and still take too long to become useful. Throughput and token latency describe performance once a worker is running. They do not capture the delay between launching that worker and making it available to accept requests. For infrastructure that scales dynamically or replaces failed workers, that interval is a separate performance problem.
IgniteServe targets this gap. Its central idea is to treat startup as state-aware orchestration rather than a fixed sequence of initialization steps. Instead of placing every optimization task on a serial path to readiness, the design considers task dependencies, reusable state, and whether work must finish before service begins. The paper reports average startup-latency reductions of 69.3% relative to vLLM for fully cold starts and 56% for cache-resident starts.[1]
Those results concern a different layer of inference efficiency from faster kernels or better batching. IgniteServe asks how quickly capacity can become serviceable, not simply how efficiently it operates afterward. For engineers and infrastructure buyers, the distinction changes both what should be benchmarked and what evidence is needed before adopting a startup optimization.
1. Cold Start Is a Capacity Availability Problem
An inference deployment has at least two relevant performance phases: becoming ready and processing requests. Optimizing the second phase does not automatically improve the first. A worker with strong steady-state performance cannot contribute capacity while it is still initializing.
The research brief identifies launch, restart, scale-out, and loss of reusable state as situations where startup latency matters. IgniteServe attributes part of that latency to optimization work executed in a predetermined serial order, even when some tasks are independent, reusable, or deferrable.[1] This makes the startup sequence itself a target for optimization, separate from the execution speed of any individual task.
For autoscaling systems, the practical issue is responsiveness. Adding replicas is useful only when those replicas become available soon enough to address demand. For fault-tolerant deployments, the corresponding issue is replacement capacity: launching a replacement worker and restoring usable service are not the same event. Startup time also matters in serverless platforms, intermittent model loading, and development environments that repeatedly initialize serving engines.
These implications should not be confused with measured business outcomes. The available evidence does not quantify how much IgniteServe reduces overprovisioning, changes infrastructure spending, or improves application-level availability. It establishes comparative startup improvements, not a deployment-specific economic result.[1]
The useful framing is therefore narrower and more actionable: startup latency is a constraint on when new capacity becomes usable. Teams should measure it independently rather than assume that a favorable token-generation benchmark captures the full behavior of a serving stack. A system can perform well after initialization while remaining slow to respond to changes in required capacity.
2. The Design Changes Which Work Blocks Readiness
IgniteServe describes startup as a collection of optimization tasks with different dependencies and urgency. Some can execute concurrently. Some produce state that can be reused. Others can be deferred until after the engine becomes available. Its architectural contribution is fine-grained parallelization governed by those distinctions.[1]
This differs from a fixed startup pipeline in an important way. In a serial sequence, every stage can extend the path to readiness, including work that does not need to block initial request processing. Making each stage somewhat faster may help, but it leaves the overall execution structure intact. IgniteServe instead seeks to change that structure.
The design can be understood through three questions:
- What must finish before service begins? Readiness-critical work must remain on the path to availability.
- What useful state already exists? Reusable optimization state can change which work needs to be performed.
- What can run independently or later? Work without a blocking dependency can potentially execute concurrently or continue after readiness.
These questions summarize the architectural motivation, not an implementation recipe. The available material does not enumerate the exact task graph, identify every reusable artifact, or explain the mechanisms used to coordinate background work. It supports the broader claim that startup can be scheduled according to dependencies and state rather than treated as an invariant sequence.[1]
That distinction also explains why IgniteServe is not simply another kernel optimization. Its target is the critical path to service availability. Quantization, kernel fusion, speculative decoding, and KV-cache optimization primarily address request-processing costs. Startup orchestration addresses the work that precedes processing, making it complementary to those approaches in purpose, although the available evidence does not establish performance for every possible combination.
3. The Reported Gains Cover Two Startup States
IgniteServe reports improvements against vLLM, ServerlessLLM, and Medusa in both fully cold and cache-resident conditions. All figures below are average startup-latency reductions reported in the paper's abstract.[1]
| Baseline | Fully cold startup reduction | Cache-resident startup reduction |
|---|---|---|
| vLLM | 69.3% | 56% |
| ServerlessLLM | 65.4% | 46% |
| Medusa | 61% | 40.1% |
The fully cold result is important because reusable optimization artifacts are unavailable in that condition. IgniteServe's reported benefit therefore cannot be explained only by retrieving previously prepared state. The result supports the broader premise that the organization of startup work matters even when useful artifacts are not already available.[1]
The cache-resident result addresses a different question: does reusable state eliminate enough startup work to make orchestration less relevant? The reported 56% average reduction relative to vLLM indicates that substantial comparative gains remain in the evaluated cache-resident setting.[1] Having reusable state and reaching readiness efficiently are not equivalent.
However, these categories need careful handling. The available material gives a broad distinction between fully cold and cache-resident starts, but not the exact experimental definition of each state. It does not specify every artifact present, its location, or the conditions required for reuse. Teams should not assume their own definition of a warm or cached startup matches the paper's evaluation.
The comparisons with ServerlessLLM and Medusa also matter. IgniteServe reports gains over systems characterized in the brief as static optimization approaches, rather than only over vLLM.[1] That broadens the comparative evidence within the reported evaluation. It does not establish that IgniteServe will deliver the same improvement across every configuration of those systems or every production environment.
4. A Startup Percentage Is Not a Deployment Forecast
The headline reductions are substantial, but percentages alone do not establish operational impact. The available source material does not provide absolute startup times, hardware configuration, model lists, workload distribution, statistical variance, or precise cache-state definitions. Those omissions limit what can be concluded from the reported averages.[1]
Absolute times are essential because infrastructure decisions depend on how long capacity remains unavailable, not only on the relative improvement. A percentage reduction cannot tell a team whether a new worker will meet its required scale-out response time without the underlying duration. Likewise, an average does not show how consistently the improvement appears across models or configurations.
Hardware and model coverage matter for the same reason. Without those details, buyers cannot establish how closely the evaluation resembles their deployment. The appropriate interpretation is that IgniteServe reports strong comparative improvements under its evaluated conditions, not that every inference stack should expect an identical reduction.
A production evaluation should therefore separate several questions:
- What event marks the beginning of startup?
- What exact condition marks service readiness?
- Which optimization artifacts are absent or reusable?
- How do startup durations vary across the intended models and configurations?
- What work remains after the engine becomes available?
The last question follows directly from the design's use of deferral. Moving work beyond the readiness boundary can shorten startup, but evaluators should still examine behavior after that boundary. This is a validation requirement, not evidence that IgniteServe introduces a runtime penalty. The supplied material does not establish such a penalty.
The same discipline applies to cost claims. Faster startup may be relevant to provisioning strategy, but the reported results are not direct measurements of infrastructure savings. Translating them into a purchasing or capacity decision requires deployment-specific evidence about startup frequency, demand behavior, and the capacity needed while new workers become available.
5. Startup Complements Scheduling and Adapter Serving
Other serving research helps clarify where IgniteServe fits. Its contribution addresses the transition into service, while related work focuses on how active capacity is shared and used.
Feather, introduced in “Requests of a Feather Must Flock Together: Batch Size vs. Prefix Homogeneity in LLM Inference,” is a prefix-aware scheduler. It uses reinforcement learning to learn the tradeoff between batch size and prefix homogeneity.[4] That is a runtime scheduling problem: how should requests be grouped once an engine is processing work? IgniteServe addresses the preceding question of how quickly that engine becomes ready.
InfiniLoRA focuses on disaggregated multi-LoRA serving. It reports up to 3.05 times higher serviceable request rates than existing multi-LoRA serving systems under strict time-to-first-token and time-per-output-token service-level objectives. It also reports a 54.0% improvement in the fraction of adapters meeting stringent SLO targets.[9] Those results concern adapter multiplexing and sustained serving capacity, not engine startup latency.
These metrics should remain separate. A startup-latency reduction is not interchangeable with a higher serviceable request rate. Nor can improvements from different papers be added together to predict a combined deployment result. They describe different bottlenecks, evaluation conditions, and outcomes.
Production context comes from “Model-as-a-Service in the Wild,” which analyzes a six-month inference trace from xMaaS, described as a large-scale model-as-a-service platform with over 100K GPUs.[2] That study provides context for serving decisions at scale, but the available result does not report a comparable cold-start optimization.
Together, these works support a layered view of inference infrastructure: startup determines when capacity becomes usable, scheduling determines how requests share it, and adapter management determines how heterogeneous model variants use it. Production workload characteristics provide the setting in which those mechanisms must be evaluated.[1][2][4][9]
6. Make Readiness a First-Class Benchmark
The most useful operational lesson from IgniteServe is to make startup visible in performance evaluation. A benchmark that begins only after the engine is ready excludes the interval this design seeks to improve. That benchmark may still describe steady-state performance accurately, but it cannot answer how quickly a deployment adds usable capacity.
Teams can begin by reporting time to service availability separately from performance after service begins. This preserves the distinction between startup orchestration and request execution. It also makes comparisons easier to interpret: a candidate system might improve one phase without improving the other.
Startup measurements should distinguish fully cold and reusable-state conditions rather than collapse them into a single number. IgniteServe's results demonstrate why that distinction matters: the reported reductions differ by state and baseline.[1] A local evaluation should document what is present in each condition instead of relying only on labels such as cold, warm, or cached.
Readiness itself also needs an explicit definition. Because IgniteServe separates mandatory readiness work from optimization that can continue later, evaluators should identify what the engine can do at the moment it is declared available. Measurements immediately after readiness should be distinguished from measurements taken after remaining optimization work has completed.
A useful evaluation structure would include:
- Startup duration under clearly documented state conditions.
- The readiness criterion used to stop the startup measurement.
- Request-serving behavior immediately after readiness.
- Steady-state performance after initialization activity has settled.
- Variation across the models and configurations relevant to the deployment.
These are recommended evaluation dimensions, not additional results reported for IgniteServe. Their purpose is to prevent a strong startup result from being mistaken for a complete serving-performance assessment. They also help infrastructure buyers compare claims that may otherwise use different measurement boundaries.
7. What This Means for Teams Running Their Own Inference Infrastructure
For teams operating their own inference stack, IgniteServe suggests a concrete shift in attention: examine the startup dependency structure, not just the speed of individual initialization operations. The key questions are which tasks truly block readiness, which can reuse existing state, and which can run concurrently or safely continue later.
That does not mean every team should immediately redesign its serving engine. The first step is to establish whether startup is a meaningful operational bottleneck. Environments with frequent scale-out, worker replacement, intermittent model loading, or repeated engine initialization have clear reasons to investigate it. The value of an optimization still depends on the deployment's actual behavior.
Where startup does matter, the reported results justify closer technical evaluation. IgniteServe reports lower average startup latency than all three baselines in both evaluated state categories, including a 69.3% reduction against vLLM for fully cold starts and 56% for cache-resident starts.[1] Those are promising comparative results, but not substitutes for testing representative hardware, models, and readiness requirements.
Infrastructure buyers should ask for the same evidence. A throughput claim describes active capacity. A startup claim describes how quickly additional capacity becomes available. Both matter, and neither should be used as a proxy for the other.
The broader lesson is that serving readiness is an optimization target in its own right. Reusable state helps, but state-aware orchestration determines how remaining work reaches completion. IgniteServe makes that orchestration explicit. For self-managed inference teams, the practical opportunity is to evaluate the path from launch to service with the same discipline already applied to token generation.
Sources
- [1]IgniteServe: Accelerating LLM Serving Engine Cold Starts via Fine-Grained Parallelization | Proceedings of the 2026 ACM SIGOPS Annual Technical Conference
- [2]Model-as-a-Service in the Wild: Characterizing Production LLM Inference Clusters at Scale | Proceedings of the 2026 ACM SIGOPS Annual Technical Conference
- [3]Reducing Batch Makespan for LLM Agent Workloads through Inference, Environment Coordination
- [4]Requests of a Feather Must Flock Together: Batch Size vs. Prefix Homogeneity in LLM Inference | Proceedings of the 2026 ACM SIGOPS Annual Technical Conference
- [5]Towards Green Text Generation: Memory-Based Speculative Decoding
- [6]DForkTree: Accelerating Speculative Decoding with Fork-Aware Block Diffusion Draft Trees
- [7]Smart Model Routing for Order-of-Magnitude LLM Cost Reduction · mlsanity
- [8]Building a Decision Pipeline on NVIDIA AIPerf
- [9]InfiniLoRA: Disaggregated Multi-LoRA Serving for Large Language Models | Proceedings of the 2026 ACM SIGOPS Annual Technical Conference
- [10]Read Once, Answer Many: Parallel Prompting for Shared-Context LLM Inference
Researched from the sources above and fact-checked against them before publishing.
See what this means for your infrastructure.
Book a discovery call and get a benchmark projection for your hardware and model.
SCHEDULE A CALL