LLM Enhancements
LLM-CoOpt and the Case for Joint Model and Hardware Optimization
LLM-CoOpt targets inference bottlenecks across algorithms and mixed hardware, but missing benchmarks limit deployment conclusions.
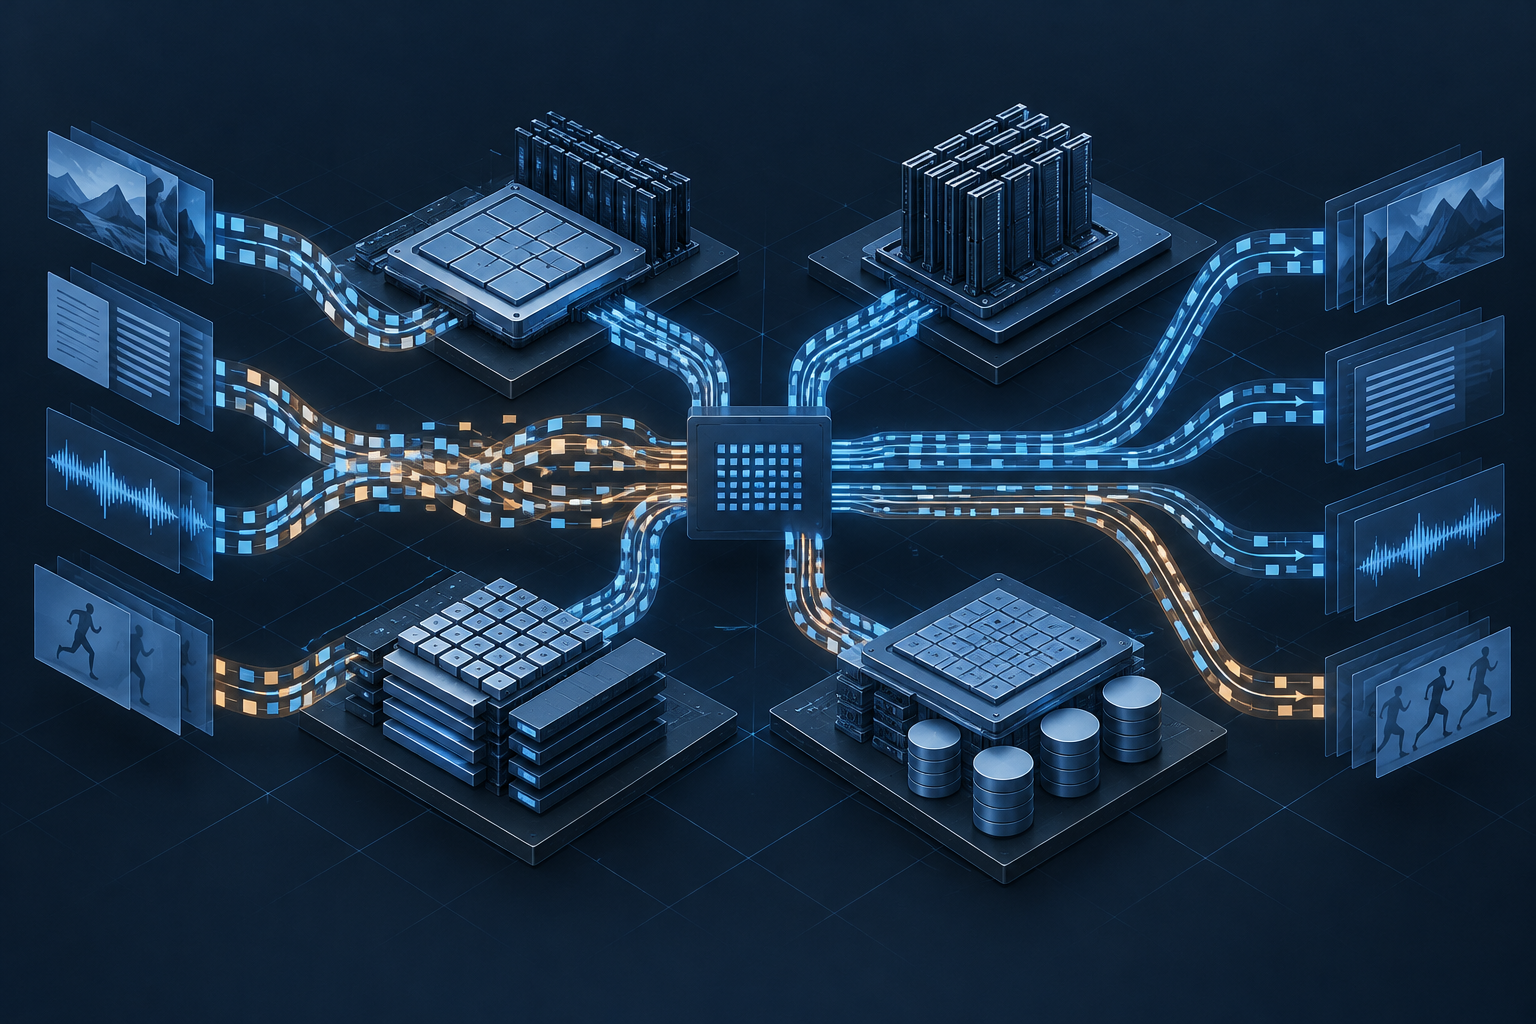
Faster inference is not always a matter of adding compute. A serving system can have substantial arithmetic capacity and still spend too much time moving model weights, accessing intermediate state, or performing avoidable work. Long inputs compound the problem by increasing attention-related computation and the state accessed during generation. When the system contains different processor or accelerator types, optimization must also account for hardware placement.
LLM-CoOpt approaches these constraints as a joint design problem. The framework combines algorithmic optimization with hardware-aware execution on heterogeneous platforms, targeting memory-bandwidth saturation, computational redundancy, and long-sequence processing. Available coverage reports improved throughput and latency without sacrificing model accuracy. [5]
The architectural proposition is worth examining, but the evidence requires restraint. The available summaries do not disclose numerical speedups, evaluated models, hardware configurations, or baseline systems. For engineers and infrastructure buyers, LLM-CoOpt is therefore best understood as a case for coordinated optimization, not yet a quantified basis for changing capacity plans.
1. What LLM-CoOpt Proposes
The paper, LLM-CoOpt: a co-design and optimization framework for efficient LLM inference on heterogeneous platforms, appears in Cluster Computing, volume 29, issue 15, as Article 861. Its listed authors are Jie Kong, Wei Wang, and Chen Yu, and its DOI is 10.1007/s10586-026-06711-8.
The central idea is to optimize what the model computes together with where and how that computation executes. Rather than treating model optimization, runtime execution, and hardware mapping as independent concerns, the framework addresses the algorithmic and hardware sides simultaneously. That joint approach is the defining feature described in the available coverage. [5]
The distinction matters because a local improvement does not necessarily improve the complete request path. Reducing computation may provide little latency benefit if the change creates additional transfers or increases memory pressure. Similarly, assigning work to a more capable processor may disappoint if data movement consumes the time saved during execution.
LLM-CoOpt consequently belongs in a different category from an isolated kernel improvement or a standalone quantization method. Its stated contribution is coordination across layers, rather than a specific reduction in one operator's execution time.
That does not establish which techniques the framework actually implements. The available material does not identify particular scheduling algorithms, pruning methods, fused operators, quantization schemes, or cache-management mechanisms. Those techniques should not be attributed to the paper without further evidence.
For evaluation purposes, the useful starting question is therefore architectural: does a proposed change improve the combined behavior of model computation and hardware execution? A smaller arithmetic workload or a faster device is only part of that answer. The relevant outcome remains the performance of the serving system as a whole.
2. Three Bottlenecks, One Interdependent Problem
LLM-CoOpt identifies three targets: memory-bandwidth saturation, computational redundancy, and long-sequence processing. The value of grouping them is that they interact, even though they describe different sources of inefficiency. [5]
Memory-bandwidth saturation occurs when data movement constrains execution more than arithmetic throughput. Autoregressive generation repeatedly accesses model parameters and intermediate state while producing tokens sequentially. Under those conditions, additional nominal compute capacity does not necessarily translate into additional token throughput.
The available material does not provide a bandwidth ceiling, a device-specific breakdown, or a measured share of execution time attributable to memory traffic. It supports the identification of bandwidth as a target, not a numerical diagnosis of any particular deployment.
Computational redundancy concerns work that does not proportionally improve the generated result. The brief identifies repeated processing, inefficient operator execution, and mismatches between model structure and hardware execution as possible sources. These explain the problem category, but they do not establish which operations LLM-CoOpt removes or reorganizes.
That distinction is important for technical readers. A claim to reduce redundancy is not evidence of pruning, operator fusion, or any particular reduction in FLOPs. The available coverage supports the objective, while leaving the implementation details unresolved. [5]
Long-sequence processing increases attention-related work and enlarges the state accessed during generation. It can also magnify the consequences of poor memory placement and low-bandwidth transfers. An optimization that works well for short inputs may therefore behave differently as context length increases.
Together, these constraints explain why optimizing a single metric can be misleading. Less computation does not guarantee less data movement. Better placement does not eliminate avoidable arithmetic. Long inputs can change which constraint dominates. LLM-CoOpt's stated approach is to treat these relationships as part of the optimization problem rather than as independent tuning exercises.
3. Why Heterogeneous Hardware Raises the Stakes
Heterogeneous inference involves resources with unequal compute capability, memory capacity, and bandwidth. Unlike a deployment tuned around one accelerator family and execution profile, a mixed system introduces choices about where operations run and how intermediate data moves between devices.
The key trade-off is straightforward: a device may execute a piece of work more efficiently, but reaching that device has a cost. If transfers or synchronization outweigh the execution benefit, apparently better placement can make the complete request slower.
LLM-CoOpt's relevance comes from framing algorithmic choices and hardware execution jointly. Its deployment target is explicitly heterogeneous, rather than a single uniform accelerator environment. [5] That framing makes workload characteristics part of hardware mapping, and hardware properties part of algorithmic optimization.
Consider the evaluation logic without assuming a particular LLM-CoOpt implementation. A candidate change that reduces arithmetic should also be examined for its effect on memory access and intermediate data. A placement change should be evaluated with transfer costs included. A result measured on short inputs should not automatically be extended to long-context requests.
These are not additional reported findings from the paper. They are practical consequences of the interaction among the bottlenecks it targets.
For infrastructure buyers, the same reasoning argues against evaluating mixed hardware solely through isolated device specifications. Compute capability, memory capacity, and bandwidth describe important resources, but the workload must use those resources effectively. The relevant question is whether the combined system delivers better throughput and latency for the intended requests.
The available evidence does not identify the CPU, GPU, or accelerator configurations evaluated by LLM-CoOpt. It therefore cannot establish which hardware combinations benefit, which mappings are preferred, or whether a particular fleet should become more heterogeneous. The framework's target environment should not be mistaken for a purchasing recommendation.
4. What the Reported Results Establish
Available coverage reports measurable improvements in throughput and latency without sacrificing model accuracy. These are meaningful outcome categories, but the summaries do not provide enough detail to assess the size or generality of the gains. [5]
Throughput describes completed requests or generated tokens over time. Latency describes the time required to process a request or generate output. Both matter to serving performance, but an evaluation needs precise definitions and workload conditions before its results can support a deployment decision.
Accuracy preservation is similarly important and similarly under-specified here. The reported claim is that performance improvements do not sacrifice model accuracy. The available material does not name the accuracy benchmarks, evaluation datasets, or acceptance criteria. It therefore does not establish that every workload or application-level quality requirement would remain unaffected.
The most consequential omissions are:
- Numerical throughput gains and latency reductions.
- Evaluated model names and baseline serving systems.
- CPU, GPU, or accelerator configurations.
- Sequence lengths and batch sizes.
- Accuracy benchmarks and evaluation datasets.
- Separate evidence for prefill and decode behavior.
These omissions leave the reported result unquantified in the available material. They limit what a reader can conclude from it. A qualitative claim of improved performance is not a multiplier that can be applied to an existing fleet's capacity.
The available evidence also does not establish that gains apply equally to prefill and decode. Teams should avoid treating a general inference improvement as proof that every phase benefits to the same extent.
The defensible conclusion is narrow: LLM-CoOpt is reported to improve throughput and latency while preserving accuracy, but the available summaries do not expose the measurements needed for independent comparison or capacity planning. Its architectural motivation is clearer than its deployment economics.
5. Where Co-Design Fits Among Inference Optimizations
Inference optimization includes several approaches that target different parts of the execution path. Quantization can reduce parameter movement. Speculative decoding can reduce the number of expensive target-model steps. KV-cache methods can reduce memory footprint or attention work. Kernel-level changes can improve execution efficiency.
LLM-CoOpt's stated emphasis is different: it addresses the interaction among model computation, memory behavior, and hardware execution. Available coverage describes an approach spanning algorithmic and hardware optimization rather than a single isolated mechanism. [5]
This distinction should not become an unsupported claim of superiority. The evidence does not establish that LLM-CoOpt outperforms dedicated quantization, KV-cache compression, speculative decoding, or sparse-attention methods. It also does not establish that the framework incorporates those techniques.
The more useful comparison is about scope. A specialized method asks whether a particular source of work or data movement can be reduced. A co-design approach asks how algorithmic choices behave when executed on particular hardware resources, including the costs introduced elsewhere in the system.
Those perspectives need not be treated as competing categories. For evaluation, however, their relationship must be demonstrated rather than assumed. A framework should be compared with a relevant baseline, and any interaction with existing optimizations should be measured explicitly.
This is especially important for long-context workloads. A strategy tuned for short prompts may not remain effective when attention-related work and state access become more prominent. Because LLM-CoOpt identifies long-sequence processing as a core target, sequence length belongs near the center of any assessment, not in a footnote. [5]
The broader lesson is about evidence across layers. An operator-level improvement can explain a mechanism, but it does not by itself establish a serving-level benefit. Conversely, an end-to-end gain is more useful when the evaluation shows which algorithmic and hardware interactions produced it.
6. Turning the Proposal Into an Evaluation Plan
Teams interested in LLM-CoOpt should treat the missing benchmark details as an evaluation checklist. The objective is not simply to reproduce a favorable result, but to determine whether the proposed coordination helps the workloads and hardware they operate.
First, establish the comparison conditions. Identify the model, hardware configuration, baseline serving system, sequence lengths, and batch sizes. These are all absent from the available summaries, and each is necessary to interpret a performance claim. A comparison without those conditions cannot show whether a result transfers to a different deployment.
Second, define throughput and latency precisely. State whether throughput is measured in requests or generated tokens, and what interval the latency measurement covers. Where the evaluation permits, examine prefill and decode separately rather than assuming a combined result describes both phases equally.
Third, inspect the complete execution path. Since co-design is meant to coordinate computation and hardware execution, the assessment should include data movement and synchronization. An isolated computation improvement is insufficient if its benefits disappear when intermediate state crosses device boundaries.
Fourth, vary sequence length deliberately. Long-sequence processing is one of the framework's stated targets. [5] An evaluation restricted to short inputs would leave a central part of the proposal untested. Teams should check whether the same strategy remains useful as the workload's context requirements change.
Fifth, verify quality using explicit criteria. The reported preservation of accuracy is encouraging, but it does not replace evaluation against the team's requirements. The benchmark or dataset and the acceptance criteria should be visible alongside the performance results.
Finally, preserve the boundary between observation and projection. A measured gain on one configuration supports a conclusion about that configuration. Extending it to other models, devices, or workloads requires further evidence. This discipline is particularly important when the framework's purpose is to account for hardware and workload differences.
7. What This Means for Teams Running Their Own Inference Infrastructure
For teams operating their own inference infrastructure, LLM-CoOpt offers a useful architectural proposition: optimize model computation and hardware execution together. Its three stated targets cover distinct but connected sources of serving inefficiency, and its heterogeneous setting makes the costs of placement and data movement central to the problem. [5]
The immediate implication is not that teams should replace their serving stack or purchase different accelerators. The available evidence cannot support either decision. It is that optimization work should be judged against the complete request path rather than an isolated compute metric.
In practice, teams can apply that principle when reviewing any proposed change. Ask whether reduced arithmetic also changes memory behavior. Ask whether moving work improves execution after transfer costs are included. Ask whether long inputs alter the result. Require performance claims to specify the workload, hardware, baseline, and quality evaluation.
For buyers, the same questions help separate an architectural advantage from an unverified capacity claim. A framework that coordinates mixed resources may be relevant to an existing fleet, but its value must be demonstrated on representative conditions before it informs procurement or provisioning.
LLM-CoOpt's reported throughput, latency, and accuracy outcomes make it worth examining. The missing quantitative evidence prevents a stronger conclusion. Without detailed benchmarks in the available material, the most actionable lesson is methodological: treat computation, memory movement, sequence length, and hardware placement as one connected optimization problem, then measure whether the complete system improves.
Sources
- [1]Exploiting the Flexibility of LLM Inference for Frequency Regulation Service
- [2]Scaling LLM Inference via Parallelism: Throughput-Latency Trade-off
- [3]Technical Languages
- [4]EdgeWise: Bringing Long-Horizon Agents to the Edge via ...
- [5]New Co-Design Framework Speeds Up LLM Inference on Mixed Hardware by Taming
- [6]Energy Consumption Analysis of Discrete Diffusion and Autoregressive Language Models
- [7]Next-Concept Modeling (NCM): A New Approach to AI Language Generation
- [8]The Frontier of LLM Inference: Our Latest Book - Agentic AI
- [9]Latest 20 Papers - October 15, 2026 · Issue #582
Researched from the sources above and fact-checked against them before publishing.
See what this means for your infrastructure.
Book a discovery call and get a benchmark projection for your hardware and model.
SCHEDULE A CALL