LLM Enhancements
MOIRA and the Case for Reading Less KV Cache
MOIRA targets long-context decode costs with adaptive KV-cache reads. Its reported gains are promising, but deployment evidence needs verification.
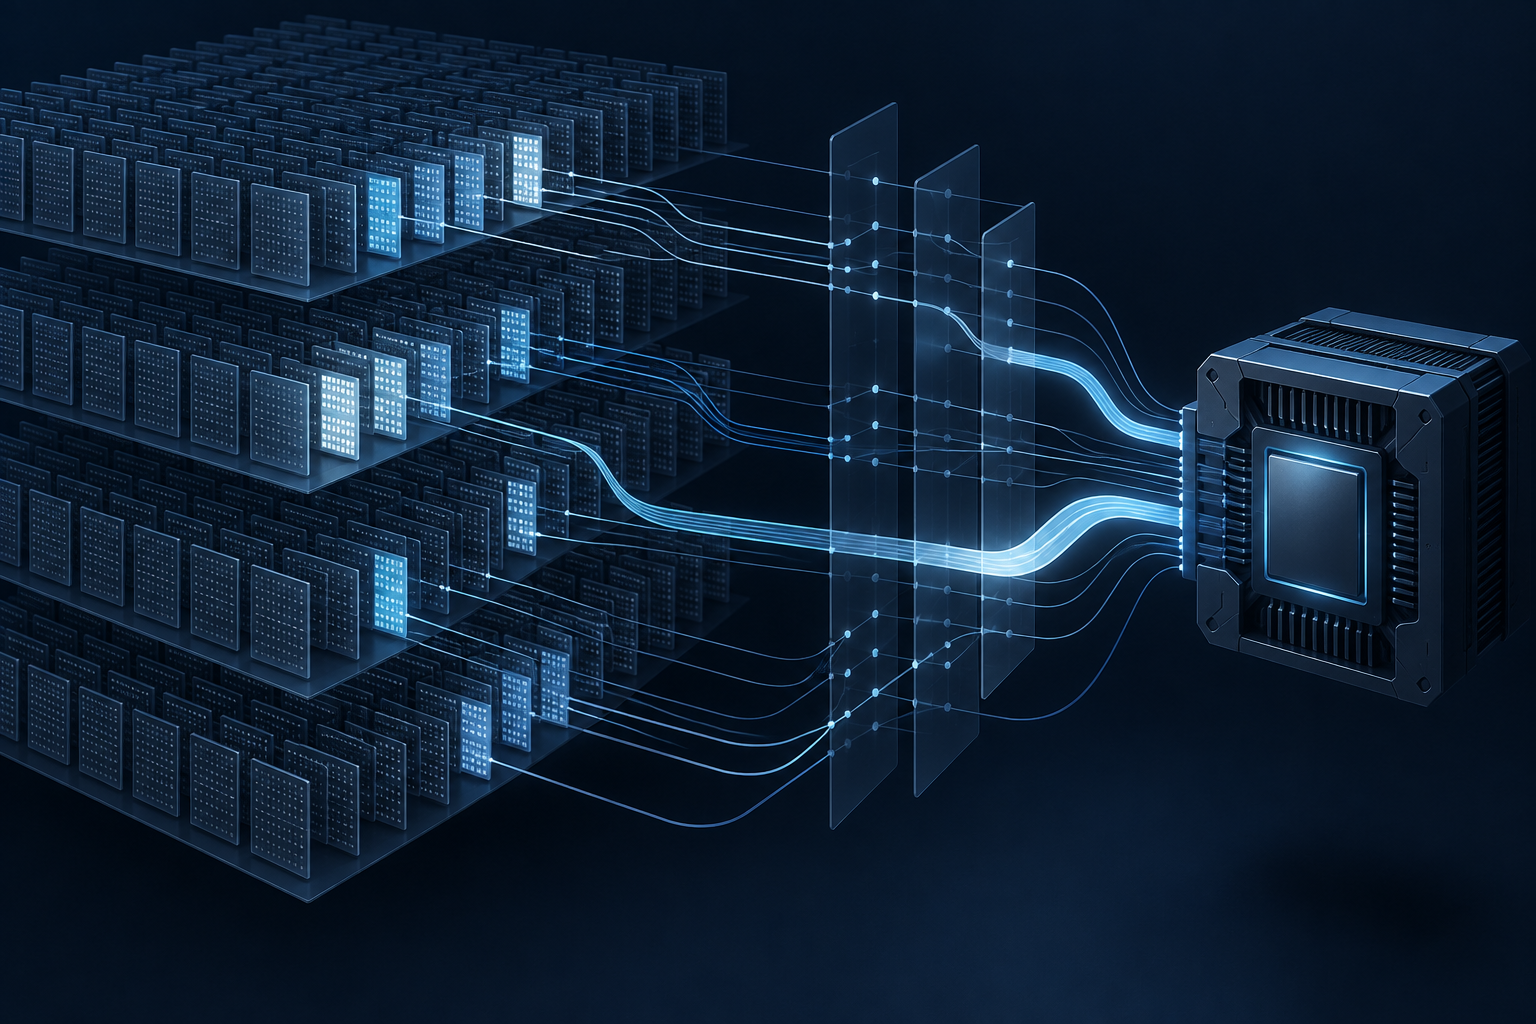
Long-context inference creates a recurring infrastructure expense: every generated token must consult state accumulated during earlier tokens. As that state grows, decoding increasingly depends on moving KV-cache data through GPU memory rather than simply performing more arithmetic. A serving system can have substantial compute capability and still spend much of its decode time accessing memory.
MOIRA, short for Mass-Oriented Indexing with Ragged Attention, targets that access pattern. The supplied research brief describes a training-free sparse-decoding path integrated into vLLM that adjusts the KV-cache read budget independently for each KV head and layer. Rather than reading the entire cache at every step, it selects a smaller set of pages.[10]
The brief reports substantial latency and throughput improvements, but its evidence needs careful handling: most performance claims cite reference [11], whose listed title is not the MOIRA paper. Reference [10] identifies MOIRA. That mismatch does not establish that the results are wrong, but it does mean they should be treated as reported, pending verification against the correct paper.
For engineers and infrastructure buyers, the useful question is therefore twofold: why might this design improve serving efficiency, and what evidence would justify deploying it?
1. The optimization target is cache traffic, not just cache capacity
KV-cache optimization covers several distinct problems. One is capacity: how much memory is required to retain the keys and values associated with a context. Another is access cost: how much of that retained state must be read to generate the next token. Those problems interact, but they are not interchangeable.
Quantization changes the representation of stored KV data. Eviction removes selected entries. Sparse decoding instead selectively reads retained entries during attention computation. The brief places MOIRA primarily in this third category, describing reductions in pages read rather than a lower-precision representation of the full cache.[10]
That distinction matters when interpreting the headline result. Reading approximately 30% of KV-cache pages does not, by itself, establish that the cache occupies approximately 30% of its original memory. It describes access behavior, not a demonstrated reduction in storage capacity. Infrastructure planning should not translate the reported read fraction into an equivalent increase in the number of contexts that fit on a GPU.
The intended benefit is lower memory traffic and less attention work during decoding. A retained page can remain available without being accessed on every generation step. This differs from permanently discarding an entry to reclaim memory.
It also explains why the approach focuses on long contexts. As the accumulated cache grows, repeatedly accessing all of it becomes more expensive. Selective access attacks that repeated cost directly. The relevant deployment question is not merely whether the cache is large, but whether reading it is a meaningful constraint on the workload's decode performance.
2. Adaptive budgets make sparsity a local decision
A fixed sparsity ratio applies the same broad constraint everywhere: each head or layer receives a predetermined share of the available cache. MOIRA's reported design instead adapts the read budget per KV head and per layer. This is the central distinction between uniform sparsity and the approach described in the brief.[10]
Different attention heads need not use the same parts of a long context. Some can emphasize recent tokens, while others retrieve information from distant positions. Layers can also differ in their attention patterns and sensitivity to omitted entries. A single global ratio cannot express those differences as directly as separate budgets.
The practical idea is to allocate more access where additional pages are useful and less where a smaller selection is sufficient. That does not imply every head can safely operate with a small budget. It means the system need not force every head to use an identical one.
The paper's title identifies the two main concepts: mass-oriented indexing and ragged attention.[10] The brief characterizes the indexing as importance-based selection and the attention execution as capable of handling different read lengths. Together, they connect the selection policy to an execution path that can accommodate uneven work.
There are important limits to what can be explained from this evidence. The brief does not specify the exact indexing algorithm, the page counts selected for individual heads, or the calibration procedure for their budgets. It also reports configurations labeled by gamma without supplying a complete definition of that parameter. Those labels can distinguish reported operating points, but they should not be expanded into an invented mathematical description.
The supported takeaway is narrower and still significant: MOIRA makes sparse access granular across both heads and layers, without requiring additional model training according to the brief.[10]
3. The reported results measure different kinds of improvement
The brief's main evaluation describes an NVIDIA H200 at 128K context on RULER. At gamma = 0.99, MOIRA reportedly matches dense accuracy while reading approximately 30% of KV-cache pages. It reports a reduction in time per output token, or TPOT, by a factor of 2.2 to 2.5 relative to dense FlashAttention-3.[10]
These figures describe a particular operating point, not three independent guarantees. The accuracy result, page-read fraction, and TPOT improvement belong together when evaluating the trade-off. Quoting the latency gain without its context length, hardware, baseline, and accuracy condition would make the evidence appear broader than it is.
A second configuration, gamma = 0.98, reportedly reduces TPOT by a factor of 2.7 while remaining within the noise of dense accuracy on the cited evaluation. The brief does not provide the corresponding fraction of pages read. It would therefore be unsupported to attach the approximately 30% figure to this more aggressive configuration.[10]
The brief also reports a throughput increase of up to 51% under high serving load.[10] That is a separate result from the latency measurements. Faster output tokens for an individual request and higher aggregate serving throughput answer different operational questions. The throughput figure should not be presented as an automatic consequence of the reported TPOT speedup.
There is also a citation problem to resolve before these numbers become procurement or capacity-planning inputs. The brief attributes them to [11], but the source list identifies [11] as Mask-Guided KV Cache Eviction in Block Diffusion Language Models. MOIRA appears under [10]. The supplied material does not reconcile that mismatch.[10][11]
Accordingly, these are reported benchmark results from the brief, not independently verified findings. The MOIRA citations here point to its listed paper, but correcting the reference number does not verify the underlying claims. Even after verification, matching dense accuracy on RULER would remain a benchmark-specific finding rather than proof of unchanged behavior across every production workload.
4. Ragged execution must preserve GPU efficiency
Selecting fewer pages is only part of the systems problem. The serving runtime must execute that selection efficiently enough to preserve the savings. Sparse work can reduce memory traffic while introducing irregular access, variable work sizes, and scheduling overhead.
Dense attention benefits from regular tensor shapes and predictable memory access. Adaptive per-head and per-layer budgets deliberately depart from that regularity. Some attention computations may process longer selections than others, so the implementation must handle uneven workloads without allowing orchestration costs to dominate.
The brief describes a specific mechanism: a kernel that keeps the varying budgets inside the CUDA graph.[10] CUDA graphs capture and replay GPU workloads with reduced CPU launch overhead. Keeping adaptive budgets within that execution structure is relevant because dynamic sparsity could otherwise require more expensive per-step coordination.
This is where the serving integration becomes as important as the selection policy. A method can identify a compact set of useful pages yet fail to improve request performance if obtaining and processing that selection costs too much. Conversely, efficient execution can make a more flexible policy practical.
The reported high-load throughput improvement is relevant evidence for this systems claim.[10] As described, it suggests that the sparse execution path retained enough efficiency to improve aggregate serving performance in the tested conditions. It does not reveal exactly how that benefit changes with batch size or across other workloads.
For an engineering evaluation, indexing and sparse attention should therefore be measured as part of the complete decode path. Looking only at the amount of attention work skipped would miss the question MOIRA is intended to answer: does adaptive access make the serving system faster after accounting for the machinery needed to support it?
5. Sparse access is distinct from other KV-cache strategies
The surrounding research illustrates why KV-cache optimization should not be treated as one interchangeable category. Different methods change different aspects of retained state, and their reported speedups may use different baselines or measurement boundaries.
SlimKV combines token-and-feature KV-cache compression with beacon memory states and latent KV representations. The brief reports up to 7.34 times attention speedup and 3.38 times end-to-end decoding speedup over an uncompressed model at 128K length.[4] Its mechanism concerns compressed representations, whereas MOIRA's reported mechanism centers on selective page access.
Those numbers should not be used to rank the methods directly. An attention speedup, an end-to-end decoding speedup, and a TPOT comparison against dense FlashAttention-3 are not automatically equivalent measurements. The supplied evidence does not establish a controlled comparison between SlimKV and MOIRA.
DeferKV changes the timing of eviction. According to the brief, it moves the decision from the end of prefill to the first real decoding step, combining prompt-side and decode-side observations.[3] That addresses when the system decides which cache entries to remove. MOIRA instead determines which retained entries to access during sparse decoding.
BreadthKV approaches decode-time compression as a trade-off between precision and token coverage. The brief describes a combination of quantization and eviction, with bit width selected using a 60-problem end-to-end calibration.[9] Again, this is a different intervention from varying read budgets across heads and layers.
For infrastructure teams, the distinction prevents a category error. A method that reduces stored bytes, one that removes entries more selectively, and one that skips reads can all target long-context cost without offering the same deployment properties. The brief does not establish that these approaches can be combined with MOIRA, nor does it quantify any combined benefit.
6. Deployment readiness requires more than a benchmark headline
The reported vLLM integration makes MOIRA operationally relevant.[10] It places the described work in an established serving framework rather than only in an isolated attention experiment. However, integration alone does not establish that operators can adopt the implementation without additional engineering or compatibility checks.
The brief does not identify an exact vLLM commit, a license, or whether the implementation is publicly released. It also does not establish hardware support beyond the reported H200 evaluation. Those are basic deployment facts that need verification before a team can assess maintenance burden or infrastructure fit.
Several evaluation details are missing as well. The supplied evidence does not identify the tested model families or batch sizes. It reports a high-load throughput improvement without enough detail to reconstruct that load test. These gaps limit how confidently an operator can transfer the result to an existing service.
A useful verification sequence starts with the source mapping. Confirm that the MOIRA paper supports the stated configurations and results, then inspect the implementation and its requirements. Only after those checks does it make sense to compare the method against the team's current serving configuration.
The comparison should preserve the distinctions in the original claims. Measure page reads separately from allocated cache memory. Evaluate TPOT separately from aggregate throughput. Assess task quality alongside speed, including whether more aggressive settings change the acceptable operating point.
These are not objections to sparse decoding. They are the checks needed to turn an interesting systems result into a deployment decision. The benchmark conditions are specific enough to motivate investigation, but the available evidence is not complete enough to support a universal performance multiplier.
7. What this means for teams running their own inference infrastructure
MOIRA's most useful architectural lesson is that KV-cache retention and KV-cache access can be treated as separate decisions. Keeping information available does not necessarily require reading all of it at every decode step. Adaptive sparse access attempts to exploit that distinction while preserving the flexibility to spend more bandwidth where it matters.
For teams serving long contexts, this creates a focused evaluation opportunity. If decode performance is constrained by KV-cache access, a training-free sparse path could address the bottleneck without requiring model retraining. If the dominant concern is instead the memory capacity needed to retain contexts, the reported page-read reduction should not be mistaken for a demonstrated capacity solution.
A practical assessment should proceed through three gates:
- Verify the evidence. Resolve the mismatch between references [10] and [11], confirm the reported benchmark conditions, and establish implementation availability, licensing, and supported configurations.
- Reproduce the relevant behavior. Test representative models, context lengths, and serving loads. Keep latency, throughput, cache allocation, and task quality as separate measurements rather than collapsing them into one speedup claim.
- Decide at the workload level. Determine whether the observed gains survive the team's actual operating conditions and justify the integration and maintenance work. Do not apply the reported maximum throughput improvement as a blanket capacity assumption.
Infrastructure buyers should ask for the same evidence. A claim of fewer cache reads is informative, but its business value depends on measured serving behavior and acceptable output quality. A claim of vLLM integration is useful, but it does not replace confirmation of the release and environment that will actually be supported.
The brief presents a promising direction: per-head, per-layer sparsity coupled to GPU execution designed to handle variable budgets efficiently. Its reported results justify attention, not automatic adoption. For operators, the next step is a correctly sourced, workload-specific evaluation that establishes whether reading less KV cache delivers a reliable improvement in their own serving stack.
Sources
- [1]BitNest: Bit-Nested Speculative Decoding for Memory-Efficient LLM Inference Acceleration
- [2]InferOpt: Constrained Multi-Objective Search for LLM Inference Configurations
- [3]DeferKV: Rethinking Eviction Timing for One-Shot KV Cache Compression
- [4]SlimKV: Joint Token-Feature KV Cache Compression with Reconstruction-Free Beacon Attention
- [5]Tailoring the Quantization Space for 1-Bit KV Cache Compression
- [6]Secure Speculative Decoding for Large Language Models
- [7]APEX: Speculate smarter, not deeper
- [8]Characterizing Parallelism Strategies in LLM Inference: Fundamental Compute-Communication Trade-offs
- [9]Spend Bytes on Breadth: Precision-Count Trade-offs for Decode-Time KV Compression in Long Chain-of-Thought Reasoning
- [10]MOIRA: Mass-Oriented Indexing with Ragged Attention for Long-Context Decoding
- [11]Mask-Guided KV Cache Eviction in Block Diffusion Language Models
- [12]LLM inference · Briefings - Meta Agent Tools
- [13]The KV Cache Is the New Memory Wall | Jaehun's Blog
- [14]DLoop: Looped Speculative Decoding
- [15]HBF for High-Throughput LLM Serving (UC Berkeley, FuriosaAI)
Researched from the sources above and fact-checked against them before publishing.
See what this means for your infrastructure.
Book a discovery call and get a benchmark projection for your hardware and model.
SCHEDULE A CALL