
LLM Enhancements
Morph: Making Request-Adaptive LLM Execution Work for Serving
Morph pairs request-specific attention and SSM execution with selective batching and prefix caching, reporting up to 3.87× higher throughput.
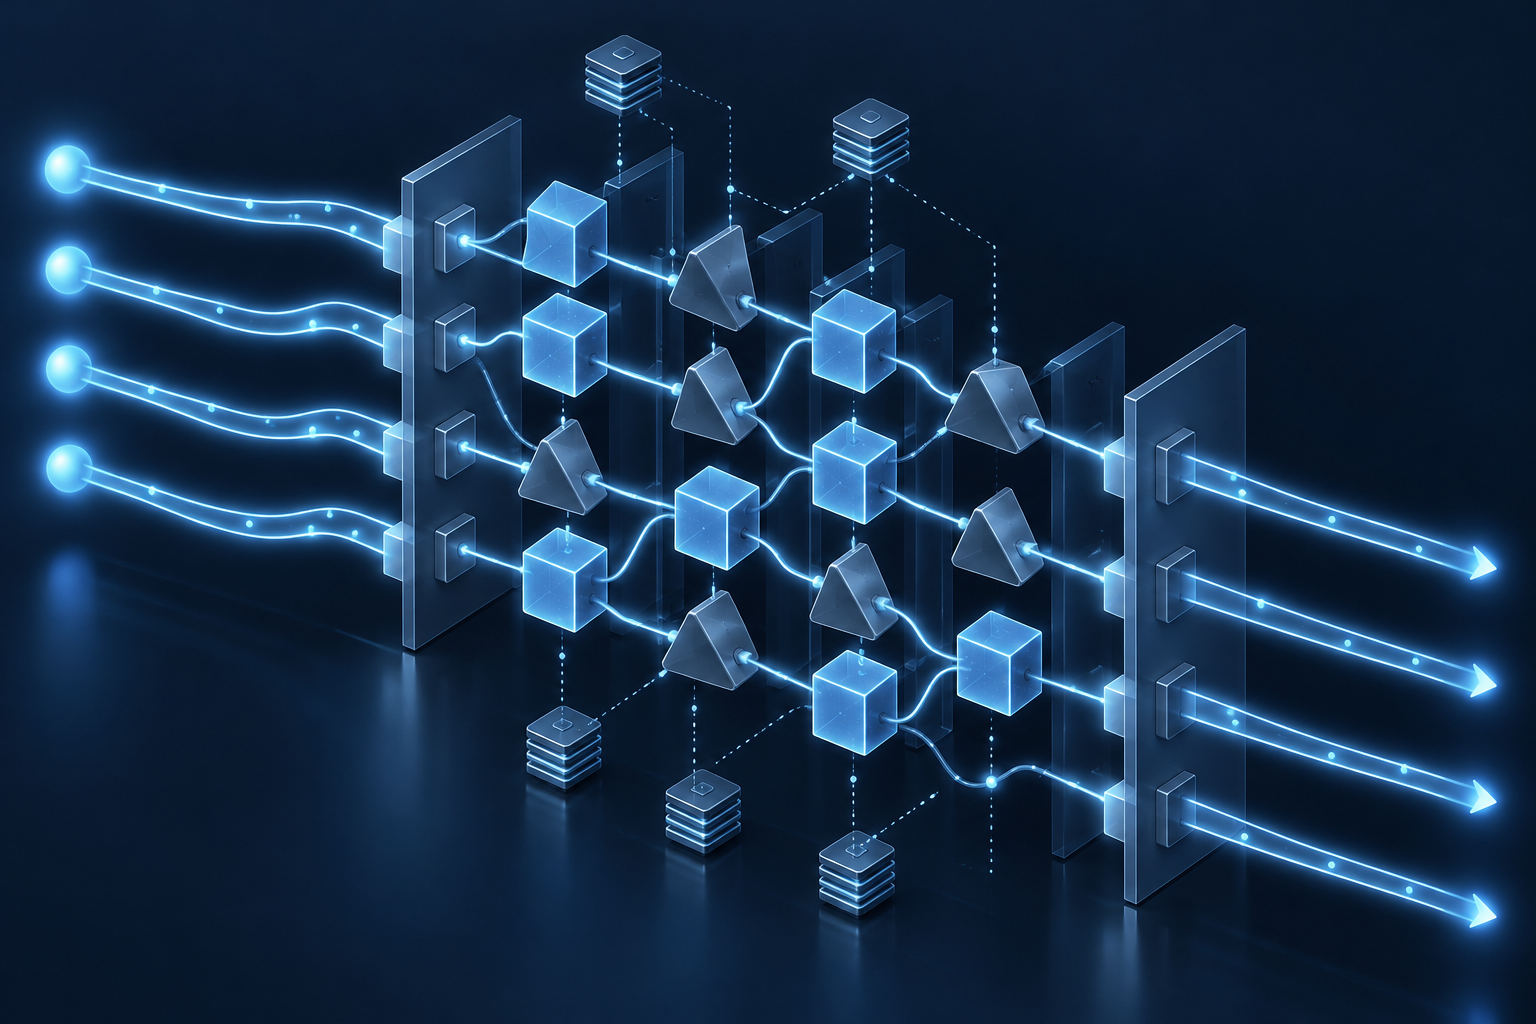
An inference optimization has to survive contact with the serving runtime. Reducing computation is not enough if the resulting execution paths undermine batching or make cached context unsafe to reuse. Morph, a system for request-adaptive hybrid LLM inference, addresses those concerns together: model execution, batching efficiency, and cache correctness.[2]
The paper, “Request-Adaptive Execution for Efficient Hybrid LLM Inference,” describes a model that combines attention and state-space-model (SSM) layers within each block. During prefill, the system selects a request-specific layout. That layout stays fixed during decoding, while selective batching and hybrid-aware context caching support execution across requests with different layouts.[2]
The reported results are promising: a better quality-efficiency trade-off than static hybrid baselines across six datasets, plus up to 3.87× higher serving throughput over baselines and substantially lower inference latency. The available evidence does not establish the hardware, workload, or operating point behind that throughput result. For infrastructure teams, the useful lesson is therefore both architectural and practical: request-level adaptation needs a runtime designed to accommodate it.[2]
1. From a fixed architecture to a request-specific execution plan
Hybrid language models bring together sequence-processing architectures with different computational strengths. A fixed hybrid architecture, however, still sends every request through the same arrangement of layer types. Requests may differ, but their execution structure does not.[2]
Morph changes that arrangement at the request level. Its model combines attention and SSM layers within each block, and its prefill-oriented gating selects a suitable layout for the incoming request. The result is not simply a hybrid model with a predetermined mix of computation. It is a model and serving system designed around request-specific architectural choices.[2]
That distinction defines the contribution. A static hybrid baseline can already combine attention and SSM computation. Morph asks whether the combination should remain identical for every request, and whether allowing it to vary can improve the balance between output quality and inference efficiency. The paper reports a better quality-efficiency trade-off than existing static hybrid baselines across its six-dataset evaluation.[2]
The available source does not explain the exact selection algorithm. It does not provide the gating-network size, the number of possible layouts, or the attention-to-SSM ratios. It would therefore be premature to describe Morph as selecting a particular number of layers, skipping a known fraction of computation, or applying a specific routing formula.
What is established is the execution boundary: the request receives a layout during prefill, and decoding retains that layout. This makes the architecture adaptive across requests without repeatedly changing it as each request generates tokens. The serving mechanisms are built around that distinction.[2]
2. Why Morph makes its architectural choice during prefill
Prefill and decoding impose different requirements on an inference system. Prefill processes the input context. Decoding generates tokens incrementally, making synchronization, batching, and reuse sensitive to runtime variability. Morph places its architectural decision in the first phase and carries the decision into the second.[2]
During prefill, the system can use the complete input request to determine an execution plan. Its prefill-oriented gating selects the request-specific arrangement of attention and SSM layers. Once generation begins, that arrangement remains fixed, rather than being reconsidered for every generated token.[2]
This is a useful way to separate adaptation from repeated execution. The system still has to serve requests with different layouts, but it does not also have to accommodate a new architectural choice at each decoding step. Keeping the layout stable removes that particular source of variation while preserving request-level flexibility.[2]
It is important not to confuse architectural stability with an absence of serving complexity. Different requests can still follow different paths. Fixing each path before decoding does not make all requests compatible with the same execution group. It gives the runtime a stable request-specific structure to work with, while leaving the cross-request coordination problem to selective batching.[2]
Nor does the brief establish that gating is free. It provides no gating-overhead measurements or detailed breakdown of time spent selecting layouts. Infrastructure buyers should treat that as an evaluation question, not assume that architectural choice has negligible cost.
The defensible claim is narrower: Morph avoids making a fresh architectural decision at every generated token. Its design deliberately places selection during prefill and preserves the selected layout throughout decoding.[2]
3. Selective batching addresses the cost of divergent paths
Batching becomes harder when requests no longer execute identical layer sequences. In conventional serving, requests in a batch generally traverse the same model layers in the same order. Request-adaptive execution breaks that uniformity: one request's selected hybrid layout can differ from another's.[2]
Naively grouping such requests can reduce hardware utilization or require separate execution streams. A model-level efficiency gain can consequently create a serving-level coordination problem. The relevant question is not only whether a request needs less computation, but whether the runtime can execute the resulting mix of requests efficiently.[2]
Morph addresses this with selective batching, which the paper describes as preserving batching efficiency despite divergent layer choices. Its role is to support compatible work without forcing every request through every layer type. This is a serving mechanism tied directly to the model's request-adaptive execution structure.[2]
The available evidence does not reveal how that grouping works. There is no exact batching algorithm, scheduling policy, batch dimension, or GPU kernel implementation in the provided coverage. It would be unsupported to claim that Morph uses a particular queue structure or fuses specific operations.
Those omissions also limit how far the reported throughput can be generalized. Without the scheduling details and workload configuration, the brief cannot establish how Morph behaves as layout diversity or request concurrency changes. These are questions for further evaluation, not demonstrated weaknesses or strengths.
For engineers, selective batching is the bridge between architectural flexibility and shared execution. For buyers, its presence is a reason to evaluate Morph as a complete serving design rather than treating its gains as something attributable solely to a different model architecture. The paper's contribution explicitly includes both.[2]
4. Hybrid-aware caching makes prefix reuse a correctness problem
Repeated context is a familiar feature of LLM serving. Requests can share system prompts, retrieved documents, conversation prefixes, or task instructions. Prefix reuse avoids recomputing shared context, making cache behavior an important part of inference efficiency.[2]
Request-specific architectures complicate that reuse. A cached representation produced under one execution layout may not be valid under another. Matching input text alone does not resolve the compatibility issue described in the brief, because the selected computation also matters.[2]
Morph introduces hybrid-aware context caching to enable correct prefix reuse. The essential point is correctness under request-dependent execution: the cache system accounts for the hybrid configuration rather than assuming that cached context is interchangeable across layouts.[2]
This is more than an auxiliary performance feature. If request adaptation changes the computation used to process a prefix, the runtime needs a way to determine when previously computed context remains reusable. Morph treats that requirement as part of the serving design, alongside gating and selective batching.[2]
The brief does not specify the cache key, storage granularity, eviction policy, or memory footprint. It also does not say whether attention states and SSM states occupy identical or separate structures. None of those details can be reconstructed from the throughput result.
That boundary matters when considering deployment. Correct reuse and frequent reuse are different questions. The source establishes that Morph supports correct prefix reuse, but it does not quantify cache hit rates for particular traffic patterns or the memory cost of retaining reusable context.
A useful evaluation would therefore examine both compatibility and benefit: when can shared prefixes be reused under the selected layouts, and how much work does that reuse actually save? Those questions follow from Morph's design without assuming implementation details that the brief does not provide.
5. Reading the throughput and quality results without overclaiming
Morph's reported evaluation has two important components. Across six datasets, it achieves a better quality-efficiency trade-off than existing static hybrid baselines. In its system-level evaluation, it reports up to 3.87× higher serving throughput over baselines, together with substantially reduced inference latency.[2]
The quality-efficiency comparison matters because reducing computation alone is not sufficient evidence of a better inference system. A deployment decision also needs to account for the quality of generated outputs. The reported trade-off supports evaluating adaptation on both dimensions, although the brief does not provide per-dataset quality scores.[2]
The throughput claim requires equally careful wording. “Up to 3.87×” is a reported upper-bound improvement, not a universal multiplier. The available coverage does not identify the workload, hardware configuration, batch size, or latency target associated with that figure. It also does not provide baseline names and configurations.[2]
Consequently, the brief cannot support a projection of absolute tokens per second, requests per second, or infrastructure savings. A relative throughput result without its operating conditions is not enough to calculate a deployment's required capacity or expected cost reduction.
The latency result is similarly directional. The paper reports substantially lower inference latency, but the available source contains no absolute latency measurements or median, P95, or P99 values. Teams should not reinterpret that statement as evidence about a particular latency percentile or service-level target.[2]
Other missing details include model parameter count, context lengths, output lengths, hardware type, and GPU count. Their absence does not invalidate the reported result. It limits the conclusions that can responsibly be drawn from this brief.
The strongest supported reading is that Morph demonstrates a promising system-level approach: request-adaptive hybrid execution can be paired with batching and caching mechanisms, and the paper reports better serving performance over its baselines. Whether the same advantage holds for a particular deployment remains an evaluation question.[2]
6. The broader lesson is model-runtime co-design
Morph fits a broader direction in inference infrastructure: model execution and serving mechanisms are increasingly treated as coupled design problems. The supplied cloud LLM systems survey includes iteration-level continuous batching, prefill-decoding disaggregation, and hierarchical KV-cache offloading in its taxonomy. Morph's specific contribution is request-adaptive hybrid execution, not a claim to introduce those other techniques.[1][2]
Its design links three decisions. Gating determines the request's attention/SSM layout. Selective batching handles divergent execution paths. Hybrid-aware caching preserves correct prefix reuse. Each mechanism addresses a consequence of allowing the architecture to vary across requests.[2]
That relationship is the central systems insight. Architectural adaptation cannot be evaluated only by looking at the computation chosen for an isolated request. The request will share execution resources with other requests, and its context may overlap with previously processed input. Morph brings those serving constraints into the design rather than leaving them outside the model-level optimization.[2]
The distinction is particularly relevant to mixed workloads, where requests differ in input length, output length, shared-prefix reuse, and latency requirements. A static hybrid architecture exposes the same execution structure to all requests. Morph instead selects a request-specific structure while attempting to retain the operational benefits of batching and reuse.[2]
The brief does not establish which request characteristics drive each gating decision. It would therefore be inappropriate to claim that a particular context length or latency requirement directly selects a particular layer mix. Workload diversity explains the relevance of adaptation, but it does not reveal the gating policy.
For technical evaluation, the implication is to examine the complete chain. Layout selection, batching behavior, and cache compatibility belong in the same analysis, because Morph presents them as parts of one serving system.[2]
7. What this means for teams running their own inference infrastructure
For teams operating their own inference stack, Morph is a reason to investigate request-adaptive execution, not a ready-made capacity forecast. The paper reports encouraging results, but the available evidence leaves important deployment variables unspecified.[2]
Start by asking for the experimental configuration behind the claims: model size, hardware, baseline settings, input and output lengths, concurrency, and latency targets. Those details are necessary to judge whether the reported comparison resembles your environment. The brief does not supply them.
Next, evaluate quality and serving behavior together. A useful deployment test should examine whether the quality-efficiency trade-off holds on representative tasks, while measuring throughput at the latency targets the service actually needs to meet. This is a recommended evaluation approach, not a claim about measurements available in the brief.
Prefix reuse deserves its own scrutiny. Workloads with shared context should be tested for both correct reuse and the resulting performance benefit. Ask how layout compatibility affects reuse, what memory the cache requires, and how cache behavior changes across the workload. Morph establishes the need for hybrid-aware caching, but the provided coverage does not answer those operational questions.[2]
Finally, examine the runtime as carefully as the model. Request-specific layouts create divergent work; selective batching is the mechanism intended to preserve batching efficiency. Understanding that interaction is essential before attributing a measured gain to architectural adaptation alone.[2]
The practical takeaway is straightforward: adaptive inference needs coordinated execution, scheduling, and cache semantics. Morph's contribution is to address those concerns together while reporting improved quality-efficiency and serving performance. For infrastructure teams, that makes it a compelling design to investigate, with the 3.87× result treated as a reported experimental upper bound rather than a promise about production capacity.[2]
Sources
- [1]LLMs in Cloud: A Discussion on Architecture, Orchestration, and Inference
- [2]Request-Adaptive Execution for Efficient Hybrid LLM Inference
- [3]Distributed LLM Inference via Communication-Efficient Speculative Decoding
- [4]MCF: A Memory- and Communication-Aware Co-Designed Framework for Long-Context LLM Inference
- [5]Waypoint: Analytically Modeling GEMM for CPUs
- [6]Test-time augmentation for LLMs: Where to inject diversity at inference time
- [7]Efficient Omni-modal Large Language Model Inference via Per-Query Modality Selection, Oriel
- [8]KV Cache Wars: How Compaction, Quantization, and a ...
- [9]Aligning Only Three Rounding Points: BF16 Large-Model Reinforcement Learning No Longer Collapses
- [10]Infra papers, 2026-10-24 · Paper Daily
Researched from the sources above and fact-checked against them before publishing.
See what this means for your infrastructure.
Book a discovery call and get a benchmark projection for your hardware and model.
SCHEDULE A CALL