
LLM Enhancements
MosaicKV and the Case for Scheduling KV Cache Across Tenants
MosaicKV coordinates KV-cache placement, tenant memory allocation, and prefetching. Its architecture is clear; performance gains remain unquantified.
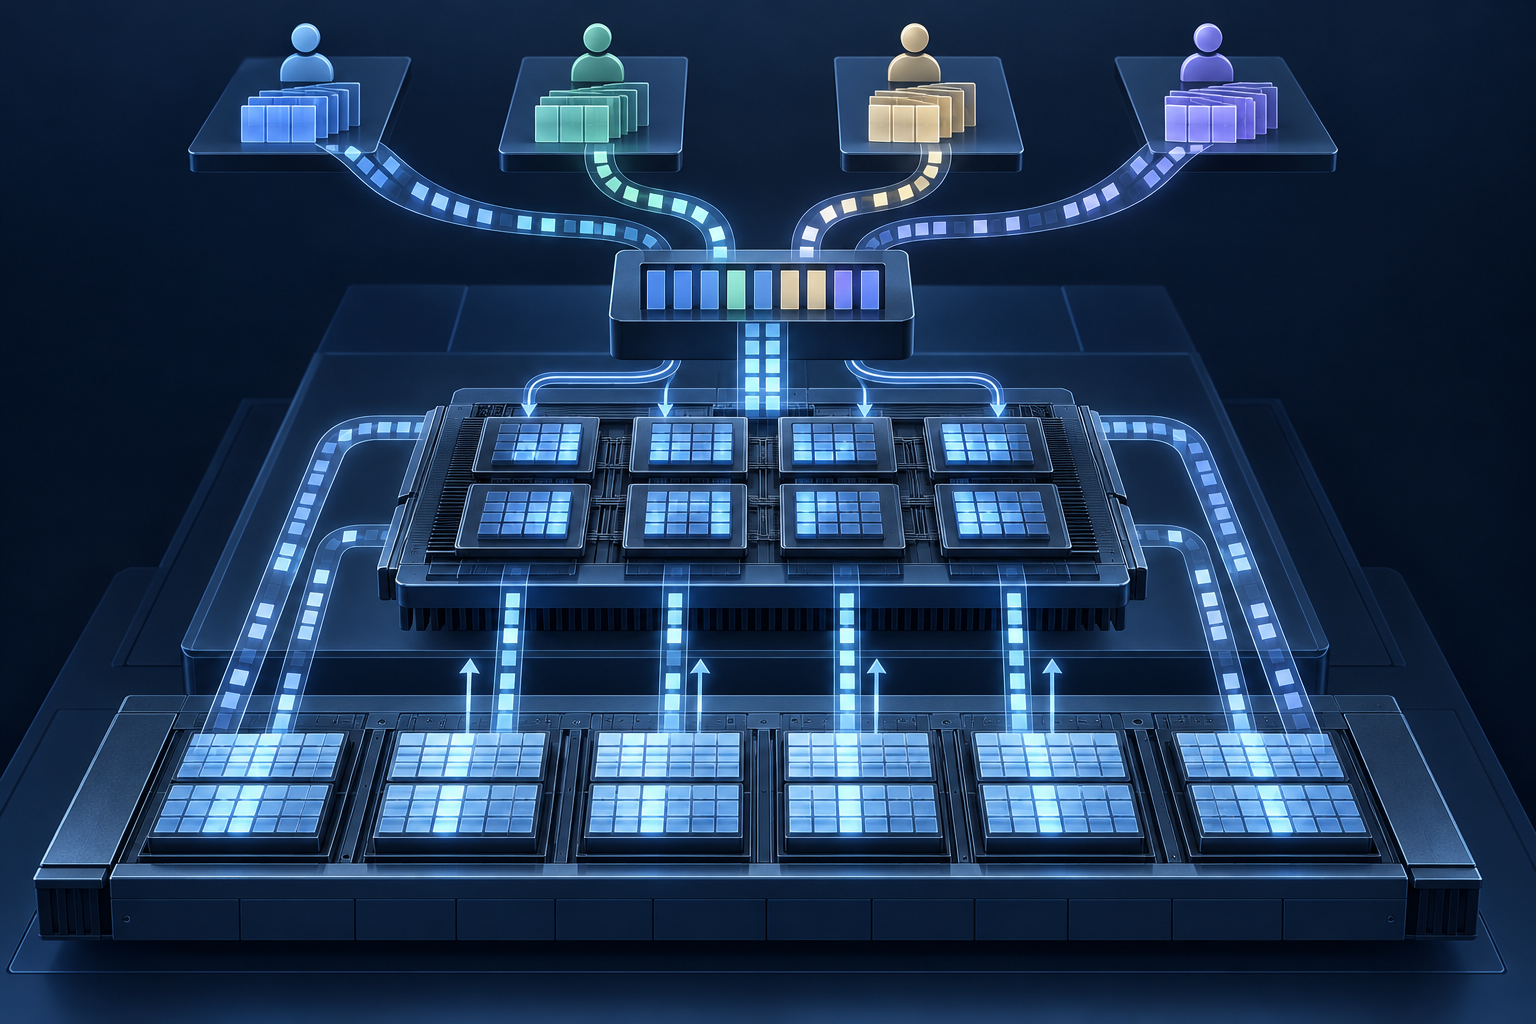
KV cache is often discussed as a capacity problem: how much attention state can fit in GPU memory before an inference server must offload it or change how it serves requests? In a multi-tenant environment, that question is incomplete. The system must also decide whose state occupies GPU memory, which pages can move to host memory, and when transfers can happen without delaying generation.
MosaicKV addresses those decisions together. It introduces a KV-cache virtualization layer for multi-tenant LLM inference on shared GPU servers, exposing cache state as a resource that can be scheduled, migrated, partitioned, and placed across GPU high-bandwidth memory (HBM) and host DRAM. Its central architectural move is to coordinate memory management with inference scheduling rather than treat offload as a separate response to memory pressure.[1]
For infrastructure engineers, this is a useful design direction, but not yet a quantified performance case. The supplied coverage explains the architecture without providing MosaicKV benchmark results. The distinction matters: a credible mechanism for managing shared memory does not establish a particular throughput gain, cost reduction, or latency improvement.
1. Shared KV Cache Turns Capacity Into a Scheduling Problem
During autoregressive generation, the KV cache retains attention keys and values associated with earlier tokens. Keeping that state in GPU HBM avoids recomputing the prompt history. However, the state grows with sequence length and concurrent requests. A workload that needs more cache can therefore consume memory that another tenant could otherwise use.
That creates a resource-allocation problem beyond the needs of any individual request. Multiple tenants share a finite GPU-memory budget, while their request rates, context lengths, and latency requirements vary. Cached prefixes can also have different reuse patterns. A policy that works well for one workload may leave less room for another.
MosaicKV explicitly targets this shared-server setting. Its description says it jointly optimizes GPU-memory partitioning across tenants, rather than treating each tenant's allocation as an independent decision.[1] Cache capacity becomes something the system schedules across competing workloads.
The memory hierarchy adds another dimension. MosaicKV decides which KV pages remain in HBM and which spill to host DRAM.[1] Host memory provides additional capacity, but accessing offloaded state requires movement between host and accelerator. The trade-off is therefore not simply more memory versus less memory. It is more capacity versus the transfer overhead associated with using that capacity.
These decisions interact. Moving one tenant's pages to host memory can make GPU capacity available elsewhere, but those pages may be needed again during generation. The allocation decision has consequences for later execution. MosaicKV's approach recognizes that partitioning memory and scheduling requests cannot be evaluated entirely in isolation.
2. Virtualization Makes Cache State an Explicit Resource
MosaicKV's organizing abstraction is a KV-cache virtualization layer. The layer exposes KV state as schedulable and migratable, allowing the system to reason about where cached state lives and how its allocation should change as workloads evolve.[1]
“Schedulable” means that GPU-memory residency is a policy decision. The system can decide how much capacity each tenant receives and which pages should remain in the faster memory tier. “Migratable” means that placement is not necessarily permanent: cache pages can move between memory locations or allocation contexts as conditions change.
The important contribution is the coordination of several decisions:
- Tenant allocation: how GPU-memory capacity is partitioned across serving tenants.
- Page placement: which KV pages stay in HBM and which reside in host DRAM.
- Prefetch timing: when offloaded pages should move back toward the accelerator.
- Micro-batching: how execution is organized to create opportunities for transfer overlap.
The available description identifies these as parts of MosaicKV's design.[1] Taken together, they make KV management a shared scheduling responsibility rather than a collection of local eviction decisions.
This framing also clarifies what virtualization means here. The architectural claim is about exposing and coordinating state across a memory hierarchy. It does not, by itself, establish a new cache-compression format or a faster physical interconnect. MosaicKV instead attempts to manage existing capacity and transfer opportunities more deliberately.
For an infrastructure buyer, the relevant question becomes whether a serving system coordinates these controls. Supporting host-memory offload alone is not equivalent to scheduling offload alongside execution. Two systems may both place KV state in DRAM while making materially different decisions about when to move it and which requests should run next. MosaicKV's stated design centers on that coordination.[1]
3. Planned Offload Connects Data Movement to Execution
Reactive paging provides a straightforward response to memory pressure: move pages out when capacity becomes constrained, then fetch them when they are needed again. The risk is that a later decode step reaches a missing page before its transfer has completed. At that point, memory capacity has been extended, but execution may wait for data.
MosaicKV's description proposes a different approach. It co-designs page layout with a slack-aware scheduler to turn KV offload into a planned pipeline. It also coordinates prefetch and micro-batching to hide PCIe DMA transfer latency.[1]
The distinction is about timing, not the elimination of transfers. Data still needs to move between host memory and the accelerator. The scheduler attempts to arrange that movement early enough, and alongside useful execution, so that it does not become an exposed delay when a request needs the page.
Slack is central to that idea. The design attempts to use available execution slack to move cache state before it is needed. Whether that opportunity exists is therefore an important evaluation question. A scheduler may have different room to rearrange work depending on the workload and its latency requirements.
Consider an illustrative scheduling decision, not a reported MosaicKV experiment. A tenant has pages in host DRAM, and its next decode step will require them. Other inference work could execute while those pages transfer. If the scheduler can align that work with the transfer, the fetch may be less disruptive than a demand-driven fetch issued only when decoding reaches the missing state.
That example also exposes the limit of the mechanism: arranging overlap and demonstrating overlap are different things. The supplied coverage establishes that MosaicKV plans prefetch and execution together, but it does not report how often transfers are hidden or how much latency remains visible.[1] Those measurements are necessary before translating the pipeline design into a performance claim.
4. Page Layout and Micro-Batching Belong in the Same Discussion
Two details distinguish MosaicKV's architecture from a simple placement policy: page layout and micro-batching. The description says page layout is co-designed with the slack-aware scheduler, while micro-batching is timed with prefetch to hide PCIe DMA latency.[1]
Page layout determines the granularity at which cache state can be retained or moved. Fine-grained pages can offer more placement flexibility, while larger pages may reduce metadata and movement overhead. The useful balance depends on how those units interact with scheduling and transfer decisions.
The supplied source does not provide numerical page sizes or measured page-management overheads. It therefore supports the conclusion that layout is part of the design, but not a claim that MosaicKV uses an optimal granularity or achieves a particular efficiency advantage. That distinction should remain explicit when discussing the architecture.
Micro-batching connects the memory policy to the timing of inference. Changing how work is grouped can change when a request reaches a decode step and how much opportunity exists to overlap transfers with computation. MosaicKV incorporates those timing decisions into cache management rather than treating batching solely as an independent throughput optimization.[1]
This creates an evaluation obligation. If a system changes execution timing to accommodate prefetch, aggregate throughput is not sufficient to explain the outcome. Engineers also need to understand what happened to request latency and whether different tenants experienced different effects.
The design should therefore be read as a coordinated control problem: page layout establishes the units of movement, placement selects their memory tier, prefetch schedules their arrival, and micro-batching helps organize the execution around them. The source describes that integration, but does not include ablations that isolate the contribution of each component.[1]
5. Where MosaicKV Fits in the Inference Stack
Recent inference work addresses several distinct sources of delay and inefficiency. Comparing those efforts is useful for understanding scope, but their reported results should not be treated as interchangeable evidence.
IgniteServe targets serving-engine cold starts. The brief reports startup-latency reductions relative to vLLM of 69.3% for fully cold states and 56% on average across cache-resident states.[2] Those results concern startup behavior, not the ongoing partitioning and placement of KV state across tenants.
Olifant, introduced in Towards Green Text Generation: Memory-Based Speculative Decoding, uses a memory-based classifier as a CPU draft model. Its reported 2.43× throughput result applies to EU legal text with a domain-matched configuration.[3] Its mechanism concerns speculative drafting rather than shared KV-cache virtualization.
Feather is closer to MosaicKV's scheduling concerns. It uses reinforcement learning to trade off batch size against prefix homogeneity.[6] The connection is that batching and cache behavior are related. The distinction is that MosaicKV centers on tenant memory partitioning and KV placement across HBM and host DRAM, coordinated with prefetch and execution.[1]
Agent-session retention is another adjacent problem. When Does Keeping Agent Sessions in GPU Memory Pay studies whether retaining KV state during tool waits is worthwhile.[7] That work focuses on the value of keeping session state resident during pauses, rather than the broader shared-memory abstraction described for MosaicKV.
These comparisons locate MosaicKV within the serving stack without implying a performance ranking. Cold-start acceleration, speculative decoding, prefix-aware grouping, and session retention address different decisions. Their measurements cannot fill the gaps in MosaicKV's evaluation. Its contribution must be assessed on evidence about its own memory-management and scheduling behavior.
6. What the Available Evidence Establishes
MosaicKV appeared in the Proceedings of the 2026 ACM Symposium on Cloud Computing Volume 1 on November 10, 2026, with an update on November 14, 2026.[1] The supplied coverage identifies its target environment, virtualization abstraction, and high-level mechanisms.
That evidence supports a specific architectural conclusion: MosaicKV coordinates multi-tenant GPU-memory partitioning, HBM-versus-DRAM placement, prefetching, and micro-batching through a design that includes a slack-aware scheduler.[1]
It does not support a numerical conclusion about performance. The coverage contains no MosaicKV benchmark tables, baseline names, GPU models, workload sizes, throughput values, latency percentiles, or ablation results. It also does not establish quantified memory savings, cost reductions, or service-level-objective improvements.
For engineers evaluating the approach, the next questions should therefore be concrete:
- Workload conditions: Which tenant mixes, context lengths, concurrency levels, and latency requirements were tested?
- Hardware conditions: What GPU-memory capacity, host-memory capacity, and transfer environment were used?
- Latency distribution: How did individual tenants and tail latencies behave, rather than only aggregate throughput?
- Transfer overlap: How much movement was hidden by useful execution, and how much remained on the request's critical path?
- Component contribution: What changed when coordinated partitioning, prefetch, micro-batching, or page-layout choices were removed?
- Comparative behavior: How did the design compare with GPU-resident caching, compression, or recomputation-based alternatives under the tested conditions?
These are proposed evaluation questions, not descriptions of experiments in the supplied record. Their purpose is to turn the architectural argument into a testable infrastructure decision.
The most important distinction is between extending usable memory capacity and improving end-to-end serving outcomes. A system can make more cache state available without necessarily improving every tenant's latency. MosaicKV provides a coordinated design for addressing that tension, but the available evidence does not establish how successfully it resolves it across workloads.
7. What This Means for Teams Running Their Own Inference Infrastructure
For teams operating shared inference servers, MosaicKV offers a useful way to frame KV-cache management: memory placement, tenant allocation, and execution timing belong in the same operational discussion. Treating them as unrelated tuning surfaces can obscure the consequences of moving state out of GPU memory.
The immediate takeaway is architectural, not a recommendation to adopt an unquantified implementation. A team considering host-memory offload should ask more than whether the serving engine supports it. It should ask how pages are selected, how transfers are scheduled, and whether batching decisions account for when data will be ready.
A practical assessment can follow three tracks. First, characterize the workload mix: which tenants create cache pressure, how context lengths and concurrency vary, and which latency requirements constrain scheduling. Second, examine coordination: whether memory allocation, prefetch, and execution are managed together or through separate policies. Third, require evidence at the tenant level, including latency distributions and behavior under changing demand, before accepting aggregate performance claims.
For buyers, the same framework helps distinguish a feature from a demonstrated outcome. “Host-memory offload” describes a capability. It does not establish successful transfer overlap, predictable tail latency, or a favorable cost result. MosaicKV's architecture makes those distinctions especially relevant because its central claim depends on coordinating decisions over time.[1]
For engineers, the research question is equally clear: can planned offload consistently hide transfer latency without harming tail SLOs? The supplied coverage does not answer that quantitatively, but it identifies the controls that need to work together.
MosaicKV's contribution is to make KV state an explicit shared resource rather than merely per-request GPU data. For teams running their own infrastructure, that is a valuable design principle. Turning it into a deployment decision still requires measurements on the hardware, workload mix, and latency objectives that matter to the service.
Sources
- [1]MosaicKV: SLO-Aware KV-Cache Virtualization for Multi-Tenant LLM Serving in the Cloud | Proceedings of the 2026 ACM Symposium on Cloud Computing Volume 1
- [2]IgniteServe: Accelerating LLM Serving Engine Cold Starts via Fine-Grained Parallelization | Proceedings of the 2026 ACM SIGOPS Annual Technical Conference
- [3]Towards Green Text Generation: Memory-Based Speculative Decoding
- [4]Model-as-a-Service in the Wild: Characterizing Production LLM Inference Clusters at Scale | Proceedings of the 2026 ACM SIGOPS Annual Technical Conference
- [5]Reducing Batch Makespan for LLM Agent Workloads through Inference, Environment Coordination
- [6]Requests of a Feather Must Flock Together: Batch Size vs. Prefix Homogeneity in LLM Inference | Proceedings of the 2026 ACM SIGOPS Annual Technical Conference
- [7]When Does Keeping Agent Sessions in GPU Memory Pay ...
- [8]Formal Framework Cuts LLM Costs by Order of Magnitude
- [9]Infra papers, 2026-11-11 · Paper Daily
- [10]Optimizing Retrieval-Augmented Generation Inference ...
Researched from the sources above and fact-checked against them before publishing.
See what this means for your infrastructure.
Book a discovery call and get a benchmark projection for your hardware and model.
SCHEDULE A CALL