LLM Enhancements
Prism Attention: What a Reported 3.4× Decode Speedup Means for Long-Context Inference
Prism Attention reports 3.4× faster decoding at 128K context. Here is what infrastructure teams should evaluate before adopting it.
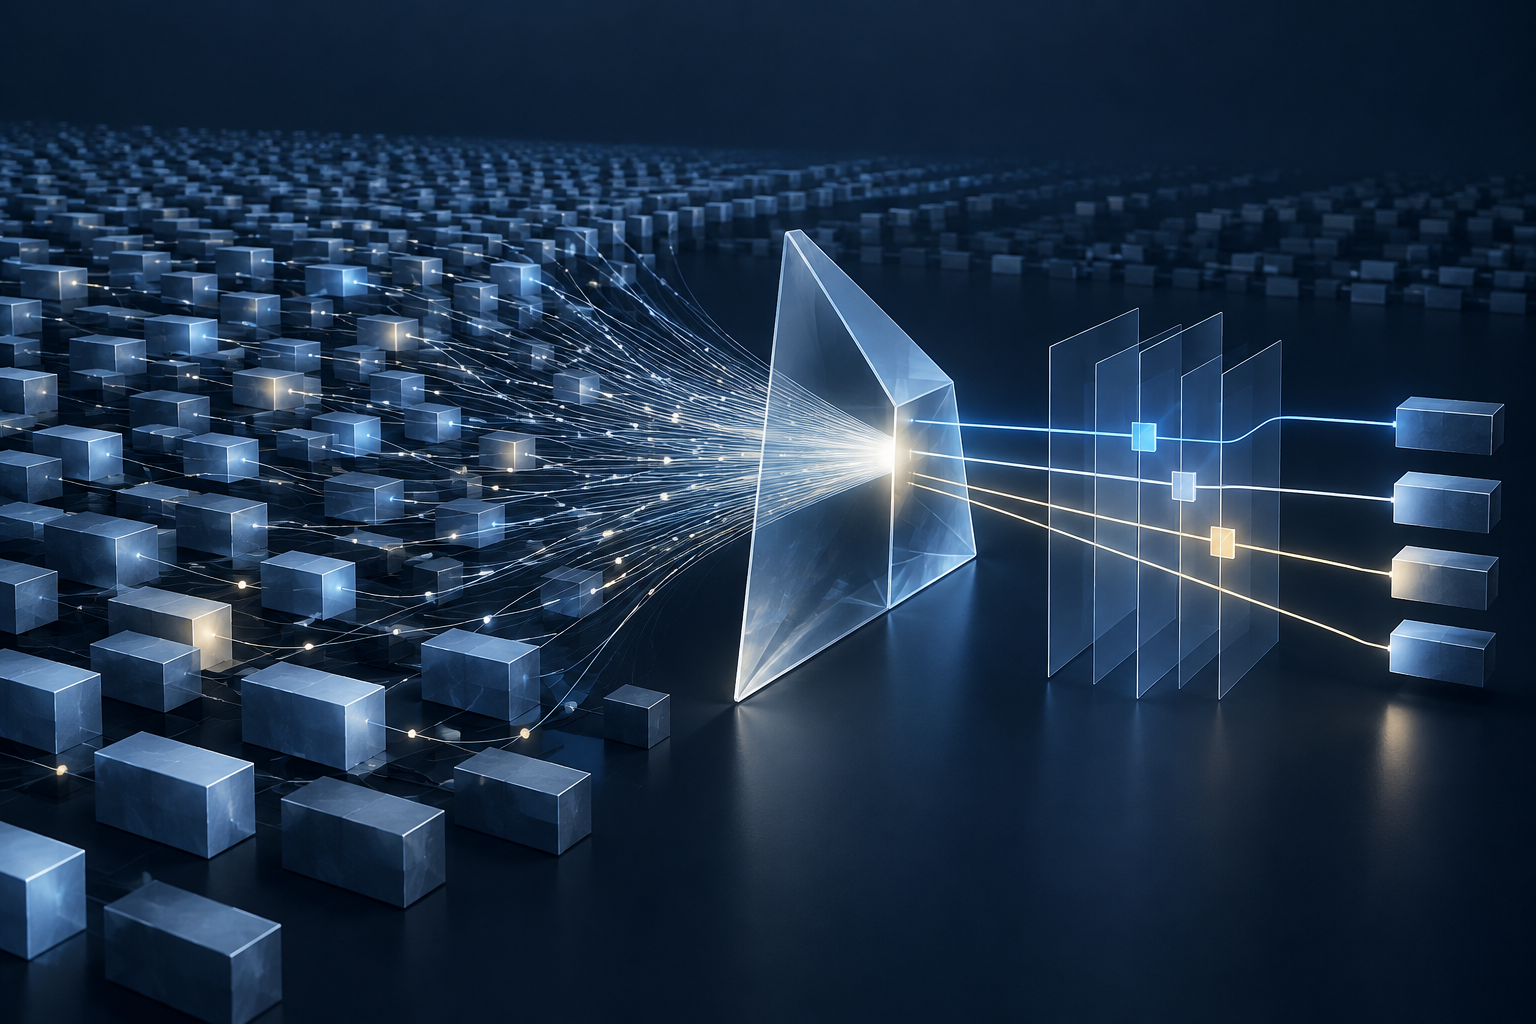
Long-context inference creates a recurring infrastructure problem: generating another token means revisiting an already large context. Faster attention kernels help, but they do not necessarily change how much context participates in each decoding step. Sparse attention takes a different approach by selecting portions of that context instead of processing all of it.
Prism Attention brings a notable reported result to that design space: 3.4× end-to-end decoding speedup over FlashAttention at a 128K-token context length. The paper also claims state-of-the-art performance among mainstream sparse-attention methods on reasoning and long-context benchmarks. The supplied research brief identifies an October 16, 2026 arXiv submission, an October 19 update, and a NeurIPS 2026 main-conference publication claim. [2]
For infrastructure teams, the headline is worth investigating, but it is not a deployment forecast. The available material does not identify the evaluated hardware, models, batch sizes, or absolute performance measurements. What it does offer is a useful systems argument: reducing attention work can pay off when the mechanism for choosing that work remains inexpensive enough.
1. Long-context decoding is a repeated context-processing problem
In conventional attention, each newly generated token attends over the available context. As the sequence grows, so does the amount of key and value data involved in decoding. A long prompt therefore affects more than initial processing. Its context remains relevant to subsequent generation steps.
At 128K tokens, reducing the context examined during each step can materially affect decoding performance. The central question is not simply whether an attention operation can execute faster. It is whether the serving system can avoid processing some context elements without unacceptable task-quality costs.
FlashAttention provides an important baseline because it is an established optimized dense-attention implementation. Prism Attention's comparison is therefore not against an unoptimized implementation. Its reported advantage comes from a different optimization direction: selecting context rather than relying exclusively on more efficient dense processing. [2]
That distinction matters when diagnosing a production bottleneck. A method targeting long-context attention is most relevant when that attention work makes a substantial contribution to decoding cost. It is less informative to look at the largest supported context window than to understand the contexts requests actually carry during generation.
A service dominated by contexts near 128K tokens warrants a different evaluation from one with predominantly short requests and occasional long outliers. The reported result establishes one context-length measurement, not a performance curve. It does not show where the method first becomes beneficial or how its advantage changes as context length increases. Those are deployment questions that require measurements beyond the headline.
2. Index sharing targets the overhead of being selective
Sparse attention has two related jobs: determine which context elements to use, then perform attention over the selected elements. Reducing the second job does not guarantee a faster system if the first job is expensive.
Selection performed independently for every layer, head, or token can consume the savings from skipping key-value entries. Index generation, metadata movement, and indirect memory accesses all belong in the performance accounting. A sparse method must reduce total execution cost, not just the size of its final attention calculation.
Prism Attention identifies its central mechanism as proposal-refined index sharing. At a conceptual level, a proposal supplies candidate indices, refinement adjusts that candidate set, and sharing offers a way to avoid repeated selection work. Index reuse may also improve memory-access regularity. These are high-level interpretations of the mechanism, not a verified description of its implementation. [2]
The available source material does not specify whether indices are shared across attention heads, transformer layers, decoding steps, or another computational unit. It also does not identify the selection technique. There is insufficient information to describe the method as a learned predictor, approximate nearest-neighbor search, clustering scheme, or locality-based selector.
Those omissions prevent a detailed integration assessment. Sharing across heads could present different engineering considerations from sharing across layers or decoding steps, but the brief does not establish which case applies.
The defensible systems takeaway is narrower and more useful: selection overhead is part of the optimization target. Prism Attention's reported end-to-end result suggests that its complete selection-and-attention pipeline performed favorably in the evaluated setting. It does not yet tell an infrastructure team how that pipeline will behave inside its own serving environment. [2]
3. What the 3.4× result establishes, and what it does not
The strongest concrete claim is a 3.4× end-to-end decoding speedup over FlashAttention at 128K context. Its end-to-end framing makes it more operationally relevant than an isolated attention-kernel measurement because it reports improvement at the decoding level rather than only within a single operation. [2]
The word “decoding” still defines an important boundary. This is not a reported 3.4× improvement in prefill, total request completion time, or fleet-level throughput. The available material also does not provide the underlying absolute latency and throughput values or enough methodological detail to reconstruct the measurement.
Several missing variables limit transferability:
- Model configuration: The evaluated model families, architectures, and parameter scales are unspecified.
- Hardware: GPU types and memory-system characteristics are not provided.
- Serving conditions: Batch sizes, decoding settings, and continuous-batching behavior are not described.
- Context distribution: The headline identifies 128K context but does not establish results across shorter or mixed-length workloads.
- Measurement detail: Absolute timing values and the exact values underlying the speedup are unavailable.
These are not minor reporting details for a buyer or platform engineer. They determine whether a measured advantage applies to a particular workload and whether a comparison is reproducible.
The result also should not be converted directly into GPU savings. Faster decoding could potentially support more concurrent work or reduce the resources needed for a fixed token rate. However, the source does not report fleet capacity, GPU counts, power measurements, or cost per token. [2]
The right interpretation is a promising experimental result with a specific baseline and context length. Treat it as a reason to reproduce and extend the measurement, not as a multiplier to apply directly to an infrastructure budget.
4. Benchmark leadership is not dense-attention equivalence
Prism Attention is presented as more than a speed optimization. The authors also report state-of-the-art performance among mainstream sparse-attention methods on reasoning and long-context benchmarks. That claim indicates evaluation of task performance alongside computational efficiency. [2]
Its scope matters. “Among mainstream sparse-attention methods” defines a comparison group; it does not establish universal leadership across every method, benchmark, or model. Similarly, benchmark competitiveness does not establish that the method reproduces dense-attention behavior.
The available material does not include individual benchmark names, exact scores, or degradation relative to dense attention. It therefore cannot resolve whether Prism Attention preserves the behavior relevant to a particular application or introduces a speed-quality trade-off that the application would reject. [2]
An infrastructure evaluation should consequently keep performance and quality measurements connected. A faster configuration is not operationally equivalent if its task outcomes differ in ways that matter to the service. Conversely, a sparse method need not demonstrate universal equivalence to be useful; it needs to meet the quality requirements of the intended workload.
The practical approach is to test the target model on the application's own reasoning and long-context workloads, alongside the intended dense baseline. Record quality results with the same configuration used for latency and throughput measurements. This avoids presenting a speed result from one operating point beside a quality result from another without establishing their relationship.
For procurement and platform planning, the unresolved question is not whether the paper reports competitive benchmarks. It does. The question is whether that competitiveness carries over to the model, context distribution, and application behavior the team must support.
5. Place Prism Attention alongside other inference optimizations
Recent inference research in the brief addresses several distinct bottlenecks. Separating those targets helps teams avoid treating every reported improvement as a competing answer to the same problem.
Efficient CPU-GPU collaborative MoE inference via Adaptive Expert Assignment focuses on assigning missed mixture-of-experts workloads between CPU and GPU. It reports up to 51.9% faster prefill and up to 39.5% higher decode throughput than its strongest baseline across evaluated batch sizes and GPU-memory budgets. Its optimization target is heterogeneous expert execution and placement, not long-context attention selection. [3]
Scaling LLM Inference via Parallelism: Throughput-Latency Trade-off instead presents an SLO-aware framework for choosing parallelism configurations. It reports that stringent time-to-first-token requirements favor pipeline-parallelism-dominated configurations, while relaxed latency constraints shift optimality toward tensor-parallelism-dominated configurations. It also reports more favorable long-context scalability for pipeline-parallel configurations. [5]
These directions address different decisions:
| Direction | Primary question |
|---|---|
| Prism Attention | How much context should participate in attention, and how can selection work be reused? |
| Adaptive expert assignment | Where should missed MoE workloads execute across CPU and GPU? |
| SLO-aware parallelism selection | Which parallelism configuration best fits throughput and latency requirements? |
The reported percentages and speedups should not be ranked as though they came from a shared test. The baselines, workloads, metrics, and optimization targets differ.
Nor does the brief establish that their gains can be multiplied together. Whether these approaches work well in combination requires evaluation. For a platform team, the immediate value is a clearer diagnostic framework: first identify whether the constraint is attention processing, expert execution and placement, or deployment-level configuration. Then choose an experiment that addresses that constraint.
6. Build an evaluation around the complete serving path
A useful Prism Attention evaluation should begin with reproduction, then move toward the intended production workload. Reproducing the reported 128K comparison would establish a reference point. Extending it would determine whether the method is useful beyond that point.
Measure prefill and decode separately. The headline concerns decoding. Separate measurements keep a decoding benefit from being mistaken for an improvement in every request phase. Record per-token latency and throughput across multiple context lengths rather than testing only the longest supported context.
Vary batching conditions. Test batch-size sensitivity and continuous-batching behavior. Include mixed short- and long-context requests because a result from a uniform long-context workload does not establish performance under a different request mix.
Account for selection costs. Measure index-selection overhead and metadata memory consumption. GPU utilization and memory-bandwidth utilization can help characterize how the complete pipeline behaves. The purpose is to determine whether avoided attention work outweighs the costs of deciding what to avoid.
Connect speed to quality. Evaluate the target models and application workloads under the same relevant settings used for performance testing. The paper's benchmark claim does not replace application-specific validation.
Test the intended deployment scale. Evaluate relevant model sizes and multi-GPU configurations. The brief does not establish scaling behavior across these dimensions, so a favorable single configuration should not stand in for all planned deployments.
Together, these measurements produce a more useful decision than a single speedup figure. They identify the conditions under which the method helps, where its overhead becomes material, and whether the observed quality meets requirements. They also provide the evidence needed before translating a research result into capacity or cost projections.
7. What this means for teams running their own inference infrastructure
Prism Attention is a strong candidate for evaluation because it combines a long-context target, a reported end-to-end decoding improvement, and task-performance claims covering reasoning and long-context benchmarks. Its most concrete result remains specific: 3.4× faster decoding than FlashAttention at 128K context in the reported setting. [2]
For teams operating their own inference infrastructure, the broader lesson is to treat context selection as a systems concern, not merely an attention algorithm detail. The cost of generating and moving indices belongs beside attention execution time in the performance model. Faster dense kernels and selective attention pursue different ways of reducing decoding cost, and the right choice depends on the workload.
The immediate next step is a bounded technical evaluation, not a fleet redesign. Prioritize workloads where long-context attention is a substantial decoding cost. Establish the dense baseline, test selection overhead and task quality, and measure behavior under realistic batching and context distributions.
Only then should the team estimate changes to concurrent capacity, GPU requirements, or cost per token. The research brief does not supply those outcomes, and the reported speedup alone cannot establish them.
The opportunity is credible, but the deployment case remains conditional. If proposal-refined index sharing reduces repeated selection work while maintaining acceptable application quality, it could become a useful component of long-context serving. The infrastructure decision should turn on whether that advantage survives the team's actual models, hardware, and service requirements.
Sources
- [1]Exploiting the Flexibility of LLM Inference for Frequency Regulation Service
- [2]Prism Attention: Proposal-Refined Index Sharing Mechanism for Efficient LLMs Inference
- [3]Efficient CPU-GPU collaborative MoE inference via Adaptive Expert Assignment
- [4]Towards Green AI: Evaluating Energy Efficiency for Quantized LLM Inference
- [5]Scaling LLM Inference via Parallelism: Throughput-Latency Trade-off
- [6]Stable Token-level Scheduling for Serverless LLM Inference
- [7]EdgeWise: Bringing Long-Horizon Agents to the Edge via ...
- [8]New Co-Design Framework Speeds Up LLM Inference on Mixed Hardware by Taming
- [9]Designing Transformers for Continuous Diffusion Language Models
- [10]Optimizing AI Deployments with VMware Cloud Foundation ...
Researched from the sources above and fact-checked against them before publishing.
See what this means for your infrastructure.
Book a discovery call and get a benchmark projection for your hardware and model.
SCHEDULE A CALL