LLM Enhancements
PulseInfer and the I/O Problem Behind Long-Context Decoding
PulseInfer treats sparse KV-cache offloading as an I/O scheduling problem. Its reported gains highlight why long-context inference needs more than additional memory capacity.
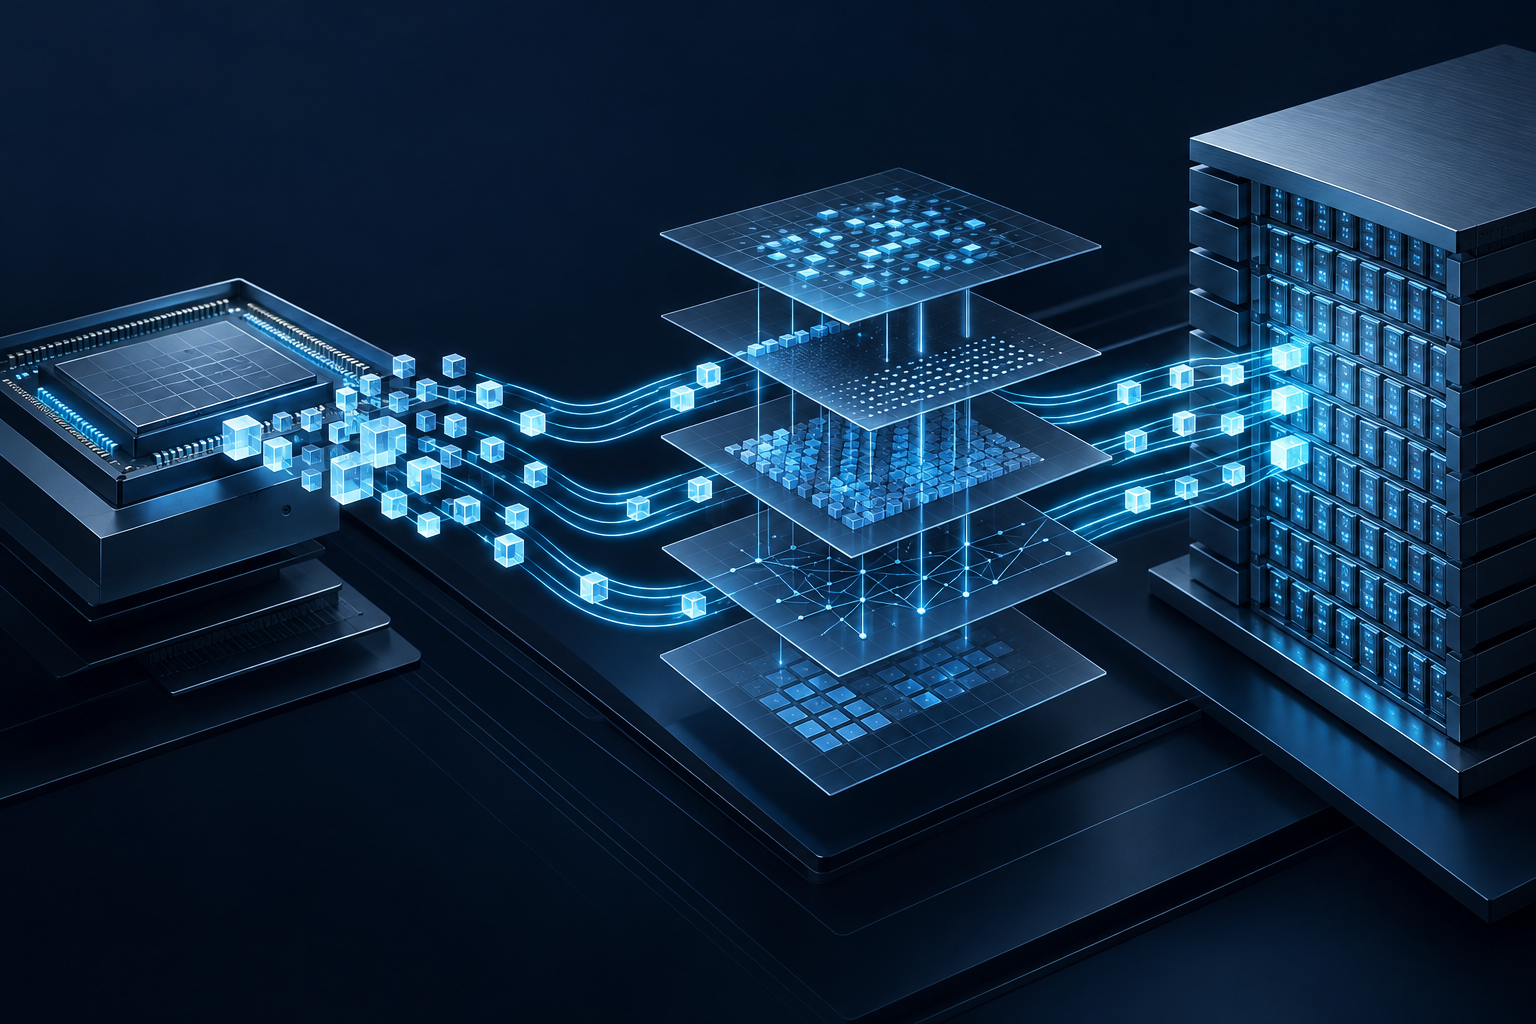
Long-context inference puts pressure on more than a model’s ability to use a large input. It also tests the serving system’s ability to keep historical attention data available without exhausting GPU memory. During autoregressive decoding, each new token requires access to stored key-value representations from preceding tokens. As that KV cache grows, it can constrain batch size and leave GPUs underutilised.[14]
PulseInfer approaches this bottleneck as a data-movement problem. Rather than treating CPU memory as a passive extension of GPU memory, it coordinates sparse KV retrieval with layer execution, offloading decisions and transfer coalescing. Its central proposition is that additional memory capacity becomes useful only when the serving system can retrieve the right data efficiently enough to sustain decoding.[14]
The paper reports up to 4.7× higher decode throughput than SGLang, up to 2.6× higher throughput than the best existing offloading baseline, and up to 76% lower time per output token, with near-lossless accuracy.[14] Those are reported maxima, not deployment guarantees. The more broadly useful development is the systems design behind them: sparse offloading needs an execution strategy, not just a place to store KV blocks.
1. Why moving the KV cache does not remove the bottleneck
The KV cache stores key-value representations of preceding tokens for access during decoding. Its size grows with context length, and decoding repeatedly accesses that history. Keeping the cache on the GPU provides fast access, but competes for limited accelerator memory and restricts how many requests the system can serve concurrently.[14]
CPU DRAM offers another place to hold historical KV data. Moving blocks there can expand effective capacity without requiring the entire context to remain resident on the accelerator. Sparse retrieval then selects a subset of that history for transfer back to the GPU during decoding.[14]
This changes the constraint rather than eliminating it. A cache that fits in host memory still has to supply the data required by attention computation. If retrieval arrives late, or if sparse selections produce many fragmented transfers, the serving system can exchange a GPU-memory bottleneck for a host-memory or PCIe bottleneck.[14]
That distinction is important when evaluating offloading. Capacity answers whether a workload’s state can be stored. Serving performance depends on whether the necessary portions of that state can reach computation at the right time. The two are related, but they are not interchangeable.
PulseInfer identifies three difficulties in this path: variable-latency recall from CPU memory, fragmented transfers caused by sparse token selection, and the need to overlap KV movement with useful GPU computation.[14] Together, they explain why simply placing more cache outside the GPU is not a complete long-context serving strategy.
For infrastructure evaluation, the implication is straightforward: an offloading benchmark needs to demonstrate productive use of the added capacity. Memory savings alone do not establish better decode throughput or lower token latency.
2. PulseInfer coordinates selection, transfers and layer execution
PulseInfer combines several mechanisms around the same objective: making sparse KV retrieval compatible with sustained GPU execution. Its design addresses which data to retrieve, how to move it and how to schedule computation around its availability.[14]
Interruptible layer-wise scheduling targets variable recall latency. The available abstract describes a system that can interrupt and reschedule work at layer granularity, allowing computation to continue or be reorganised while required KV data is retrieved.[14] The important distinction is that data arrival becomes part of scheduling rather than an external delay that execution must simply absorb.
The available evidence does not expose the complete scheduling algorithm. It therefore supports the architectural claim, coordination between layer execution and retrieval, without establishing precise preemption rules, queue policies or timing thresholds.
I/O-Adaptive Offloading Admission adjusts offloading decisions according to I/O conditions. This makes offloading an adaptive decision rather than a uniform policy applied regardless of transfer conditions.[14] The source names the mechanism and its purpose, but does not provide enough detail to specify its admission formula or operating limits.
SoloHead sparse selection determines sparse KV entries to retrieve. PulseInfer combines this selection method with a gather-scatter I/O engine, which coalesces fragmented transfers into more efficient operations.[14] Selection reduces the historical data involved; the I/O engine addresses the execution cost of moving that selected data.
These mechanisms should be understood together. Better selection does not automatically produce an efficient transfer pattern. Transfer coalescing does not, by itself, ensure that data arrives before computation needs it. Scheduling cannot substitute for appropriate offloading decisions. PulseInfer’s contribution is to coordinate these concerns within an I/O-centric serving design.[14]
For engineers, that integration is the substantive point. The system treats sparse access as an end-to-end execution problem rather than assuming that fewer selected KV entries necessarily translate into faster decoding.
3. What the reported performance establishes
PulseInfer is implemented on SGLang, placing its evaluation in the context of an existing LLM-serving system rather than a standalone synthetic kernel. The reported improvements concern end-to-end decode serving.[14]
| Metric | Reported result |
|---|---|
| Decode throughput versus SGLang | Up to 4.7× higher |
| Decode throughput versus the best existing offloading baseline | Up to 2.6× higher |
| Time per output token | Up to 76% lower |
| Accuracy | Described as near-lossless |
These measurements address different operational questions. Decode throughput describes aggregate token-processing capacity. Time per output token, or TPOT, describes the delay between generated output tokens and is therefore relevant to the responsiveness of an individual decoding stream.[14]
Reporting improvements in both suggests that PulseInfer is not presented merely as a way to accommodate more stored context. Under the evaluated conditions, the paper reports gains in both serving capacity and token delivery speed.[14] The available excerpt does not establish whether all headline maxima occurred under the same configuration, so they should not be combined into a single assumed deployment outcome.
The missing benchmark details are consequential. The available evidence does not identify the GPU model, complete model list, context lengths, batch sizes, concurrency levels, host interconnect configuration or statistical variance. Beyond SGLang, it also does not name the best existing offloading baseline.[14]
Accuracy requires similar care. “Near-lossless” is the paper’s reported characterisation, but the excerpt provides no numerical accuracy deltas, evaluation datasets or definition of that term.[14] It should not be rewritten as exact equivalence to the reference execution path.
The appropriate reading is therefore promising but bounded: PulseInfer reports substantial peak improvements for its evaluation conditions. Establishing whether those improvements transfer to a particular service requires the full benchmark setup and workload-specific validation.
4. Why context length changes the optimisation priority
PulseInfer fits into a broader question about decoding: which bytes dominate the work at a given context length? A related paper, “Where Activation Sparsity and KV-Cache Sparsity Cross in LLM Decoding,” describes two recurring sources of traffic. Decoding rereads projection weights at every step, while KV-cache traffic grows with context length.[7]
Its abstract reports that activation sparsity matters more at short context, whereas KV-cache sparsity becomes more important at long context. It also states that the resulting speedups follow byte-level bounds up to fixed kernel costs.[7] This provides a useful explanation for PulseInfer’s focus without establishing a universal context-length threshold.
At shorter contexts, reducing projection work may offer the larger opportunity. As historical KV data grows, reducing the amount of cache data accessed and improving its transfer path become increasingly relevant.[7] An optimisation can therefore be technically effective yet poorly matched to a particular workload’s dominant traffic source.
A separate direction, “Distance-KV: Exploiting Relative Distance for Efficient Long-Context Inference,” examines KV-cache compression using relative-distance information. The available digest reports that retrieval ability can vary strongly with relative distance even within a single attention head. It contrasts that observation with approaches that rank tokens by importance or differentiate attention heads.[3]
Distance-KV and PulseInfer address different parts of the problem. The former investigates how cache selection or compression can exploit model behaviour. PulseInfer concentrates on executing sparse accesses efficiently through transfer coalescing, admission decisions and scheduling.[3][14]
For evaluation, this distinction prevents a common category error: a reduction in selected cache data is not itself a measurement of serving acceleration. Selection determines what must move. The serving system determines how efficiently those movements support computation. Both layers matter, but evidence for one does not establish the performance of the other.
5. How this differs from generating more tokens per iteration
Sparse KV offloading is not the only route to faster decoding. Multi-token prediction and speculative decoding pursue another opportunity: reducing the number of expensive target-model iterations needed to make output progress.
“Beneath the Tokens: A Performance Engineering Study of Multi-Token Prediction in GPU-Accelerated LLM Inference” evaluated two-token multi-token prediction on an NVIDIA A10G in a controlled single-request deployment. Its 360-request benchmark covered plain-text, reasoning-intensive and tool-calling workloads, with telemetry from Nsight Systems, PyTorch Profiler and selected Nsight Compute measurements.[6]
That study reported output-throughput improvements of 1.91× to 2.19×, time-to-first-output reductions of 10.0% to 14.2%, and 56.4% to 78.1% fewer executions of a selected repeating CUDA Graph per generated token. Its explanation was amortisation: additional token progress per iteration outweighed the extra speculative-execution cost.[6]
PulseInfer targets a different expense. Rather than primarily reducing repeated model execution, it reduces the cost of obtaining historical KV information during decoding.[14] These mechanisms are potentially complementary, but the available PulseInfer evidence does not include a combined benchmark with multi-token prediction or speculative decoding.
SpecStream occupies an adjacent area by coordinating KV offloading with speculative decoding. It reported average throughput speedups of 1.41× for Qwen3 and 1.32× for InternLM2.5 over an offloading baseline, plus a 55.4% average improvement in output throughput per GPU compared with parallel speculative decoding on separate target and draft GPUs.[2]
Those figures should not be ranked directly against PulseInfer’s maxima. They describe different approaches and reporting measures, and the available evidence does not establish comparable evaluation conditions. The useful comparison is architectural: SpecStream coordinates offloading with speculation, while PulseInfer focuses more narrowly on sparse KV movement and the scheduling needed to make it efficient.[2][14]
6. What to verify before adopting sparse offloading
The evidence gaps point to a practical evaluation plan. Before treating PulseInfer’s reported gains as relevant to a production service, teams should establish whether their workloads experience the bottleneck it addresses: large KV caches limiting batch size and leaving GPUs underutilised during long-context decoding.[14]
First, match the workload conditions. Request the model architectures, context lengths, concurrency levels and batch sizes behind the results. Compare those conditions with the intended deployment rather than relying on a peak throughput multiplier.
Second, inspect the complete data path. GPU details alone are insufficient for an I/O-centric design. The host-memory and interconnect configuration, along with the baseline offloading implementation, are necessary to interpret the results. Those details are not established in the available excerpt.[14]
Third, evaluate throughput and TPOT together. A deployment decision should distinguish aggregate capacity from the experience of individual output streams. PulseInfer reports improvements in both, but a local evaluation still needs to establish their relationship under the team’s own operating conditions.[14]
Fourth, define acceptable quality changes. Ask for the datasets, reference execution path and measured accuracy differences behind “near-lossless.” For a sparse retrieval system, selection quality is part of the performance trade-off, not a separate footnote.[14]
Finally, separate measured combinations from plausible ones. If the intended serving stack also uses speculative decoding or multi-token prediction, test that combination explicitly. The brief supports potential complementarity, not a claim that independently reported speedups will multiply.
These checks do not diminish the paper’s contribution. They distinguish a credible systems result from a capacity-planning assumption. PulseInfer supplies a concrete design and reported serving gains; deployment confidence requires evidence that the same constraints and benefits appear in the target environment.
7. What this means for teams running their own inference infrastructure
For teams operating inference infrastructure, PulseInfer highlights a shift in how long-context performance should be evaluated. GPU memory capacity remains important, but offloading makes the retrieval path and its coordination with execution equally central to the design.[14]
The relevant question is not simply whether CPU memory can hold more KV data. It is whether sparse selection, transfer coalescing and layer scheduling can turn that capacity into useful decoding progress. PulseInfer’s named mechanisms address those responsibilities directly, which makes its architecture worth examining even before its reported speedups are reproduced locally.[14]
Infrastructure buyers should treat the headline numbers as reasons to investigate, not as inputs that can immediately be applied to fleet sizing. The available evidence lacks the hardware, workload and quality details needed for that calculation. Engineers should likewise resist equating reduced GPU residency with a proven reduction in serving cost.
A sensible next step is a bounded evaluation: establish the current long-context bottleneck, recover the paper’s full conditions, and measure decode throughput, TPOT and output quality under representative workloads. If speculative execution is already part of the stack, include it in that evaluation rather than assuming compatibility gains.
PulseInfer’s broader lesson is clear: expanding KV-cache capacity and efficiently using that capacity are separate engineering problems. Its reported results suggest that coordinating I/O with computation can materially improve long-context decoding. For self-hosted inference, that makes the host-to-GPU data path a first-class part of serving architecture, not merely an implementation detail.[14]
Sources
- [1]TopK-Guided: Adaptive, Budget-Aware Activation Sparsity for Efficient LLM Inference
- [2]Resource-Efficient Speculative Decoding for Long-Context LLM Serving
- [3]AI Paper Digest, 2026-09-25
- [4]ThinkingCap-Qwen3.8-27B: Less Thinking, Similar Accuracy
- [5]NVIDIA Technical Blog
- [6]Beneath the Tokens: A Performance Engineering Study of Multi-Token Prediction in GPU-Accelerated LLM Inference
- [7]Where Activation Sparsity and KV-Cache Sparsity Cross in LLM Decoding
- [8]Daily #079: Anthropic Warns of Yet More Existential AI Risk
- [9]Models | CHAOSNODE
- [10]Vera Rubin NVL72 MLPerf Results: 3.7x Over GB300
- [11]Prefill-Free Cross-Family KV Cache Transfer for Heterogeneous Multi-Agent LLMs
- [12]Blog & Engineering Insights - newsaint
- [13]AI Native Daily Paper Digest, 20260930, Metis | Frontis- ...
- [14]PulseInfer: I/O-Centric Sparse KV Cache Offloading for Efficient Long-Context LLM Decoding
- [15]Periodic Weak Spots: Phase Sensitivity from Chunked KV- ...
Researched from the sources above and fact-checked against them before publishing.
See what this means for your infrastructure.
Book a discovery call and get a benchmark projection for your hardware and model.
SCHEDULE A CALL