LLM Enhancements
RaReCache Moves KV-Cache Optimization Across Model Boundaries
RaReCache uses smaller-model prefill and selective recomputation to cut first-token latency, with important deployment questions still open.
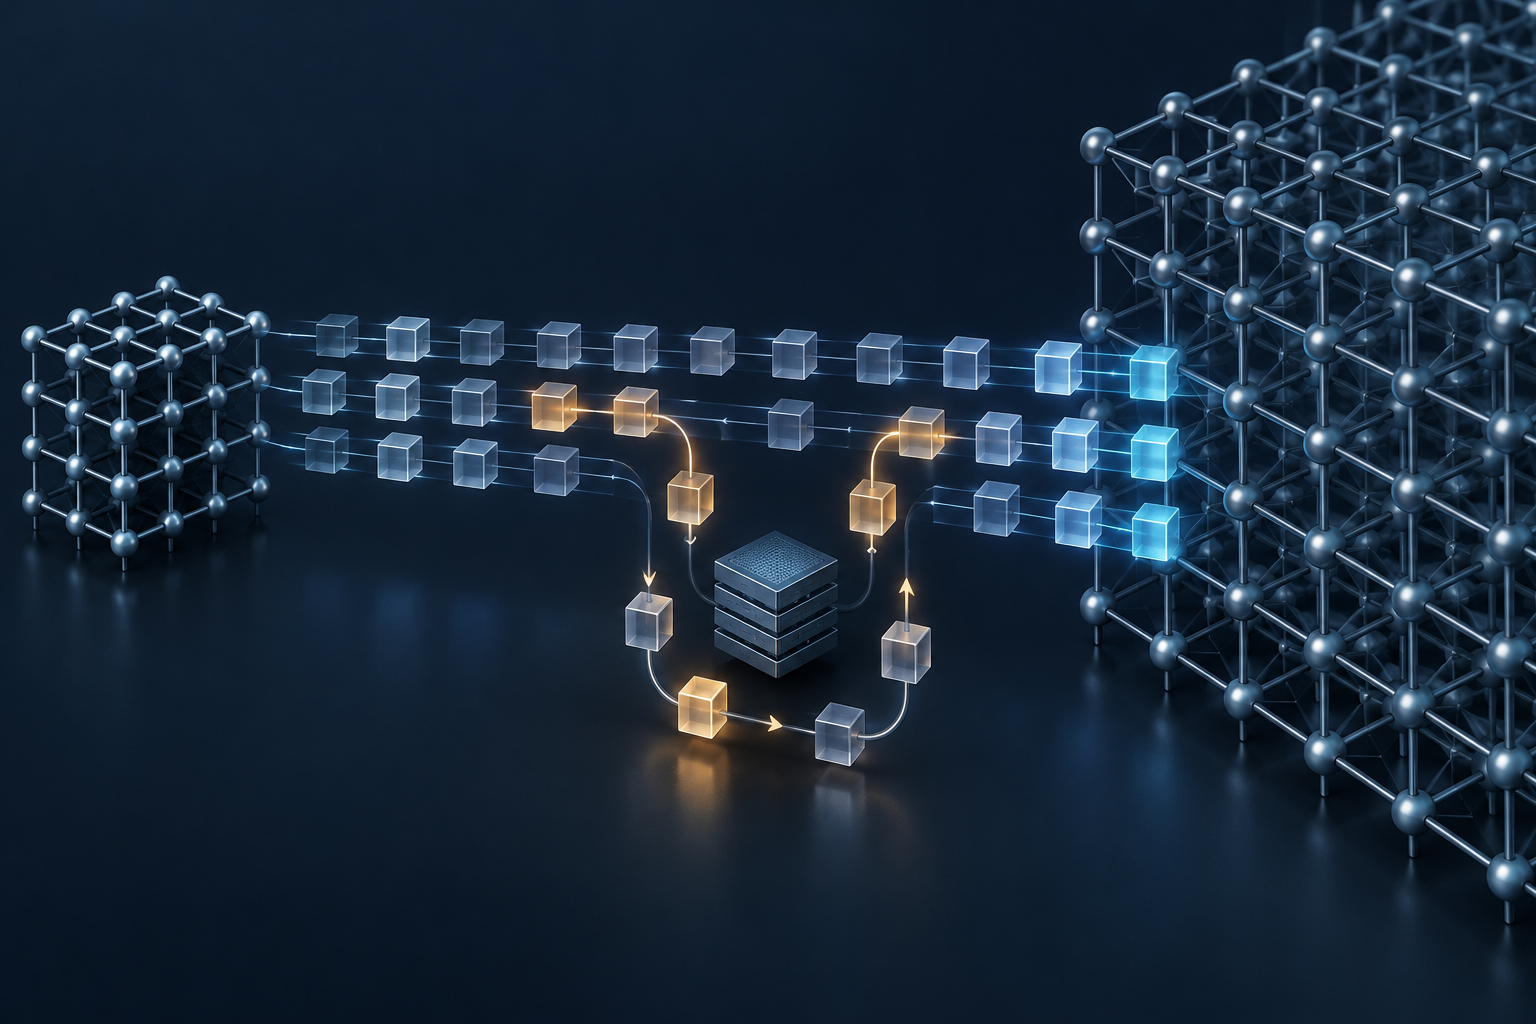
KV-cache optimization usually starts with a familiar question: how can a serving system store or read less state? RaReCache asks a different one: how much of that state needs to be produced by the target model in the first place?
The paper proposes using a smaller model to process a prompt, reusing its cached keys and values in a larger target model, and selectively recomputing positions where the models are likely to disagree. Published on October 8, 2026, and updated on October 9, it reports up to a 3.04× prefill speedup and substantial reductions in time-to-first-token under saturated serving load, using a 30% recompute budget.[7]
For infrastructure teams, the interesting development is not simply another cache technique. It is a proposed division of labor between models: the smaller model supplies much of the prompt-side state, while the larger model corrects selected portions before generation. That could change how teams approach expensive prefill workloads. But the available evidence supports a bounded performance claim, not a general guarantee of compatibility, output quality, or production economics.
1. The bottleneck is prompt processing, not just cache capacity
LLM serving has two computational stages. Prefill processes the input prompt. Decode generates output tokens using the accumulated context. For long prompts, prefill can dominate time-to-first-token because the target model must process the input before it begins generating a response.[7]
This distinction matters when interpreting a cache optimization. During decode, the system repeatedly reads cached keys and values as it generates one or a few tokens at a time. Reducing cache precision or removing selected entries can address the cost of storing and reading that state. Those changes are different from avoiding some of the target model's initial prompt computation.[7]
RaReCache focuses on the latter. Its stated objective is to let small models perform prefill on behalf of much larger targets, with the target recomputing only positions identified as critical. Rather than treating the full target-model prefill as unavoidable, it treats some source-model representations as candidates for reuse.[7]
The relevant operational question is therefore whether a workload is constrained by prompt processing and first-token latency. RaReCache's headline results concern prefill speed, request throughput, and TTFT. They do not establish faster output-token generation or lower decode latency.[7]
For an infrastructure buyer, that is an important boundary. A technique that improves response startup may be valuable without changing the speed of the subsequent generation. Evaluation should preserve that distinction rather than combining all inference performance into one speedup figure.
2. Rank disagreement decides where the target spends computation
RaReCache combines three operations: a smaller source model performs initial prefill, the larger target reuses the resulting KV states, and the target recomputes a selected subset of prompt positions. The selection mechanism is based on rank disagreement between information derived from the two models.[7]
The motivation is straightforward. A smaller model may be cheaper to run, but its internal representations are not identical to those of the target. Reusing every source-generated cache entry could introduce mismatches into the target's attention computation. Recomputing the entire prompt with the target, however, would undermine the objective of avoiding full target-model prefill.[7]
Selective recomputation occupies the middle ground. The method identifies positions where the models' token-level priorities differ and treats those positions as less reliable for direct reuse. Target-model computation is then directed toward those locations rather than spread across the complete prompt.[7]
The available description does not expose the full ranking procedure, the exact disagreement calculation, or the implementation details needed to reproduce the selection. It supports an explanation of the method's organizing principle, but not a claim about how inexpensive or portable that selector will be in a particular serving stack.[7]
The reported evaluation uses a 30% recompute budget. That budget limits how much prompt-side work the target repeats while leaving the remaining cache content available for reuse. It should not be interpreted as a 70% reduction in total serving cost: the smaller model still performs prefill, and the available evidence does not provide a complete accounting of selection, reuse, and recomputation overhead.[7]
The technical proposition is consequently more specific than using a smaller model for a request. The target still performs generation; the source supplies reusable prompt-side state, with selective correction intended to limit the effects of cross-model mismatch.[7]
3. The reported gains answer different performance questions
RaReCache reports several results that should be read separately rather than combined into a single acceleration claim.[7]
| Reported metric | Result | Relevant evaluation boundary |
|---|---|---|
| Prefill speed | Up to 3.04× speedup | Prompt processing rather than complete response generation |
| Request throughput | 1.8× target-prefill throughput | Reported single-GPU online-serving setting |
| Median TTFT | 5.0× lower | At the target model's saturation load |
| 99th-percentile TTFT | 6.4× lower | At the target model's saturation load |
| Recompute budget | 30% | Limited target-model recomputation |
The prefill result measures the stage the method is designed to accelerate. The phrase “up to” matters: the available evidence provides a peak reported result, not a guaranteed improvement across all requests or workloads.[7]
The request-throughput result provides a separate systems signal. RaReCache reportedly handles 1.8× the request throughput of target prefill on a single GPU. This indicates evaluation under online-serving conditions, where requests arrive and compete for GPU capacity, rather than only an isolated prompt-processing benchmark.[7]
The TTFT results are particularly relevant to service responsiveness. Median latency describes the middle of the measured distribution, while the 99th percentile captures a high-latency tail. Both reported reductions occur at the target model's saturation load, so the comparison is explicitly tied to a heavily loaded baseline.[7]
That load condition must remain attached to the numbers. The available evidence does not establish equivalent TTFT improvements under light traffic. It also does not provide absolute latency values, so the ratios cannot be converted into milliseconds or used directly to determine compliance with a specific service-level objective.[7]
Together, the results support a substantial improvement in the evaluated prefill and online-serving setting. They do not establish a universal end-to-end speedup or a corresponding reduction in infrastructure spending.
4. Cross-model reuse is distinct from compression and eviction
RaReCache belongs in the KV-cache discussion, but its primary mechanism is different from reducing cache size or read traffic. Keeping those mechanisms separate helps teams compare research without treating every improvement as interchangeable.
Quantization reduces the bits used to represent cached values. Eviction or sparsification removes selected tokens or blocks. Cross-model reuse avoids producing some target-model KV states by borrowing states from another model. Selective recomputation then corrects positions judged unreliable for that reuse.[7][9][3]
DeferKV illustrates the eviction category. Dated October 5, 2026, it moves the one-shot eviction decision from the end of prefill to the first real decoding step. Its rationale is that early generation queries provide attention signals more consistent with later decode attention than prompt-only signals. It reports improvements on LongBench, RULER, and Needle-in-a-Haystack while maintaining low inference latency.[9]
Read What Matters, dated October 8, targets query-adaptive quantization and cache-read traffic. It reports that reading an average of four bits from an eight-bit cache increases C4 perplexity by at most 0.66% across six base models. Its reported workload uses an 8K-token, batch-one, single-layer workload on an NVIDIA A10G: a restricted eight-bit reader with a two-bit mean payload-read budget has 39% lower latency than the tested TurboQuant codec.[3]
BreadthKV addresses decode-time memory allocation for long reasoning traces by combining quantization and eviction. Across three reasoning models and four math and science benchmarks, it reportedly scores above eviction alone in 17 of 18 settings and produces shorter outputs.[13]
The available evidence does not present these results as direct alternatives on a common benchmark. They concern different resources, workloads, and evaluation boundaries. RaReCache is distinctive because it targets the amount of target-model prefill computation. The supplied evidence also does not establish whether these techniques can be combined without additional costs or quality effects.
5. Quality and compatibility remain decisive unknowns
The largest unresolved question is not whether the reported speedups are interesting. It is what they require from the model pair and what happens to output quality.
The available source description does not identify the source and target models. It also does not specify quality metrics, task-accuracy changes, or whether exact output quality is preserved. Selective recomputation is intended to reduce the consequences of representational mismatch, but that intent is not equivalent to demonstrated quality preservation across tasks.[7]
Compatibility is another open boundary. The evidence does not explain how overhead scales when source and target architectures differ substantially. Teams therefore cannot infer that an arbitrary small model can provide useful KV states to an arbitrary larger model, or that integrating a new pair would require little work.[7]
Several deployment details are also missing: prompt lengths, workload distribution, exact GPU configuration, and absolute latency values. Although the throughput result is described as single-GPU, that alone does not provide enough hardware detail for a procurement comparison or capacity plan.[7]
These omissions should constrain interpretation, not erase the result. The defensible claim is that RaReCache reports meaningful prefill, throughput, and TTFT improvements in its evaluated setting with a 30% recompute budget. The evidence does not show that those improvements generalize across every model pair, hardware platform, serving framework, or prompt distribution.[7]
For engineering review, the distinction is practical. A promising mechanism can justify a prototype before it justifies deployment. Acceptance should depend on reproducing useful performance under the team's own quality requirements, rather than assuming the reported latency ratios settle both questions.
6. Evaluate the complete serving path, not just the headline
A useful evaluation should begin with the target model's current serving behavior. Measure prefill time, TTFT, request throughput, and decode performance separately. The purpose is to establish whether prompt processing is the bottleneck that needs attention and whether gains there would address the service's actual requirements.
Next, compare ordinary target-model prefill with the complete cross-model path. That comparison should include source-model prefill, disagreement-based selection, cache reuse, and target-model recomputation wherever they contribute to measured latency or resource use. A stage-specific improvement is valuable, but it should not hide costs elsewhere in the request path.
Because the paper's strongest TTFT claims are tied to target saturation, test multiple offered loads rather than relying on one operating point. Report both median and 99th-percentile TTFT, alongside the request rate at which each was measured. This would help determine whether the deployment reproduces the reported benefit at saturation and how it behaves under other traffic conditions.[7]
Quality testing should be a separate acceptance gate. Use tasks representative of the intended service and compare the candidate configuration against ordinary target-model prefill. The available evidence does not supply enough quality information to substitute for that evaluation.[7]
Treat the 30% recompute budget as a reported experimental setting, not a universal recommendation. If an implementation allows budget changes, evaluate performance and quality together rather than optimizing latency in isolation.
Finally, record the conditions behind every result: model pair, hardware, prompt distribution, generation lengths, serving configuration, and load. These are evaluation recommendations, not additional findings from the paper. They address the evidence gaps that currently prevent a direct translation from published ratios to a production capacity decision.
7. What this means for teams running their own inference infrastructure
RaReCache offers a different way to think about model heterogeneity. Instead of assigning every computational stage to the same model, a serving system could use a smaller model to supply prompt-side state and reserve the larger model for selected corrections and generation.[7]
For teams operating their own infrastructure, the immediate implication is to inspect the prefill portion of the service before prioritizing another decode-focused optimization. If long prompts and first-token latency are central constraints, cross-model cache reuse is a relevant research direction. If the dominant problem is long-generation cache traffic, the reported RaReCache results do not answer that problem directly.[7]
The next step should be a bounded engineering investigation, not an assumption of production readiness. Establish which model pairs are supported, obtain quality evidence, reproduce latency across realistic loads, and account for the complete serving path. Infrastructure buyers should likewise ask for workload-specific measurements rather than treating the 3.04× prefill result as a general capacity multiplier.
The broader significance is the optimization target: avoid some full-size model computation instead of only making its cache smaller. RaReCache reports compelling results for that approach, including improved tail TTFT under saturated load. Its operational value for a self-hosted deployment will depend on whether those gains survive the team's model choices, quality requirements, and traffic patterns. Those are the questions that separate an interesting serving paradigm from a dependable infrastructure improvement.[7]
Sources
- [1]SPIN: Shadow Predictive Indexer for Sparse Attention
- [2]GitHub - foxl-ai/kiln: An LLM inference engine for AWS ...
- [3]Read What Matters: Query-Adaptive Quantization for KV Caches
- [4]Model-Serving Costs Hinge on KV-Cache and Speculative Decoding
- [5]Persistent Memory in Multi-Agent LLM Inference: What It Costs, What It Buys, and When You Can Tell
- [6]Secure Speculative Decoding for Large Language Models
- [7]RaReCache: Bridging the Gap in Cross-Model KV Cache Reuse via Rank disagreement-based Selective Recomputation
- [8]The Two-Phase Machine: Your LLM Request Is Two Jobs ...
- [9]DeferKV: Rethinking Eviction Timing for One-Shot KV Cache Compression
- [10]2026-10-07-deepseek-v41-flash.md
- [11]ML Drift: Next-Gen GPU AI/ML Inference at the Edge
- [12]Few Bits, One Law: Toward W2A4KV2
- [13]Spend Bytes on Breadth: Precision-Count Trade-offs for Decode-Time KV Compression in Long Chain-of-Thought Reasoning
- [14]VFold: Symmetry-Aware Cross-Layer Value Cache Compression
- [15]Daily Papers - Hugging Face
Researched from the sources above and fact-checked against them before publishing.
See what this means for your infrastructure.
Book a discovery call and get a benchmark projection for your hardware and model.
SCHEDULE A CALL