LLM Enhancements
RIFT: Compressing the Draft Cache Without Losing Speculative Decoding Effectiveness
RIFT combines cache selection, adaptive refresh, and drafter training to reduce draft-side KV state while preserving acceptance length.
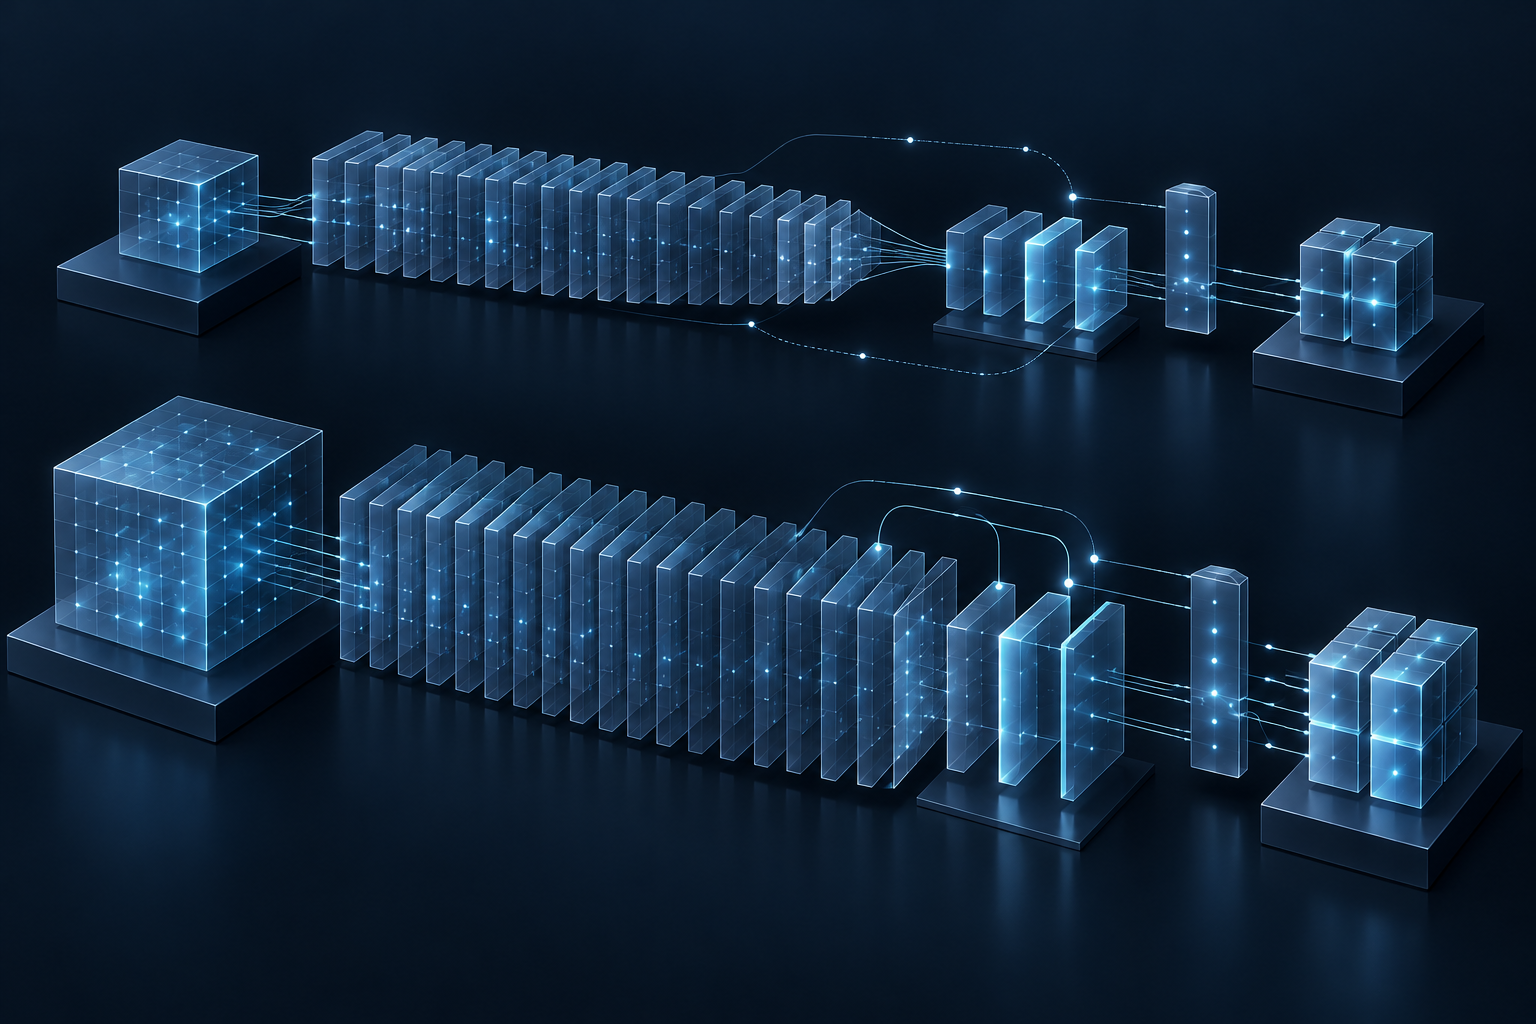
Speculative decoding introduces a second model into the generation path: a smaller drafter proposes tokens, and a larger target model verifies them. That arrangement creates an additional state-management problem. The drafter maintains its own key-value (KV) cache, and that cache grows as generation continues. For long outputs, draft-side state becomes a cumulative cost rather than just a consequence of the original prompt.[2]
RIFT, presented in RIFT: KV Cache Compression for Draft Models with Complementary Compressibility Training, addresses that cost directly. The paper combines selective cache retention, adaptive cache refresh, and training designed to make the drafter effective under compressed-cache conditions. Its central finding is that substantial draft-cache compression can preserve nearly all of the measured acceptance length in a specified long-context configuration.[2]
For infrastructure teams, the distinction between acceptance length and delivered performance is essential. RIFT provides evidence that a drafter does not always need a full cache to remain useful. It does not establish a universal throughput improvement or an end-to-end latency reduction. The engineering question is how much state a deployment can remove without spending the resulting advantage on cache management or weaker proposals.[2]
1. The draft model has a growing state problem
Speculative decoding depends on the relationship between proposal cost and proposal usefulness. The draft model generates candidate tokens, while the target model determines which candidates to accept. A compressed drafter must therefore remain effective at proposing tokens that survive verification, not merely become cheaper to run in isolation.[2]
The draft model's KV cache is part of that proposal cost. It stores attention state used during continued generation, and its size increases as tokens accumulate. RIFT focuses specifically on long-output generation, where a manageable starting prompt can still lead to substantial draft-side cache growth over thousands of generated tokens.[2]
This focus separates the problem from compressing only the target model's cache. Alongside the target model's cache, speculative decoding introduces another cache whose requirements need to be accounted for. RIFT treats that additional state as compressible rather than assuming the drafter must retain the complete history.[2]
The operational implication is that prompt length alone does not describe the draft-cache workload. Output length matters because the cache continues to evolve after prefill. An evaluation limited to initial prompt processing would miss the cumulative behavior that RIFT is designed to address.[2]
For teams assessing the method, the relevant workload description should therefore include both input and output lengths. The cache budget also needs to be considered alongside proposal effectiveness. A small cache is not automatically a useful optimization if its information loss causes the target model to reject substantially more draft tokens. RIFT's contribution is to coordinate compression with mechanisms intended to prevent that failure.[2]
2. Cache selection must preserve useful history and recent tokens
RIFT introduces a family of selection-based KV-cache compression strategies. Rather than retaining every cached token, these strategies balance information from prefill with recently generated tokens. The selected cache is intended to preserve the information most useful to the drafter as generation proceeds.[2]
That balance matters because the compression problem is not simply to impose a smaller storage limit. The drafter must continue operating with incomplete historical state. Which entries remain available affects the information it can use when proposing the next tokens. RIFT therefore makes cache selection part of the generation strategy, rather than treating it as an unrelated memory-management operation.[2]
The paper reports that refreshing the selected cache during generation significantly improves drafter quality compared with relying on a fixed selection. This finding makes the cache's changing contents important, not just its configured capacity. A selection made earlier in the request may not remain equally useful as more output is produced.[2]
For an engineering evaluation, this suggests separating two questions. First, how large is the retained cache? Second, how does the system decide which state occupies that capacity over time? Comparing only token budgets would obscure a consequential difference between a fixed subset and a dynamically refreshed subset.
The supplied evidence does not identify one cache budget or selection policy as optimal for all workloads. Instead, it supports a narrower conclusion: selection-based compression is viable for the draft cache, and refreshing that selection can improve proposal quality. The benefit depends on maintaining useful information under the imposed capacity constraint, rather than on compression alone.[2]
3. Adaptive refresh manages a latency-versus-quality trade-off
Refreshing the cache is not free. RIFT's selection refresh operations require additional score calculations, which add decode latency. More frequent reselection can improve drafter quality, but the work required to obtain that improvement becomes part of the serving cost.[2]
This creates a trade-off that a cache-size metric cannot capture. A system could retain a small cache and still incur meaningful management overhead if it repeatedly recalculates which entries to keep. Conversely, reducing refresh work too aggressively can leave the drafter with less useful information and weaken its proposals.[2]
RIFT addresses this tension with an adaptive KV refresh strategy. According to the paper's abstract, the strategy reduces the number of score calculations while retaining drafter quality. The approach is dynamic rather than a permanently fixed cache-selection schedule.[2]
The available brief does not specify the exact decision rule or expose a deployment-ready tuning procedure. It would therefore be premature to prescribe refresh thresholds, intervals, or implementation details. The supported point is that refresh timing is an explicit optimization variable, and RIFT adapts it to reduce scoring work without giving up the quality benefits of refreshing.[2]
Infrastructure teams should treat this as a reason to measure cache-management cost separately from cache capacity. An evaluation should ask whether quality preservation comes with enough scoring overhead to change the latency outcome. It should also distinguish the effects of cache selection, refresh behavior, and training, where practical.
The broader systems lesson is that draft-cache compression behaves like a runtime control problem. Capacity constrains how much state is retained, selection determines its contents, and refresh decisions determine how much work is spent keeping those contents useful.[2]
4. Compressibility training prepares the drafter for missing state
RIFT does not rely exclusively on inference-time cache management. It also introduces a compressibility-driven training phase based on sparse-attention masks. The objective is to prepare the draft model to remain effective when its available attention state is restricted.[2]
This addresses a mismatch between full-cache preparation and compressed-cache operation. A drafter optimized to use a full cache may lose proposal quality when historical states are removed. RIFT exposes the model to sparse-attention conditions during training so it learns under the same type of information restriction it will encounter during compressed-cache inference.[2]
The paper calls this complementary compressibility training. The complementarity is important: selection and refresh govern which information is available at runtime, while training adapts the drafter to operate under those constraints. Neither component should be treated as a substitute for the other when interpreting the reported result.[2]
For teams evaluating adoption, this changes the scope of the work. RIFT is not presented merely as a cache setting applied to an otherwise unchanged drafter. Its strongest reported acceptance-length result explicitly includes compressibility training. Assuming that the same retention follows from imposing the same cache budget on an unadapted draft model would go beyond the evidence.[2]
A practical assessment should therefore include model preparation as well as serving behavior. Teams should ask whether they can evaluate an appropriately trained drafter and keep that distinction visible in comparisons with their full-cache baseline.
This is also why the method is more than token removal. RIFT coordinates the drafter's preparation with the information policy used during generation. The intended outcome is not simply a smaller state representation, but a model that continues making useful proposals with that smaller representation.[2]
5. What the reported 98% result actually establishes
The main quantitative result uses Qwen3.5-4B as the draft model and Qwen3.5-122B as the target model. With compressibility training, RIFT retains over 98% of the drafter's full-cache acceptance length under a specific long-context workload.[2]
The reported configuration is:
- Input length: 32K tokens.
- Output length: 4K tokens.
- Draft KV-cache budget: 8K tokens.
- Acceptance-length retention: Over 98% relative to the full-cache drafter.[2]
Acceptance length measures how many draft tokens the target accepts before verification rejects a token or ends the current drafted sequence. Retaining over 98% of that baseline indicates that the compressed drafter preserves nearly all of the measured proposal effectiveness in this configuration.[2]
It does not mean that 98% of all proposed tokens are accepted. Nor does it mean that the system retains 98% of baseline throughput or achieves a particular latency improvement. The reported quantity is a relative acceptance-length result, and it should remain labeled that way in technical and purchasing discussions.[2]
The 8K-token budget is one quarter of the stated 32K-token input length. That comparison gives a concrete sense of the cache constraint. However, it is not a claim that total serving memory falls by the same proportion. The budget concerns the draft model's KV cache, not every memory consumer in the inference system.[2]
The inclusion of 4K-token outputs also matters. The evaluation covers continued generation beyond the initial prompt, matching the paper's concern with accumulating draft-side state. Still, the quantitative claim remains scoped to this model pairing and these workload parameters. It does not establish equivalent retention for every model, output length, or compression ratio.[2]
6. Acceptance preservation is not an end-to-end benchmark
RIFT's reported acceptance-length result addresses a central risk of draft-cache compression: losing enough proposal quality to undermine speculative decoding. It is strong evidence for the evaluated configuration, but it is only one part of an infrastructure performance assessment.[2]
The available abstract does not provide a universal tokens-per-second improvement, a complete hardware benchmark, or evidence that the 8K-token budget is optimal across workloads. It also does not establish that compression improves end-to-end latency in every deployment. Selection scoring, refresh decisions, and target-model verification remain part of the overall cost.[2]
A deployment evaluation should keep several measurements distinct:
- Draft-cache capacity: The state budget allocated to the drafter.
- Acceptance length: Proposal effectiveness relative to a comparable full-cache baseline.
- Cache-management work: The scoring and refresh cost associated with maintaining the selected state.
- End-to-end behavior: The resulting latency and throughput on the team's own infrastructure.
These are evaluation requirements, not additional results reported for RIFT. Their purpose is to prevent a favorable proxy metric from becoming an unsupported production claim.
The same caution applies to potential capacity benefits. A smaller draft cache could reduce memory pressure or leave more memory available for other requests and model components. Those are plausible deployment opportunities identified by the brief, not demonstrated concurrency gains or cost savings.[2]
For buyers, the useful question is therefore not simply whether compression works. It is whether a proposed implementation preserves acceptance behavior while improving the metric that constrains the actual service. RIFT makes that question worth testing, but the reported result does not answer it for every infrastructure configuration.
7. What this means for teams running their own inference infrastructure
RIFT suggests that the draft model's cache can be treated as a tunable systems parameter rather than an unconditional requirement for full-history retention. In the evaluated configuration, a trained drafter operates within a constrained cache budget while preserving nearly all of its full-cache acceptance length.[2]
For teams operating their own serving stack, the next step is a controlled evaluation, not an assumption of immediate speedup. Start with the workload dimensions the result makes explicit: input length, generated output length, drafter-target pairing, and cache budget. Preserve those distinctions when comparing the method with existing speculative-decoding behavior.
Then evaluate the coordinated design. Cache selection determines what information remains, adaptive refresh manages the cost of updating that selection, and compressibility training prepares the drafter to function with restricted state. Testing only a smaller cache would not establish the benefits of the combined approach described in the paper.[2]
Keep the decision criteria operational. Does the constrained cache address an actual memory limitation? Is acceptance length preserved on representative requests? How much latency comes from selection scoring? Does the complete system improve the service metric that matters to the deployment? These questions separate a promising research result from a justified infrastructure change.
The takeaway is specific: useful drafting does not necessarily require retaining the full draft-side history. RIFT provides evidence that selection, adaptive refresh, and training can work together to preserve proposal effectiveness under compression. For self-managed inference teams, that creates another optimization surface, provided memory savings, proposal quality, and runtime overhead are evaluated together.[2]
Sources
- [1]UlaCache: Unified Logical Addressing for Sparse LLM Serving
- [2]RIFT: KV Cache Compression for Draft Models with Complementary Compressibility Training
- [3]MemoraX AI Researchers and Collaborators Have 10 Papers
- [4]Announcing New vLLM and SGLang Inference Engines on TPU
- [5]LLM Daily: October 23, 2026
- [6]SGLang-TorchTPU: PyTorch-Native Production Serving on ...
- [7]PCP, DCP, and Hybrid HiSparse on 16 H200s
- [8]Speculative Decoding Explained (2026): Draft, Verify, Limits
- [9]LLM Daily: October 24, 2026
- [10]How to Speed Up Local LLMs with vLLM
Researched from the sources above and fact-checked against them before publishing.
See what this means for your infrastructure.
Book a discovery call and get a benchmark projection for your hardware and model.
SCHEDULE A CALL