LLM Enhancements
SparseEngine Makes Long-Context Inference a State Management Problem
SparseEngine treats sparse KV state as an engine-level concern. Its reported gains make a case for evaluating cache lifecycle and cross-request reuse alongside decoding speed.
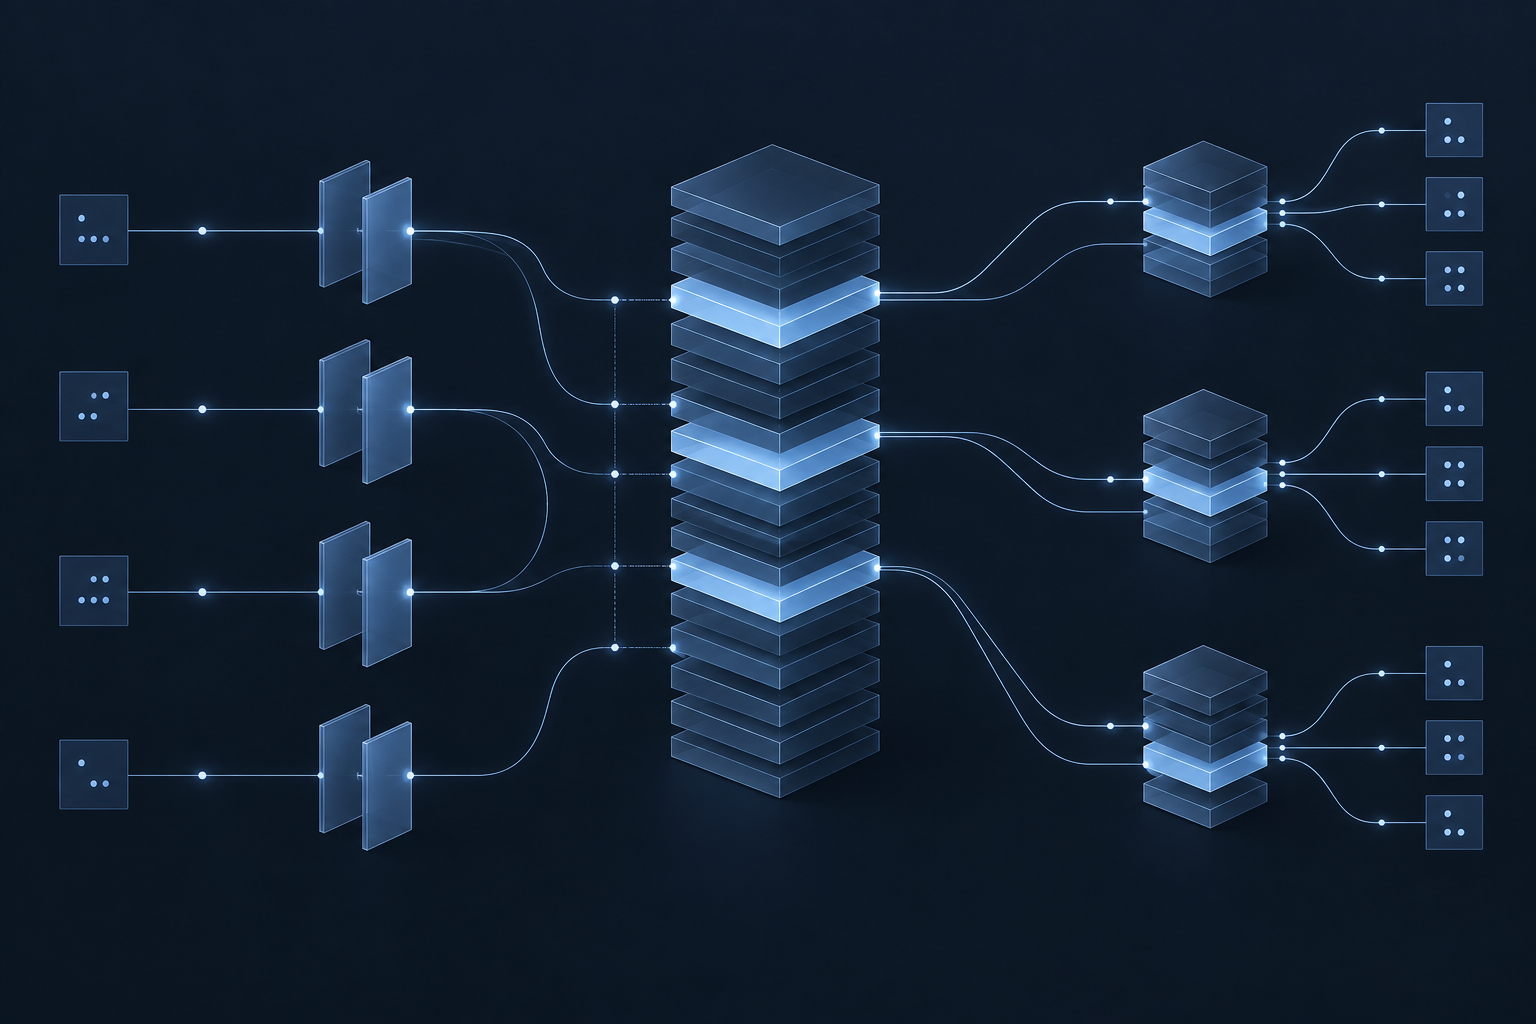
Long-context agents put pressure on inference infrastructure through the history they accumulate. Tool outputs, retrieved documents, previous actions, and intermediate reasoning become part of the context for subsequent generation. That expanding history increases both KV-cache memory requirements and attention computation. For a serving team, the problem is not simply how to process a long prompt. It is how to retain, transform, and reuse useful state as an agent continues working.[5]
SparseEngine approaches this as an engine-design problem. Rather than adding one eviction policy to a fixed cache architecture, it gives sparsity methods control over their KV representations and computation, coordinated through a shared lifecycle contract. The paper reports support for 15 methods across four categories, alongside mechanisms for cross-request state reuse and selective prefix-cache pruning.[5]
The authors also report substantial performance improvements: over 10× higher throughput with KV eviction, over 2.5× faster decoding than vLLM at matched concurrency, and over 2× end-to-end speedup on agent benchmarks while maintaining method quality. Those are separate results, not interchangeable descriptions of one measurement.[5]
For engineers and infrastructure buyers, the important question is what this architecture changes, and what evidence is still needed before its reported gains can inform a deployment decision.
1. Long Context Changes the Serving Bottleneck
An autoregressive serving system retains key and value states for prior tokens so that subsequent tokens can attend to existing context without recomputing the entire sequence. As histories grow, that retained state consumes more memory, while attention must account for an expanding context. Serving multiple requests concurrently adds further pressure on the available cache capacity.[5]
Agent workloads make this especially relevant because their histories grow through repeated interaction. A tool result or retrieved document is not necessarily a one-time input. It can remain part of the context carried into later steps. SparseEngine identifies this accumulated history as a source of both memory growth and increasing attention work.[5]
Sparse inference methods address that pressure by avoiding retention of, or computation over, every historical token. But doing so introduces a second problem: the serving engine must understand what state remains and how a method expects to use it. Removing KV entries is not enough if the surrounding infrastructure assumes a single fixed representation or cannot coordinate the resulting state transitions.[5]
This is the central distinction in SparseEngine's positioning. The optimization target is not only attention computation inside an individual decoding step. It is the interaction between sparse state, request execution, and reuse across related requests.[5]
For evaluation, that distinction matters. A useful assessment must consider both the savings from handling less historical state and the engine's ability to manage that state throughout serving. A decoding result alone cannot establish how well the same approach handles successive requests in an agent task. SparseEngine's architecture and reported agent-benchmark results address these related but different concerns.[5]
2. A Shared Lifecycle Instead of One Universal KV Layout
SparseEngine's main architectural contribution is its shared lifecycle contract. Individual sparsity methods determine how KV state is represented and how attention computation is performed. Common serving infrastructure coordinates the state transitions needed to execute those methods.[5]
This separates responsibilities that a fixed-layout engine can otherwise bind together. The method controls what information survives and how it participates in computation. The engine provides shared coordination around those choices. Cross-request mechanisms then handle reuse of retained history across related requests.[5]
The motivation is that sparse methods need not make the same decisions. A method may evict KV blocks, retain selected tokens, or prune regions of history while preserving the structure needed for reuse. Requiring every approach to fit one representation or eviction protocol can make integration difficult. SparseEngine instead treats those differences as part of the engine's design space.[5]
The paper reports 15 supported methods across four categories. That establishes the authors' stated breadth of support, but it does not reveal the complete integration surface. The available record does not name all 15 methods or identify the four categories. It also does not specify the full lifecycle API, runtime implementation, or hardware kernels.[5]
Those omissions put a boundary around what can be concluded. The architecture suggests a common foundation for evaluating multiple sparse-context strategies. It does not, from the available evidence, establish that arbitrary methods can be combined without additional work, or that a new method can be integrated through a particular interface.
For an infrastructure team, the design is therefore more informative than an assumed implementation detail. It identifies a useful separation between method-specific state semantics and common serving coordination, while leaving the engineering cost of adopting or extending that separation to be verified.[5]
3. Chain Cache Extends State Management Across Requests
SparseEngine introduces Chain Cache to manage state across request boundaries. Its stated function is to resume KV-eviction methods from retained history rather than treating each related request as an entirely new computation.[5]
That is relevant to agents because successive requests can represent successive steps of the same task. A later request may repeat a substantial portion of the earlier interaction history. If useful state cannot survive that boundary, the engine may have to recompute or reconstruct information it has already processed.[5]
Chain Cache addresses this continuity problem. The key idea is not simply that earlier tokens exist in a cache. It is that an eviction method can resume from the history it retained. This connects the method's state-management decisions to the execution of a later request.[5]
The distinction is important when reasoning about sparse serving. An engine must manage both the history represented by the request and the reduced state retained by the method. Cross-request reuse needs to work with that retained state, rather than assuming that all original KV entries remain available. Chain Cache is the named mechanism SparseEngine provides for this purpose.[5]
However, the available evidence does not isolate its performance contribution. There is no verified breakdown of Chain Cache hit rate, memory overhead, eviction granularity, or speedup independent of the rest of the engine.[5]
Teams should therefore avoid attributing SparseEngine's headline multipliers to Chain Cache alone. A more useful follow-up would examine how retained state is reused across representative agent turns, what additional state must be maintained, and how much of the end-to-end improvement depends on that reuse. Those are evaluation questions, not results established by the current record.
4. Prefix Pruning Preserves a Logical Relationship
The second named mechanism is controllable Prefix-Cache Pruning. According to the paper's abstract, it removes KV entries from selected regions of history while preserving logical-prefix matching.[5]
Prefix caching depends on recognizing shared context. Serving systems commonly reuse KV states when requests share an identical prefix. If cached state is altered or deleted without preserving the relationship used for matching, that reuse can be disrupted. SparseEngine's mechanism is designed to permit selected history regions to be removed without losing logical-prefix matching.[5]
This highlights a tension at the center of sparse serving. Retaining fewer entries can reduce the historical state an engine must handle. Yet that retained state must still fit into the engine's reuse mechanisms. Optimizing the amount of stored state and preserving the ability to match related requests are connected requirements, not independent cache features.[5]
The word “controllable” is also significant, but should not be overinterpreted. The source identifies controllability as a property of the mechanism. It does not specify the controls exposed to operators, the exact pruning algorithm, the default regions selected, or the quality criteria used to decide what can be removed.[5]
Consequently, the evidence supports a precise architectural claim: SparseEngine supports selected-region KV pruning while preserving logical-prefix matching. It does not support a claim that any arbitrary deletion policy will preserve reuse or quality.
For deployment assessment, teams should ask how pruning choices interact with their request histories and what evidence demonstrates acceptable quality under those choices. The available brief cannot answer those questions. It does show why prefix reuse should be evaluated alongside sparsity, rather than treated as an unrelated serving optimization.[5]
5. Three Performance Claims, Three Evaluation Boundaries
SparseEngine's reported results span throughput, decoding speed, and end-to-end agent execution. Keeping those boundaries separate is essential to interpreting the paper accurately.[5]
| Reported result | What the available evidence establishes | What remains unspecified |
|---|---|---|
| Over 10× higher throughput with KV eviction | An author-reported throughput improvement in a KV-eviction setting | Absolute throughput, units, hardware, workload details, and baseline configuration |
| Over 2.5× faster decoding than vLLM at matched concurrency | An author-reported decoding comparison controlling for concurrent request count | vLLM version, model, GPU configuration, scheduler settings, and cache policy |
| Over 2× end-to-end speedup on agent benchmarks | An author-reported improvement beyond isolated decoding measurements | Benchmark names, execution details, and per-benchmark results |
All three results are attributed to the full system in the available evidence.[5]
Matched concurrency makes the vLLM comparison more specific, but it does not establish that every other experimental variable was identical. The defensible conclusion is that SparseEngine outperformed the stated vLLM baseline under the authors' matched-concurrency evaluation. The record does not justify extending that multiplier to an arbitrary vLLM deployment.[5]
The end-to-end result is particularly relevant to agent infrastructure because it concerns agent benchmarks rather than only isolated next-token decoding. Even so, the absence of benchmark names and detailed results prevents a direct assessment of similarity to a team's own workload.[5]
The authors also report maintaining method quality. That qualification matters because performance improvements from sparse state handling must be considered together with output quality. However, the available source does not provide the quality metrics, statistical variation, or per-method accuracy results. It therefore does not establish identical quality across every supported method or workload.[5]
The right reading is substantial author-reported improvement under specified experiments whose full conditions are not present in the brief. These results warrant further evaluation. They are not universal capacity-planning factors or a basis for assuming proportional infrastructure savings.
6. What the Evidence Supports, and What It Does Not
The paper, “SparseEngine: Sparse-First Inference Engine,” was posted to arXiv on 30 September 2026 and last updated on 1 October 2026. The available record identifies its core architecture, supported-method count, two named state-management mechanisms, and headline performance results.[5]
That is enough to describe a coherent systems contribution. SparseEngine makes method-specific KV representations part of a shared serving lifecycle, addresses retained history across requests through Chain Cache, and supports selected-region pruning with logical-prefix matching.[5]
It is not enough to determine production suitability. The record does not verify whether source code or a production release is publicly available. It also does not expose the complete experimental tables or provide the implementation detail needed to assess integration with a particular serving stack.[5]
Several missing variables are especially important for reproducibility: model names, GPU types, context lengths, concurrency levels, absolute latency and throughput, and the exact vLLM baseline configuration. Without them, teams cannot distinguish how much of a reported advantage depends on a particular workload or experimental setup.[5]
Method coverage also needs verification. A count of 15 methods across four categories indicates breadth, but it does not tell an engineer whether a specific required method is supported. Likewise, the stated preservation of method quality needs the corresponding metrics and benchmark results before it can be mapped to application requirements.[5]
These limits do not negate the architectural contribution. They define the difference between understanding a promising design and validating a deployable system. The strongest supported conclusion is that SparseEngine presents a sparse-first serving architecture with broad reported method support and substantial author-reported gains, while leaving important implementation and evaluation details unverified in the available record.[5]
7. What This Means for Teams Running Their Own Inference
For self-hosted inference teams, SparseEngine suggests a broader evaluation lens: treat the lifecycle of historical state as part of serving performance. The engine's contribution is not just reducing retained KV entries. It is coordinating method-specific state, preserving continuity across requests, and maintaining prefix-matching relationships after selected pruning.[5]
A practical assessment should begin with the workload. Examine how agent histories grow, which portions recur across successive requests, and where KV memory or attention work becomes a constraint. This provides a basis for deciding whether SparseEngine's target problem resembles the one the team actually needs to solve.
Next, separate architectural fit from benchmark validation. For architectural fit, verify the required sparsity methods, their state representations, lifecycle integration requirements, and compatibility with existing request-state handling. The published count of supported methods cannot substitute for that check.[5]
For performance validation, request or reproduce measurements with explicit models, hardware, context lengths, concurrency, baseline settings, and absolute results. Evaluate decoding and complete agent execution separately. The paper reports improvements in both, but those measurements answer different operational questions.[5]
Quality should be an explicit acceptance criterion. Because the available evidence does not identify the metrics behind “maintaining method quality,” teams need results tied to their own task requirements before accepting a sparse-state policy.[5]
Finally, verify software availability and implementation maturity before treating the design as an adoption option. Neither public source availability nor a production release is established by the brief.[5]
The takeaway is promising but bounded. SparseEngine makes a case that long-context inference optimization belongs in the engine's state-management architecture, not only in an isolated eviction heuristic. For teams operating their own infrastructure, that is a useful direction for technical evaluation. The reported multipliers should motivate a controlled comparison, not replace one.
Sources
- [1]RATIO: Reasoning Analysis and Token-level Inference Optimization for Quantized Reasoning Models
- [2]Spexis: Speculative Lookahead Scheduling for LLM Inference
- [3]OLED-MoE: Accelerating MoE-Based dLLM Inference via...
- [4]Herschel: Continuous Optimization of Production LLM Inference through On-Demand Profiling
- [5]SparseEngine: Sparse-First Inference Engine
- [6]Taming Speculative Search for Test-Time Scaling in LLM Serving
- [7]AI Paper Digest, 2026-09-25
- [8]AgentPerfBench: A Benchmarking and Evaluation Suite for Inference Performance of Agentic LLMs
- [9]AgSpec Paper Clocks 4.76x Decoding Speedup for Coding Agents | AI Weekly
- [10]Efficient Agentic LLM Serving over SSD-based Sparse KV Storage
- [11]DISCO: Distributed Long Context Scaling with Grounding-Reasoning Disaggregation
- [12]Resource-Efficient Speculative Decoding for Long-Context LLM Serving
- [13]Replay the Curvature: Accurate and Scalable NVFP4 Quantization for Large Language Model Inference
- [14]RVQ Position Aware Speculative Decoding for On Device Text to Speech
- [15]FORGE: Form-Optimal Routing of Grounded Evidence for Frozen LLM Agents
Researched from the sources above and fact-checked against them before publishing.
See what this means for your infrastructure.
Book a discovery call and get a benchmark projection for your hardware and model.
SCHEDULE A CALL