LLM Enhancements
Specter: Using Speculative Decoding to Hide MoE Expert Transfer Latency
Specter uses speculative decoding to anticipate MoE expert demand and overlap PCIe transfers with GPU work in single-request inference.
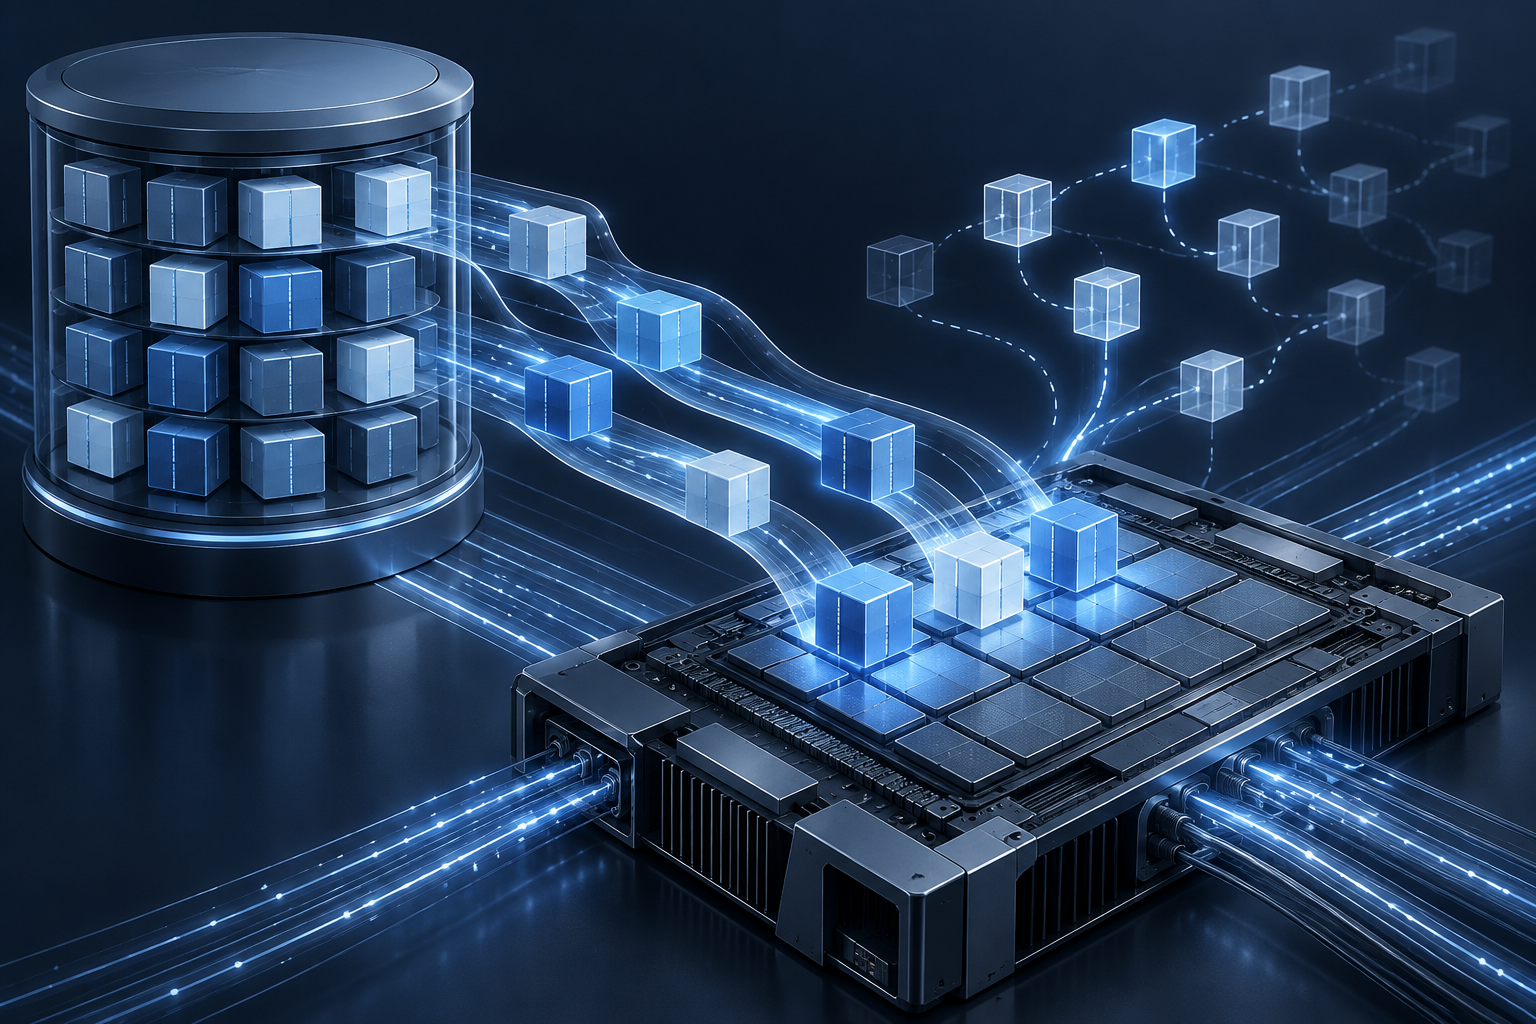
Mixture-of-experts models reduce arithmetic by activating only a subset of their experts for each token. That does not eliminate the problem of storing the full expert set. When a model's experts exceed available GPU memory, moving some of them to host memory creates another constraint: the parameters needed for execution must cross PCIe before the GPU can use them. A sparse computation can still spend time waiting for data.[3]
Specter targets this problem in single-GPU, single-request inference. It combines quantized speculative decoding with expert offloading, using predictions of future expert demand to schedule transfers ahead of verification and execution. Its authors report an average 1.50× speedup in time per output token, reaching 1.88× at best, relative to the state-of-the-art baseline used in their evaluation.[3]
The architectural idea matters as much as the headline result. Speculative decoding supplies information about what execution might require next. Specter uses that information not just to propose tokens, but to prepare model state. For infrastructure teams, it illustrates a way to treat expert offloading as coordinated execution scheduling rather than reactive memory management.
1. Sparse computation still has a memory problem
An MoE model selects only some of its experts for each token, reducing arithmetic relative to a dense model with the same total parameter count. But conditional activation does not mean the entire model fits on a single GPU. Experts that are inactive for one token may still be required later, and their parameters must remain available somewhere.[3]
Expert offloading addresses the capacity constraint by keeping some experts in host memory and moving them to the GPU when needed. This changes the execution problem. The runtime must coordinate expert selection, residency, transfer, and computation. If a selected expert is not resident, its arrival can become a prerequisite for further GPU work.[3]
A reactive approach begins fetching only after the relevant routing and execution decisions are known. In that case, transfer latency can directly extend token latency. Reducing the arithmetic performed per token does not remove this dependency: the selected computation still needs its parameters.[3]
Specter's focus on single-request inference is important here. A single request offers fewer opportunities to hide communication through batching. The system therefore seeks overlap within the work of generating that request, coordinating expert movement with verification and execution rather than relying on many simultaneous requests to provide useful computation.[3]
The deployment question is consequently more specific than whether an MoE model can fit through offloading. It is whether the runtime can deliver the required experts early enough to keep their movement off the latency-critical path. Specter addresses that question through lookahead, linking predicted future demand to transfer scheduling.[3]
2. Speculation becomes an expert scheduling signal
In speculative decoding, a smaller or cheaper mechanism proposes multiple future tokens, and the target model subsequently verifies them. Specter connects this process to MoE execution by using lookahead information to predict which experts future tokens will require. The paper describes the mechanism as “accurate multi-step lookahead over future expert usage.”[3]
This extends the role of speculation. Token proposals provide advance information about possible future computation. For an offloaded MoE model, that information can inform which expert parameters should move toward the GPU before the corresponding verification or execution step.[3]
The conceptual scheduling sequence is straightforward:
- Speculative processing supplies information about possible future tokens.
- Lookahead predicts the experts those tokens will need.
- The runtime organizes expert transfers ahead of the corresponding work.
- PCIe movement overlaps with useful verification and execution where possible.[3]
This is a conceptual description, not a specification of Specter's internal queues or scheduling algorithm. The supplied evidence establishes the connection between lookahead and advance expert movement, but does not provide those implementation details.
The distinction from a conventional speculative decoder is important. Generating token proposals alone does not necessarily account for expert residency. Likewise, an offloading system can manage movement without knowing which experts will be needed next. Specter's contribution is to connect these mechanisms so that speculative information becomes a scheduling signal for offloaded execution.[3]
That makes the design a cross-layer optimization. The decoding process exposes information that can change how the runtime moves model state. Rather than optimizing token generation and expert transfer independently, Specter coordinates them around future expert demand. The intended benefit comes from preparing execution dependencies before they become immediate blockers.[3]
3. Hiding PCIe latency depends on useful overlap
Specter's objective is not simply to start transfers earlier. It is to overlap those transfers with useful computation. If expert movement and GPU work proceed concurrently, some communication latency can be hidden rather than added directly to the time needed to generate an output token.[3]
This distinction matters because offloading still requires data movement. Specter's central mechanism changes when movement occurs relative to verification and execution. A transfer that completes while the GPU performs useful work has a different latency impact from one that leaves execution waiting for parameters.[3]
The benefit therefore depends on successful overlap. Predicted experts must be relevant to upcoming work, and their movement must be scheduled early enough to help. The reported speedup shows gains in the evaluated setting, but it does not establish that every transfer was hidden or that communication stopped being a constraint.[3]
Prediction quality is another important dependency. Correct predictions can place required parameters on the GPU before they are needed. Incorrect predictions may consume bandwidth without helping the current computation. Execution may also stall when an expert that was not anticipated must be fetched. These are implications of the mechanism, not quantified findings in the supplied evaluation.[3]
Although the source characterizes its lookahead as accurate, the available evidence does not include a numerical expert-prediction accuracy or a measured misprediction penalty. It therefore cannot support a claim about how much wasted movement the design tolerates.[3]
For evaluation, the useful question is whether advance movement consistently removes waiting from the target workload. Prediction accuracy, transfer activity, and remaining stalls would help explain that outcome, but the supplied result does not report those measurements.
4. Quantization is part of the coordinated design
Specter combines quantization with speculative decoding and expert offloading rather than presenting it as an isolated memory optimization. Quantized representations can reduce storage and transfer requirements, making quantization relevant both to speculative processing and to communication efficiency.[3]
The mechanisms address different parts of the same dependency. Quantization can reduce representation cost. Speculation supplies advance information about possible future work. Offloading manages experts across host memory and GPU memory. Scheduling connects the pieces by arranging movement before the corresponding execution needs the parameters.[3]
This relationship helps explain why the design is more than a collection of independent features. A smaller representation does not, by itself, determine transfer order. A prediction does not help if it never influences expert movement. An offloading mechanism can satisfy a memory constraint while still leaving transfers on the critical path. Specter coordinates these functions around predicted demand.[3]
However, the supplied source does not identify Specter's exact numerical precision, quantization format, or calibration method. It also does not establish whether quantization applies to all experts, only speculative components, or additional model tensors. Those details should not be reconstructed from the performance headline.[3]
The available evidence also provides no breakdown assigning a particular fraction of the reported improvement to quantization, speculation, or scheduling. The defensible claim is about the combined system, not the isolated contribution of each component.
Quality is a separate evidence gap. The brief does not report accuracy or quality changes associated with quantization and speculative verification. Infrastructure teams should therefore treat performance and quality validation as distinct requirements, rather than reading the TPOT result as evidence of quality preservation.[3]
5. Reading the 1.50× result precisely
The reported result is an average 1.50× speedup in time per output token, with a maximum reported speedup of 1.88×, under single-request inference. The comparison is against the state-of-the-art system used in the evaluation. The supplied source does not identify that baseline.[3]
Time per output token, or TPOT, measures the generation behavior at issue here. It is not time to first token, aggregate requests per second, or total throughput under a specified concurrency level. The result supports a claim of faster autoregressive generation in the evaluated single-request setting, not a general claim that every serving metric improves by the same factor.[3]
The average and maximum also answer different questions. The average summarizes the reported evaluation, while the maximum identifies its best reported speedup. Neither should be presented as a guaranteed improvement for an arbitrary deployment. In particular, the 1.88× figure is not a substitute for the average result.[3]
Several missing details limit direct comparison with an operator's environment:
- The evaluated MoE model names and exact baseline are not supplied.
- The GPU, host processor, and PCIe generation are not identified.
- Sequence lengths, output lengths, and a batch-size range are not provided.
- Quantization bit width and quality measurements are not reported.[3]
These omissions do not change the stated result, but they limit what can be inferred from it. The supplied evidence does not establish equivalent gains across different hardware links, model architectures, or serving workloads. It also does not support numerical claims about cost per token or energy consumption.[3]
For a purchasing or deployment decision, the speedup is evidence that coordinated offloading can improve latency. It is not yet a complete performance forecast for a particular installation.
6. The broader lesson is coordination, not another isolated optimization
Specter's strongest systems lesson is that information generated during decoding can improve the scheduling of model state. Future-token speculation becomes useful beyond token proposal because it helps anticipate which expert parameters execution may need next.[3]
This reframes expert offloading. A purely reactive view asks how to fetch an expert once its absence blocks progress. A lookahead-driven view asks whether the runtime can prepare that expert while other useful work is still underway. The difference is not necessarily whether a transfer occurs, but whether execution must wait for it.[3]
It also gives engineers a sharper way to assess optimization combinations. Quantization, speculative decoding, and offloading may each address a real constraint, yet their coexistence does not establish that they cooperate. The relevant architectural question is whether one mechanism exposes information that another can use to improve execution. Specter explicitly connects speculative information to advance expert scheduling.[3]
That does not establish universal applicability. The available result leaves open whether similar benefits persist across different routing patterns, hardware links, quantization formats, model scales, and concurrent serving workloads. These factors matter because the mechanism depends on useful predictions and successful overlap, while the supplied evaluation does not provide broader sensitivity results.[3]
For engineers, this suggests an evaluation approach rather than a blanket recommendation: examine where execution waits, determine whether future demand can be anticipated, and measure whether advance movement reduces that waiting. Specter provides evidence for this approach in its reported single-GPU, single-request setting. Extending the conclusion requires measurements beyond those supplied in the brief.
7. What this means for teams running their own inference infrastructure
For teams operating their own inference stack, Specter is most relevant when expert offloading and single-request generation latency are part of the deployment problem. Its reported gains concern that setting. They should not be applied automatically to highly concurrent serving or to metrics the evaluation does not report.[3]
A practical assessment should separate architectural fit from benchmark expectations. First, determine whether required expert transfers are contributing to token-generation waits. If expert movement is not the relevant constraint, Specter's headline result does not establish what benefit this coordination would deliver in that environment.
Next, compare any candidate implementation under the workload and hardware conditions that matter to the deployment. Model choice, host-memory configuration, PCIe link, sequence lengths, output lengths, and concurrency should be explicit. The supplied evidence does not provide enough detail to assume those conditions match the reported evaluation.[3]
Quality validation should remain independent of latency validation. Because the brief does not report quantization-related quality changes, teams would need their own evidence before treating faster generation as an acceptable deployment outcome. Likewise, cost and energy conclusions require measurements beyond TPOT.[3]
For infrastructure buyers, the useful questions are concrete: what baseline is being compared, which transfers remain on the critical path, what happens when predictions are wrong, and whether the improvement persists under the intended serving load. Those questions test the mechanism rather than simply repeating the speedup claim.
Specter's reported 1.50× average and 1.88× maximum TPOT speedups make coordinated expert scheduling worth examining. The durable takeaway is that offloaded MoE latency depends not only on where parameters live, but also on when the runtime knows to move them. Speculative decoding can supply that advance knowledge, turning future expert demand into an opportunity to overlap communication with useful GPU work.[3]
Sources
- [1]Evaluating the Applicability of LLM Inference Optimizations on Apple Silicon
- [2]UlaCache: Unified Logical Addressing for Sparse LLM Serving
- [3]Paper page - Specter: Fast MoE Inference via Quantization ...
- [4]Local Inference of LLMs on Long Contexts: A Data Systems Perspective
- [5]Co-designing Pruning and Scheduling for Efficient MoE ...
- [6]tech-brief/news/en/2026-10-21.md at main · BaptisteBlouin/tech-brief
- [7]Is a Faster Model Actually Faster? Test the Whole Job - Morgan Suo, MiniMax
- [8]Sparsity-Aware Scheduling for Efficient MoE-Based LLM ...
- [9]DigitalOcean Releases Inference Optimized Image for AI… |…
- [10]LatComm: Reusable Context Compression for Latent Communication between Large Language Models / LatComm:大模型间潜空间通信的重用型上下文压缩 | Alan Hou
Researched from the sources above and fact-checked against them before publishing.
See what this means for your infrastructure.
Book a discovery call and get a benchmark projection for your hardware and model.
SCHEDULE A CALL