
LLM Enhancements
Speculative Decoding Needs an Energy Budget, Not Just a Longer Draft
Speculative decoding can increase energy use and slow serving. Acceptance, batching, and verification cost determine when it helps.
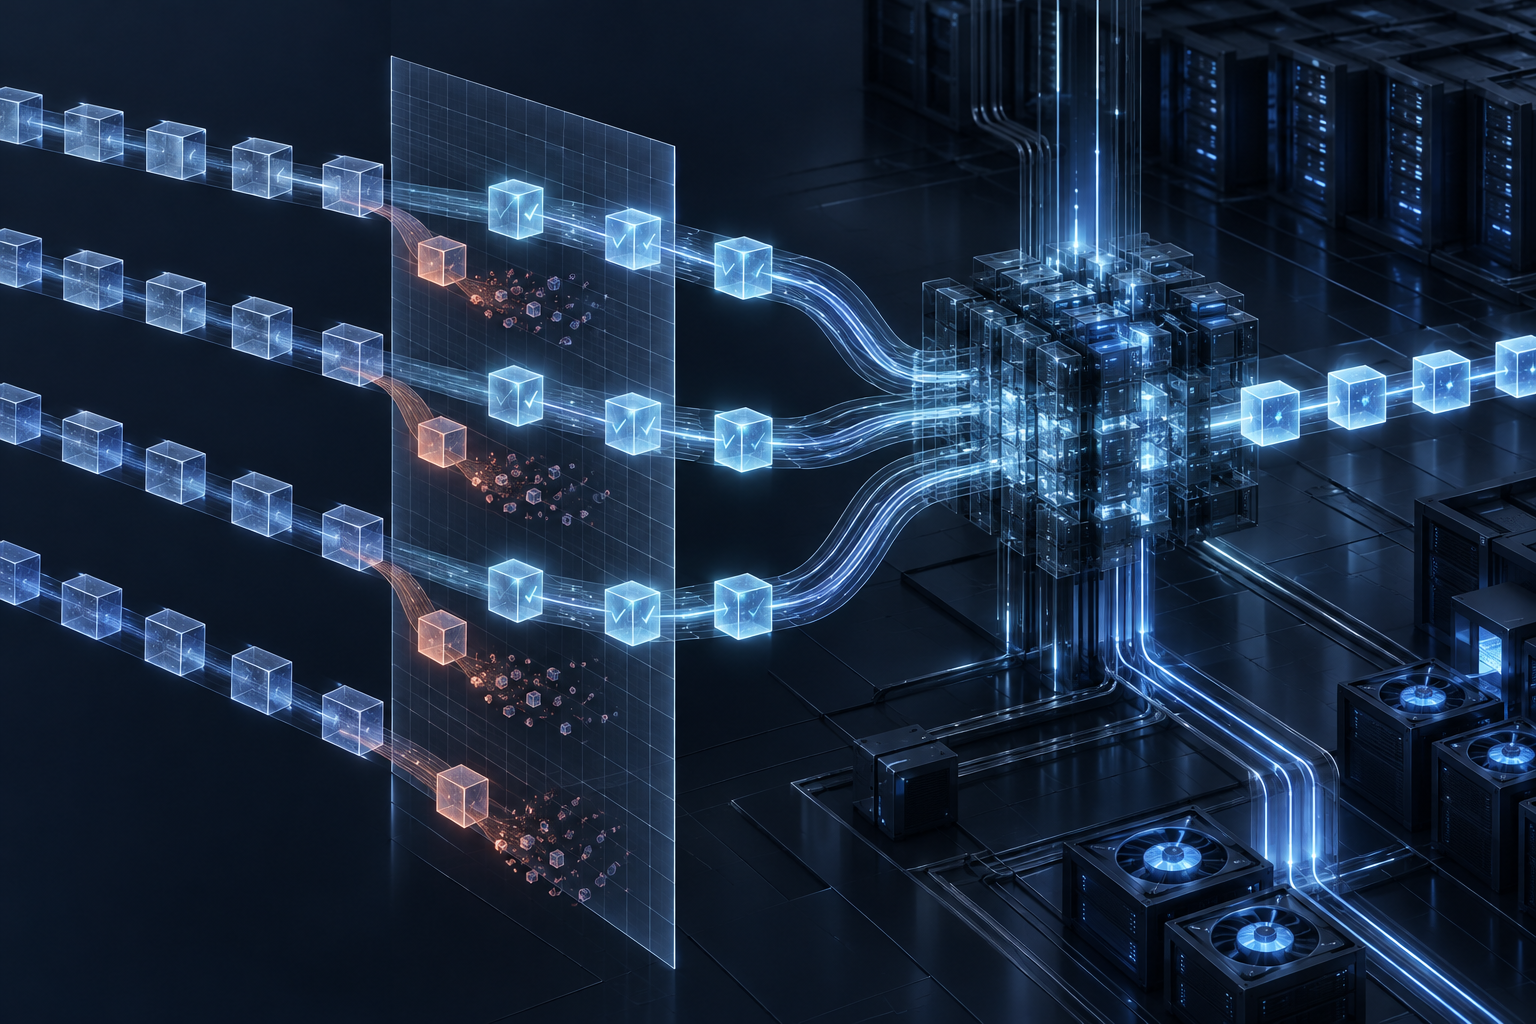
Speculative decoding promises a straightforward improvement to language-model serving: let a smaller model propose several tokens, then have the larger model verify them together. If enough proposals survive verification, the serving system can replace multiple sequential target-model decoding steps with fewer verification passes. The appeal is especially clear when repeated reads of model weights constrain decoding performance.[5]
But fewer target-model steps do not automatically mean lower energy consumption or faster serving. Draft generation adds work. Verification adds arithmetic. Rejected proposals consume resources without delivering the expected decoding benefit. Whether speculation pays off depends on the interaction among those costs, the acceptance rate, and the serving workload.[5]
Only Accepted Tokens Count: An Energy Accounting of Speculative Decoding Under Latency Targets examines that interaction using SGLang with CUDA graphs enabled, NVIDIA H100 and H200 GPUs, batch sizes up to 64, and five corpora. Its central findings challenge an unconditional approach to speculative decoding: at large batch sizes, block drafters can make verification compute-bound and slow execution, while low token acceptance can increase energy per generated token.[5]
For infrastructure teams, the implication is not to abandon speculation. It is to treat speculation as a workload-dependent control decision, with latency and energy evaluated together.
1. Count useful output, not proposed tokens
Conventional speculative decoding separates generation into drafting and verification. A smaller drafter proposes future tokens. The larger target model verifies those proposals in a single forward pass, reusing its weight read rather than performing a separate target-model step for every proposed token. The intended benefit is faster generation while retaining the target model's output distribution.[5]
That mechanism creates an accounting trap. Draft length measures how much work the system proposes to consolidate, not how much useful work it actually consolidates. The benefit depends on acceptance. A long draft with many rejected proposals can look aggressive without being efficient.
The drafter consumes energy regardless of whether its proposals are accepted. The target model must also perform verification. When acceptance is low, those costs can outweigh the reduction in target-model decoding work, increasing energy per generated token.[5]
This makes acceptance more than an indicator of how well the drafter predicts the target model. It is also an operational efficiency signal. A serving system should interpret acceptance alongside the cost of obtaining it: drafter execution and target-model verification both matter.
The practical distinction is between proposed tokens and delivered output. Counting proposals rewards activity. Accounting for generated output exposes whether that activity was useful. Similarly, counting fewer target-model iterations without including draft-model execution can hide part of the cost.
An evaluation should therefore ask a paired question: how much target-model work did speculation avoid, and how much additional drafting and verification work did it require? The paper's findings show why neither draft length nor iteration count can answer that question alone.[5]
2. Batching can reverse the benefit
At low batch sizes, autoregressive decoding is commonly constrained by memory movement, including repeated reads of model weights. Verifying several proposed tokens together can use arithmetic capacity that would otherwise be underused, making better use of a target-model weight read.[5]
That opportunity changes as the batch grows. Verification now processes proposed tokens across more simultaneous requests. The arithmetic burden increases, and the operation can cross from a memory-constrained regime into a compute-bound one. The paper reports that block drafters can push verification beyond this arithmetic and memory balance at large batch sizes, turning the extra verification work into a performance loss.[5]
This is why speculation width cannot be treated as an independent throughput setting. Increasing the number of proposed tokens changes the work performed during verification. Its effect depends on how much other work the GPU is already handling through batching.
A configuration that is advantageous at batch size 1 may therefore impose unnecessary computation at batch size 64. Those operating points should not be expected to respond identically to the same speculation policy.[5]
For continuous batching, the engineering consequence is important: a fixed speculation width may become inefficient as batch composition changes. The controller needs to consider the current operating regime rather than assume that a configuration remains beneficial throughout serving.
GPU utilization is also an incomplete success criterion. Higher utilization can reflect useful consolidation of memory-bound decoding, but it can also reflect additional verification arithmetic that makes execution slower. The goal is not simply to keep more GPU resources busy. It is to produce useful output within the latency target at an acceptable energy cost.[5]
3. The experimental setting matters, and so do its limits
The study's serving configuration is central to its relevance. It evaluates SGLang with CUDA graphs enabled on both H100 and H200 GPUs, tests batch sizes reaching 64, and includes five corpora. This goes beyond treating speculative decoding as a single-request optimization detached from batched serving behavior.[5]
Those details should shape how teams interpret the result. A low-batch demonstration cannot establish that the same policy improves a larger batched workload. Likewise, results from one accelerator should not be carried over automatically to another. The brief identifies different memory and compute characteristics for H100 and H200, making independent validation necessary.[5]
The evidence also has clear limits. It does not establish a universal speculation width or a single speedup that applies across the evaluated conditions. The useful conclusion is conditional: acceptance, batching, and the hardware execution regime determine where speculation helps.[5]
Model architecture adds another reason to avoid universal claims. A complementary study, Why Speculative Decoding Works Better Than Predicted on Sparse MoE Models, evaluates 10 sparse mixture-of-experts models ranging from 30B to 1T parameters, with 8 to 512 experts. It reports that verification cost depends on temporal overlap across draft tokens and GPU execution dynamics, not only activated-expert bytes.[9]
That result does not replace the energy analysis. It reinforces the broader lesson that verification cost must be evaluated for the actual system. Hardware, batch size, and model architecture can all affect the relationship between proposed work and useful output.[5][9]
For buyers, benchmark context is therefore part of the claim. A performance result without its batching, acceptance, hardware, and energy conditions is insufficient evidence for a deployment decision.
4. Latency and energy are separate objectives
A configuration can be useful for meeting a latency target without minimizing energy. Conversely, reducing energy consumption is not enough if requests miss their response-time objective. The paper evaluates speculative decoding under latency targets, making this distinction part of the problem rather than an afterthought.[5]
The relevant accounting boundary includes both models. Measuring only target-model execution leaves out the drafter, even though the drafter consumes energy for accepted and rejected proposals alike. Low acceptance can make that omitted cost particularly consequential.[5]
For an operator, this suggests evaluating configurations in two stages. First, determine whether they satisfy the required latency target under the workload being tested. Then compare the energy per generated token among configurations that satisfy that requirement. This is an evaluation recommendation, not a complete optimization procedure reported by the paper.
Acceptance belongs in that comparison, but it should not replace the energy measurement. The study identifies both low acceptance and compute-bound verification as potential problems. Improving acceptance does not, by itself, establish that verification remains economical at the current batch size.[5]
The same caution applies to reductions in target-model iterations. They explain part of the mechanism, but they do not establish the net result. Additional draft execution and verification arithmetic can change the energy outcome even when the target model takes fewer decoding steps.
The operational question is therefore more specific than whether speculation works: which configuration meets the latency objective with the lowest measured energy per generated token for this workload and hardware? That framing prevents a latency improvement from being presented automatically as an energy improvement.
5. Adaptive control should follow the operating regime
The findings support adaptive speculative decoding rather than a fixed assumption that more speculation is better. They do not provide a complete controller. The following controls are engineering consequences of the reported behavior, not a source-reported implementation.[5]
Track acceptance. Monitor the fraction of proposed tokens accepted by the target model. Falling acceptance should trigger a reassessment of whether the drafter's contribution still offsets its execution and verification costs. Acceptance is evidence for that decision, not a sufficient decision rule by itself.
Make speculation batch-aware. Distinguish operating regions in which verification can exploit available arithmetic capacity from those in which additional verification is becoming expensive. A policy chosen for low-batch execution should not remain unquestioned as the batch grows.
Monitor verification cost. The controller needs evidence about what additional proposed tokens do to target-model execution. If wider speculation adds compute without reducing effective decoding cost, maintaining or increasing width is not justified by the expected memory savings.
Include energy in policy evaluation. Account for drafter energy and rejected proposals, rather than using target-model latency as the sole efficiency measure. Otherwise, the controller can favor a configuration whose apparent benefit disappears at the full-system accounting boundary.
Keep policies hardware-specific. Validate H100 and H200 independently. Results on both platforms establish the importance of testing each, not their interchangeability.[5]
Speculation width, drafter choice, and batching should consequently be treated as coupled variables. A change to one can alter the value of the others. The controller's purpose is to preserve a favorable tradeoff as conditions change, not to maximize draft length or acceptance in isolation.
6. Build an evaluation around deployment decisions
A useful internal evaluation should reproduce the conditions under which the team expects to operate, rather than search only for the configuration with the most attractive isolated result. The paper's combination of batching, multiple corpora, CUDA graphs, and two GPU platforms illustrates why serving context belongs in the test design.[5]
Start with a non-speculative baseline under the same workload and execution settings. Then compare candidate speculative configurations while accounting for both draft and target-model work. This is a recommended evaluation approach: the brief does not provide a universal benchmark recipe or numerical acceptance threshold.
For each operating point, retain enough context to explain the outcome:
- GPU platform and serving configuration.
- Workload or corpus being evaluated.
- Batch size and speculation width.
- Drafter choice and observed acceptance rate.
- Drafter execution cost and target-model verification cost.
- Performance against the latency target.
- Energy per generated token, including drafting.
Keep results separated by operating regime before summarizing them. A low-batch improvement should not obscure a high-batch regression. Similarly, a configuration that satisfies a latency target should remain distinguishable from one that uses less energy but fails that target.
When comparing drafters, ask whether the extra proposals they produce translate into useful accepted output at an acceptable verification cost. When comparing hardware, repeat the evaluation rather than assuming that a policy selected on H100 transfers directly to H200.[5]
The output should be a decision map: configurations that help, conditions under which they stop helping, and signals that indicate a transition. That is more actionable for serving operations than a single aggregate speedup unsupported by its operating conditions.
7. What this means for teams running their own inference infrastructure
For teams operating their own inference stack, speculative decoding should be managed as part of serving policy, not enabled once and treated as a permanent efficiency gain. The reported results show two distinct failure modes: low acceptance can increase energy per token, and aggressive verification at large batch sizes can make execution slower.[5]
The first priority is visibility. Teams need to connect delivered output with acceptance, drafter cost, verification cost, batch size, and latency performance. Without that connection, a reduction in target-model steps can be mistaken for an overall resource saving.
The second priority is configuration discipline. Validate drafter choice and speculation width across the batch sizes and hardware actually used. Do not infer an H200 policy from H100 results, or a high-batch policy from single-request behavior. Keep latency compliance and energy efficiency explicit in the decision.[5]
The third priority is a better standard for procurement and internal performance claims. Ask whether reported improvements include draft-model costs, how acceptance varies across tested workloads, and whether verification remains beneficial at the intended batch sizes. The brief supports these questions, not a universal speedup or guaranteed energy reduction.
The broader lesson is straightforward: useful speculation is conditional speculation. More proposed tokens, fewer target-model iterations, and higher GPU utilization are intermediate signals, not final outcomes. For an inference team, the result that matters is generated output delivered within its latency objective, with the full energy cost accounted for. Speculation earns its place only when the measured tradeoff remains favorable.[5]
Sources
- [1]Quality-aware cost minimization for multi-tier LLM routing in ...
- [2]GPU-Resident Speculative Decoding for In-Browser LLM Inference with WebGPU
- [3]ALPS: An Efficient Request Scheduler for LLM Inference
- [4]Do Recommenders Need to Think in Words? Latent Reasoning for ...
- [5]Only Accepted Tokens Count: An Energy Accounting of Speculative Decoding Under Latency Targets
- [6]Just Talk Once: Communication-Efficient Split Federated LLM Fine-Tuning on Edge Devices | Proceedings of the Twenty-seventh International Symposium on Theory, Algorithmic Foundations, and Protocol Design for Mobile Networks and Mobile Computing
- [7]KV Cache Wars: How Compaction, Quantization, and a ...
- [8]MOSAIC: Efficient Collaborative Inference for Multi-Modal Large Language Models with Distributed Edge Computing | Proceedings of the Twenty-seventh International Symposium on Theory, Algorithmic Foundations, and Protocol Design for Mobile Networks and Mobile Computing
- [9]Why Speculative Decoding Works Better Than Predicted on Sparse MoE Models
- [10]LFM3-1.7B On-Device: The 256K KV Cache Math, Which GGUF to Ship, and the Safety Test to Run First
Researched from the sources above and fact-checked against them before publishing.
See what this means for your infrastructure.
Book a discovery call and get a benchmark projection for your hardware and model.
SCHEDULE A CALL