LLM Enhancements
SPIN Targets the Hidden Indexing Cost of Sparse Attention
SPIN predicts important KV blocks instead of scoring the full cache, reporting throughput and latency gains in vLLM serving.
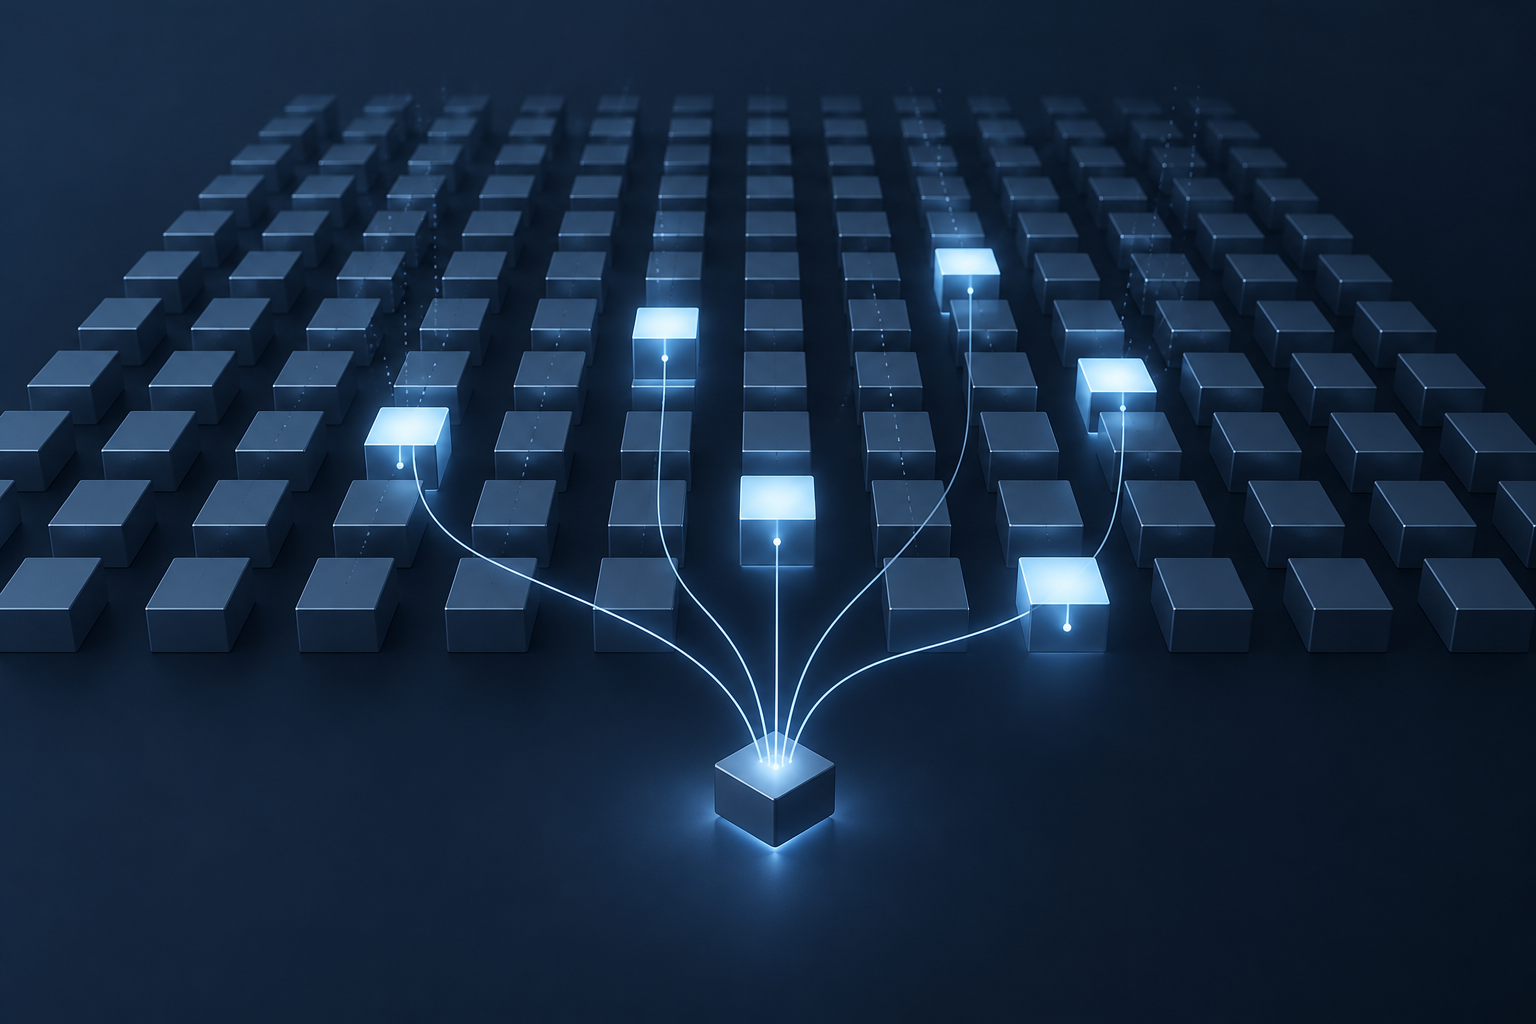
Sparse attention promises to reduce the work of generating tokens from long contexts. But selecting a smaller set of cached information can introduce its own expensive operation: deciding which information belongs in that set. If a serving system scores the entire key-value cache at every decoding step, it retains a cache-wide pass even when attention itself processes only a subset.[2]
SPIN: Shadow Predictive Indexer for Sparse Attention targets that selection cost. The paper, dated October 6, 2026, describes lightweight, history-based prediction of important KV blocks rather than exhaustive scoring at every step. Its available research record reports 30 to 40% sparsity while preserving task quality, with up to 14.9% higher output throughput and up to 13.2% lower median inter-token latency in end-to-end vLLM serving.[2]
Those results make predictive indexing worth examining as a distinct inference optimization. They do not establish a universal speedup or a deployment-ready configuration. The useful question for infrastructure teams is narrower: when sparse attention still pays to examine the full cache, can predicting the working set improve the serving path?
1. The hidden full-cache pass inside sparse attention
Sparse attention and inexpensive attention selection are not the same thing. A system can reduce the KV material consumed by the attention operation while still inspecting the complete cache to identify that material. SPIN's motivation is that existing sparse-attention indexers retain this full-cache scoring pass at every decoding step, and the overhead becomes a major bottleneck as context length grows.[2]
This separates two kinds of work that should not be conflated in performance analysis. The first is identifying relevant cached information. The second is using the selected information in attention. Reducing the second does not necessarily reduce the first. A sparsity figure therefore describes only part of the performance story unless the selection mechanism is also accounted for.
For engineers evaluating long-context serving, the distinction changes the diagnostic question. Instead of asking only how much attention computation can be skipped, ask how much work the system performs to decide what to skip. An optimization that selects fewer blocks may deliver disappointing end-to-end results if selection remains expensive.
SPIN addresses this specific gap. Its contribution is not simply a smaller attention working set, but a predictive approach that avoids scoring the complete cache at each decoding step.[2] That makes it relevant to systems where the retained cache fits within available capacity but selecting relevant blocks has become a compute or latency bottleneck.
The operational lesson is to treat indexing as a separate performance component. Cache capacity, selection cost, and attention execution are related concerns, but improvement in one should not be assumed to resolve the others.
2. Predicting KV-block importance from history
SPIN replaces repeated exhaustive indexing with what the paper describes as lightweight, history-based prediction. It uses historical signals to identify important KV blocks, avoiding the need to score the entire cache at every decoding step.[2] The defining change is therefore in how the system obtains its attention working set, not merely in how large that set becomes.
The available record also says that KV blocks and speculative decoding are first-class design and implementation considerations.[2] This matters because a block-selection mechanism must operate within a serving system, rather than as an isolated attention approximation. The paper explicitly considers these serving concerns, although the retrieved information does not explain the detailed interaction between them.
That boundary is important. The brief does not identify the predictor architecture, training procedure, block size, or exact historical features. It also does not provide an implementation commit. There is consequently no basis for describing SPIN as a particular kind of learned model, specifying an update schedule, or claiming that it requires no training.
Likewise, treating speculative decoding as a design consideration does not establish compatibility with every speculative decoding implementation. Teams would need implementation details and measurements before assuming that SPIN can be combined with their existing token-generation configuration without additional work.
The defensible mechanism-level claim is both simpler and more useful: SPIN predicts important KV blocks from lightweight historical information instead of performing exhaustive cache scoring at every decode step.[2] Evaluating that claim requires examining the total selection path, including the predictive mechanism, rather than counting only the blocks omitted from attention.
3. Reading the sparsity and quality claims carefully
Across evaluations described as covering long-context and agentic benchmarks, SPIN reports 30 to 40% sparsity while preserving task quality.[2] This is an encouraging result because a smaller attention working set is useful only if it retains the information needed to complete the task.
However, the available result does not define the exact unit of sparsity. It does not specify whether the percentage is measured in KV blocks, tokens, attention edges, or another implementation-level quantity. The reported range should therefore remain a sparsity claim, not be translated into a matching percentage of cache memory savings, bandwidth reduction, or total decoding work avoided.
The quality statement also needs its original scope. The retrieved information does not provide individual benchmark names, baseline scores, per-task differences, or confidence intervals. “Preserving task quality” is the paper's aggregate evaluation claim, not evidence that every workload, context length, or individual response remains unchanged.[2]
This distinction is particularly relevant to long-context and agentic applications. Omitting cached information can remove material needed for retrieval, reasoning, tool use, or subsequent steps in an agent workflow. Agentic contexts can contain interaction histories, retrieved documents, tool outputs, and intermediate reasoning, with information that is not uniformly important across decoding steps.
For an infrastructure team, the reported quality result should motivate workload-specific validation. A useful evaluation would ask whether the selected working set preserves the application's actual outcomes, especially when necessary information appears far back in the context. That is an evaluation recommendation, not a claim about an observed weakness in SPIN.
The central trade-off remains clear: predictive selection must save enough work to matter while retaining enough information to preserve useful behavior. SPIN reports a favorable balance on its evaluated workloads, but the available evidence does not establish that balance for every deployment.[2]
4. What the vLLM serving results establish
SPIN's most concrete systems results come from end-to-end vLLM serving: up to 14.9% higher output throughput and up to 13.2% lower median inter-token latency.[2] These measurements are more directly relevant to infrastructure decisions than an isolated reduction in attention operations because they reflect performance within a serving stack.
Output throughput describes generated-token production over time. Median inter-token latency describes the middle-of-distribution delay between generated tokens. The former concerns aggregate output capacity; the latter concerns the cadence of an interactive response. Reporting improvements in both indicates that the benefits appear beyond an internal indexing or attention metric.[2]
The phrase up to is essential. These are maximum reported improvements, not averages and not guarantees for an arbitrary model, workload, or hardware configuration. The available record does not identify the configurations producing either maximum. It also does not establish that both maxima occurred in the same experiment.
Median latency has another boundary: it does not characterize the slowest requests or tokens. A lower median inter-token latency should not be presented as evidence of improved tail latency, lower time to first token, or a matching reduction in total request duration. Those results are not supplied in the brief.
Nor can the throughput result be converted directly into a hardware purchasing or operating-cost claim. Such a calculation would require deployment-specific information about workload, utilization, service requirements, and the tested baseline. The reported percentage is evidence of serving improvement, not a complete capacity plan.
The missing experimental details also limit causal interpretation. Without hardware, model, context-length, batch-size, and profiling information, the gain cannot reliably be attributed to reduced arithmetic, lower memory traffic, improved kernel occupancy, or scheduling changes. What is supported is narrower: SPIN reports measurable end-to-end benefits in vLLM while targeting full-cache indexing overhead.[2]
5. How predictive indexing differs from other optimizations
SPIN belongs in a broader inference optimization discussion, but its target should remain distinct. KV-cache compression, eviction timing, speculative decoding, and predictive indexing address different parts of the generation process. Their headline speedups are not interchangeable measures of effectiveness.
SlimKV, for example, focuses on joint token-feature KV-cache compression with reconstruction-free beacon attention. It reports up to 7.34× attention speedup and 3.38× end-to-end decoding speedup at 128K context length.[6] Its approach changes the representation of cached information. SPIN instead targets the work required to identify important blocks during decoding.[2]
DeferKV changes when an eviction decision is made, moving it from the end of prefill to the first real decoding step. Its evaluations include LongBench, RULER, and Needle-in-a-Haystack.[10] This is a different decision point from SPIN's prediction of block importance during sparse-attention indexing.
APEX addresses speculative decoding by optimizing proposal and draft depth. It integrates with vLLM and reports up to 5.24× speedup over autoregressive decoding with Qwen3-8B across six workloads.[8] SPIN's reported consideration of speculative decoding does not make it an alternative proposal-depth policy, nor does it establish an additive performance benefit when the methods are combined.
These differences prevent a meaningful ranking based on the largest percentage or multiplier. SlimKV's attention speedup, APEX's speedup over autoregressive decoding, and SPIN's output-throughput improvement describe different measurements under different reported conditions. The available SPIN record lacks the details needed for a controlled comparison.
A more useful way to organize these methods is by the bottleneck they address: cache representation, eviction timing, speculative proposal strategy, or block-selection overhead. That framing helps teams choose what to investigate without assuming that one optimization universally dominates the others.
6. The evidence needed for an infrastructure decision
The available evidence comes from the paper's search record rather than detailed experimental tables or an inspected implementation. It supports the stated mechanism and reported aggregate results, but it leaves important reproducibility questions open.[2] Infrastructure teams should make those unknowns explicit before building a rollout or procurement case.
First, establish the experimental baseline. The retrieved information does not identify the models, hardware, batch sizes, context lengths, or exact serving configurations behind the reported gains. Without those details, teams cannot determine how closely the evaluated environment resembles their own or which baseline behavior SPIN improves upon.
Second, clarify the sparsity measurement and implementation behavior. The exact sparsity unit, predictor design, block size, and training requirements are not supplied. These details matter for understanding what changes in the serving path and how to reproduce the paper's operating point.
Third, separate quality validation from performance validation. The aggregate quality claim is promising, but it is not a substitute for per-task results on a team's own long-context and agentic workloads. A local evaluation should compare application outcomes alongside throughput and latency rather than treating sparsity as a success criterion by itself.
Fourth, measure the complete serving configuration. Because SPIN explicitly considers KV blocks and speculative decoding, evaluation should use the cache and token-generation settings intended for deployment. Compatibility and combined performance should be measured, not inferred from separate results for different techniques.
Finally, request evidence beyond best-case improvements. A distribution of results across relevant workloads would be more useful for planning than a single maximum. Teams should also inspect latency measures relevant to their service requirements, rather than assuming that an improvement in the median resolves every responsiveness concern.
These are validation requirements, not evidence that SPIN fails them. They define what remains unknown from the available record.
7. What SPIN means for teams running their own inference infrastructure
SPIN's practical contribution is a sharper way to think about sparse-attention serving: selecting less information is not enough if selecting it still requires examining everything. The paper targets that mismatch by predicting important KV blocks from history, and it reports benefits that reach end-to-end vLLM serving.[2]
For teams operating their own infrastructure, the immediate step is diagnosis rather than adoption by headline. Determine whether cache-wide indexing is a meaningful part of the decoding cost in the serving path under evaluation. If it is not, SPIN's targeted optimization may not address the dominant constraint. If it is, predictive block selection deserves closer investigation.
The next step is a controlled comparison using relevant workloads and service requirements. Evaluate output throughput, inter-token latency, and task quality together. Keep the distinction between maximum reported gains and expected production behavior visible throughout the decision. Do not treat 30 to 40% sparsity as a matching capacity increase, or a 14.9% peak throughput improvement as an automatic reduction in infrastructure spending.
Buyers should apply the same discipline to integration claims. The available record does not provide code-release information, an implementation commit, or enough configuration detail to establish deployment effort. End-to-end vLLM results are valuable evidence, but they are not by themselves proof of a ready-to-enable production feature.
The defensible conclusion is that SPIN presents a promising predictive-indexing approach to a specific long-context bottleneck. Its reported quality preservation and serving gains justify further evaluation. Its broader lesson is immediately useful: profile the cost of choosing the attention working set, not just the cost of processing it.[2]
Sources
- [1]BitNest: Bit-Nested Speculative Decoding for Memory-Efficient LLM Inference Acceleration
- [2]SPIN: Shadow Predictive Indexer for Sparse Attention
- [3]Tailoring the Quantization Space for 1-Bit KV Cache Compression
- [4]GitHub - walidelkhatib/llm-inference-benchmarks: Latency vs....
- [5]Persistent Memory in Multi-Agent LLM Inference: What It Costs, What It Buys, and When You Can Tell
- [6]SlimKV: Joint Token-Feature KV Cache Compression with Reconstruction-Free Beacon Attention
- [7]Few Bits, One Law: Toward W2A4KV2
- [8]APEX: Speculate smarter, not deeper
- [9]InferOpt: Constrained Multi-Objective Search for LLM Inference Configurations
- [10]DeferKV: Rethinking Eviction Timing for One-Shot KV Cache Compression
- [11]Mask-Guided KV Cache Eviction in Block Diffusion Language Models
- [12]Spend Bytes on Breadth: Precision-Count Trade-offs for Decode-Time KV Compression in Long Chain-of-Thought Reasoning
- [13]Secure Speculative Decoding for Large Language Models
- [14]Characterizing Parallelism Strategies in LLM Inference: Fundamental Compute-Communication Trade-offs
- [15]What is Strata? How it speeds up long-context LLM processing ...
Researched from the sources above and fact-checked against them before publishing.
See what this means for your infrastructure.
Book a discovery call and get a benchmark projection for your hardware and model.
SCHEDULE A CALL