LLM Enhancements
Token Window Pacing: Rethinking Admission Control for Serverless LLM Inference
Token Window Pacing reports higher throughput and steadier latency by regulating token workload rather than admitting whole requests or batches.
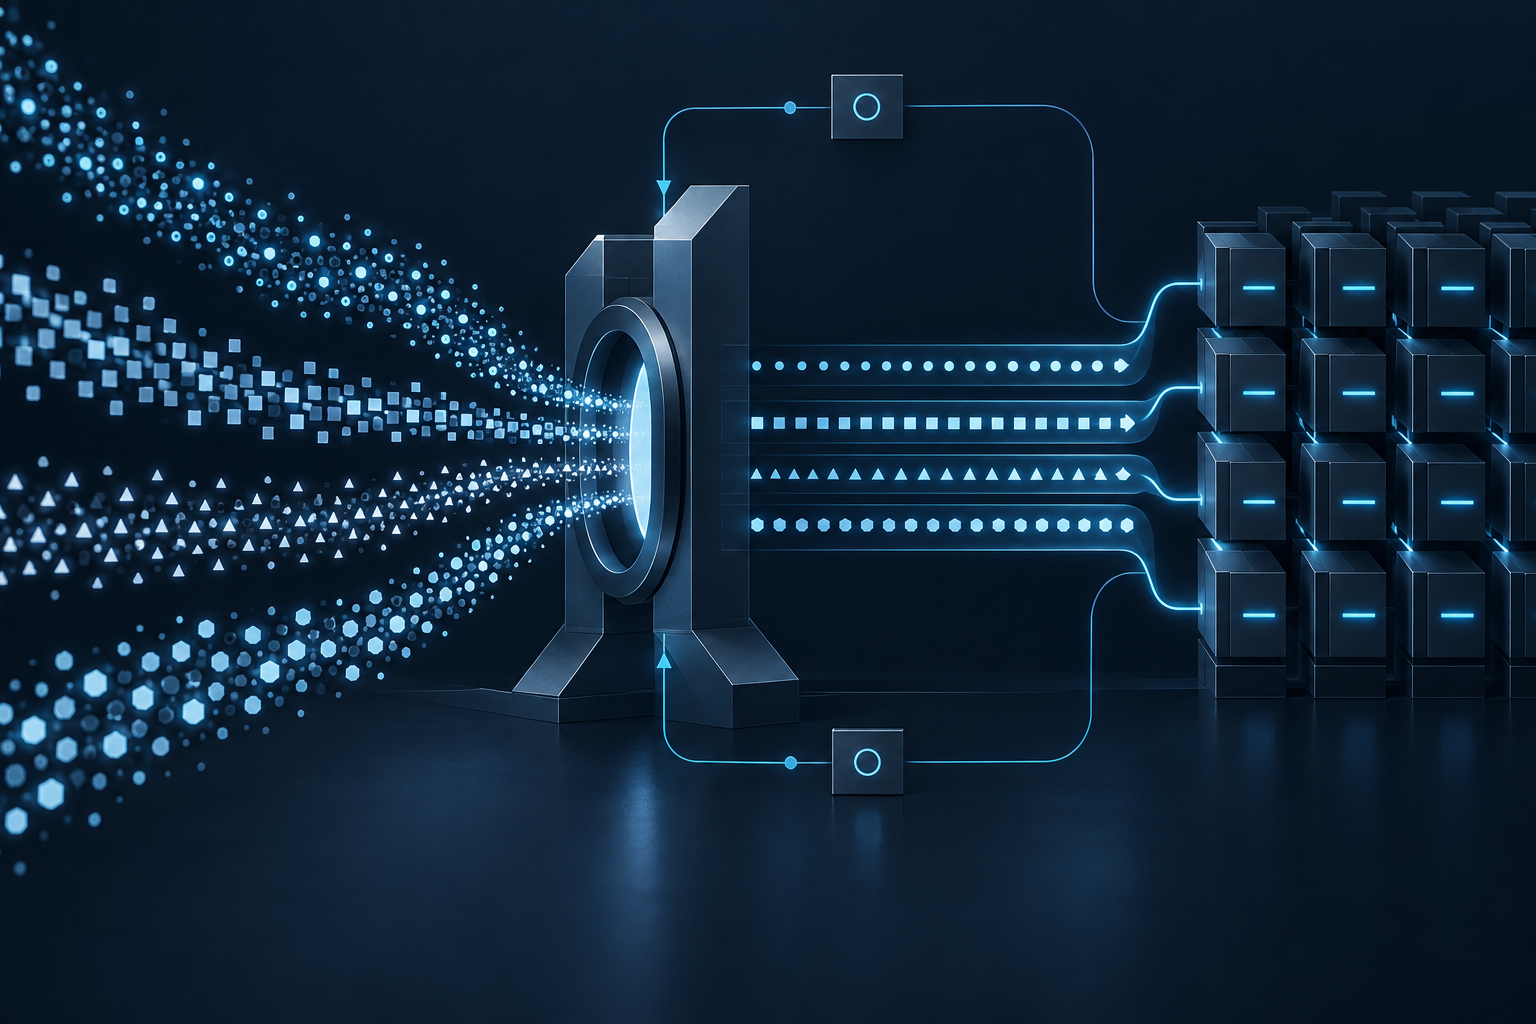
An inference scheduler determines more than which request runs next. It also influences how quickly queues grow, how consistently tokens arrive and whether additional workload produces useful throughput or unstable latency. In serverless LLM inference, those decisions are complicated by requests with different prompt lengths, generation lengths and arrival patterns.[4]
Token Window Pacing (TWP), introduced in Stable Token-level Scheduling for Serverless LLM Inference, approaches this problem through token-level feedback control. The paper, submitted on October 13, 2026, and updated on October 14, reports up to 45% higher throughput than ServerlessLLM and up to 58% higher throughput than conventional schedulers, alongside improvements in latency stability.[4]
The contribution is a scheduling policy, not a new model representation or GPU kernel. TWP regulates admission using runtime signals that reflect the behavior of ongoing generation. For infrastructure teams, that makes it relevant to a practical question: can a serving system admit more useful work without making token delivery less predictable?
The reported results are promising, but the available source summary leaves important experimental details unresolved. Understanding both the mechanism and those limits is essential before translating the headline gains into infrastructure expectations.
1. Why request-level decisions can miss token-level pressure
Autoregressive serving does not complete a request in one forward pass. A request continues to consume compute and memory resources as it generates tokens. Its presence in the system therefore extends across multiple decoding steps, during which new requests may arrive and pending work may accumulate.[4]
A scheduler that admits requests or batches as whole units must manage that continuing demand through relatively coarse decisions. The mismatch becomes important when requests differ substantially. Prompt lengths affect the work entering the system, generation lengths affect how long requests remain active, and arrival patterns affect how quickly demand changes.[4]
The paper identifies instability under these variable workloads as a central problem. A request already generating tokens can remain active while incoming work competes for capacity. Meanwhile, queue depth can change quickly. Admission decisions that do not respond adequately to those conditions can contribute to latency spikes.[4]
Several serving objectives must be considered together:
- Time to first token (TTFT): how quickly a request begins receiving output.
- Inter-token latency (ITL): the time between generated tokens.
- Queue growth: the accumulation of pending workload.
- Aggregate throughput: the amount of work the system completes.
These objectives describe different aspects of service behavior. Stable TTFT does not by itself establish consistent token delivery, and higher throughput does not by itself establish acceptable tail latency. TWP is presented as a way to address these concerns together by making admission control responsive to the runtime behavior of token generation.[4]
The design starts from a straightforward observation: the unit used to regulate workload should reflect the way that workload consumes serving capacity.
2. What Token Window Pacing actually controls
TWP is described as a closed-loop scheduling framework. Instead of relying only on request-level or batch-level admission decisions, it uses observed runtime information to regulate the token workload entering the serving system.[4]
The available description identifies three categories of input:
- Inter-token latency, which captures the timing of ongoing token generation.
- Queue depth, which indicates pressure from pending work.
- Workload characteristics, which capture differences between requests and their expected execution demands.[4]
These signals feed an admission-control loop. When ITL rises or the queue becomes congested, admission can be regulated before severe latency spikes develop. When capacity is available, the scheduler can admit additional work without waiting for a coarse batch boundary.[4]
The important distinction is the control variable. Conventional scheduling commonly treats requests or batches as the units of admission. TWP instead regulates token workload, using runtime feedback to adjust how work enters the system.[4]
That description should not be stretched into an implementation claim. The available material does not establish the precise control law, thresholds, sampling intervals or scheduling overhead. It also does not provide enough detail to reconstruct how each feedback signal contributes to an admission decision. The supported conclusion is that TWP applies token-level feedback to request admission, not that every generated token is independently dispatched through a fully specified mechanism.
For engineers, this distinction separates the architectural idea from the implementation evidence. A scheduler can be responsive to token-generation behavior while still admitting requests. The essential change is that admission reflects current token-level conditions rather than relying solely on whole-request or whole-batch decisions.[4]
3. Reading the throughput and latency results together
The paper reports throughput improvements of up to 45% over ServerlessLLM and up to 58% over conventional schedulers. It also reports stable TTFT, significantly reduced latency spikes, lower P99 tail latency and reduced variation in ITL. The experiments are described as using realistic serverless workloads.[4]
Those are complementary claims, not interchangeable ones. Throughput measures completed work, while latency measurements describe how that work is experienced over time. A serving system can improve one dimension without improving another. TWP's reported contribution is that its admission policy improves throughput while also stabilizing service behavior.[4]
The two throughput comparisons must remain separate. The 45% figure is relative to ServerlessLLM, while the 58% figure is relative to conventional schedulers. Neither should be presented as a universal improvement across deployments. Both are reported maximum gains, and the available source summary does not provide the individual experimental conditions behind them.[4]
The latency claims also need careful interpretation. Lower P99 latency concerns the tail of the latency distribution. Reduced ITL variation concerns consistency between token arrivals. Stable TTFT concerns the beginning of a response. Together, these suggest broader improvements in serving predictability, but the summary does not supply absolute values for any of these metrics.[4]
Without absolute throughput, TTFT, P99 or ITL measurements, teams cannot determine whether the evaluated configurations would satisfy their own service objectives. They also cannot infer how much infrastructure a deployment could remove while maintaining equivalent performance.
The defensible reading is narrower: the reported experiments support token-level admission control as a promising way to improve throughput and latency behavior together. They do not establish a transferable capacity multiplier for every inference workload.
4. A serving-policy optimization, not a utilization guarantee
TWP operates at the serving-policy layer. Its mechanism concerns which workload enters the system and at what token-level pace. The source does not claim changes to model weights, quantization formats, KV-cache representation, attention computation or GPU hardware.[4]
That scope matters when interpreting the throughput gains. Higher throughput indicates that the scheduler changes how available serving capacity is allocated across requests. It does not, by itself, establish a specific increase in GPU utilization. The available source reports no numerical GPU-utilization result for TWP.[4]
Infrastructure evaluations should therefore distinguish between two questions: whether the system completes more work and whether a hardware-utilization metric increases. The evidence supplied here supports the former through the reported throughput comparisons. It does not quantify the latter.
The broader systems argument is that arithmetic capacity alone does not determine serving performance. Queueing, admission control and latency variance influence whether available hardware capacity becomes useful completed responses. TWP targets those dynamics rather than changing the underlying arithmetic or compressing the model.[4]
This also limits what can be said about cost and efficiency. The summary does not provide scheduling overhead, energy measurements or deployment costs for TWP. A throughput improvement should not be relabeled as an equivalent cost reduction or energy saving without additional evidence.
For buyers, the relevant distinction is between a promising performance mechanism and a demonstrated operational outcome. TWP provides evidence for improving the allocation of serving capacity under the evaluated workloads. Assessing its effect on infrastructure requirements would require measurements against the team's own latency objectives, workload mix and deployment configuration.
5. Where TWP fits among other inference optimizations
Other work from the same period addresses different layers of the inference stack. Comparing these approaches helps clarify what TWP does, without implying that their reported gains are directly comparable or additive.
Scaling LLM Inference via Parallelism: Throughput-Latency Trade-off studies tensor parallelism, pipeline parallelism, SLO-aware serving and long-context scalability. It reports that stringent TTFT requirements favor pipeline-parallel-dominated configurations, while relaxed latency constraints shift the optimum toward tensor-parallel-dominated configurations.[3] That work concerns parallelism configuration under latency constraints. TWP concerns admission control under changing runtime conditions.[4]
Efficient KV Cache Migration for Geo-Distributed LLM Inference in Collaborative Edge Computing introduces EdgeFlow. It combines direct KV-cache transmission with activation-based recomputation and reports migration-time reductions of up to 45%.[5] That percentage describes migration time, not serving throughput, and should not be compared directly with TWP's 45% throughput improvement over ServerlessLLM.
Fractional Power-of-Two Quantization for Efficient and Effective Multiplier-Free LLM Inference focuses on fractional power-of-two quantization for multiplier-free inference.[1] Its contribution concerns numerical representation and computation, rather than the admission policy governing incoming work.
Towards Green AI: Evaluating Energy Efficiency for Quantized LLM Inference evaluates ten post-training quantization strategies across several models and NVIDIA GPUs. It reports up to fourfold energy savings relative to FP32 for short text generation using fused-kernel EETQ int8 and Bitsandbytes int8 implementations.[2] Those are energy results under the stated evaluation conditions, not evidence about TWP's energy efficiency.
The useful comparison is therefore architectural. Parallelism, KV-cache migration, quantization and token-level scheduling address different sources of serving cost or delay. TWP is distinctive because it changes the feedback-controlled policy for admitting workload.[4] Whether these approaches work well together, and how their effects interact, would require separate evaluation.
6. What the available evidence does not establish
The source summary establishes TWP's motivation, feedback inputs and headline performance claims. It does not expose the full experimental methodology. That gap limits independent assessment of how broadly the results apply.[4]
Several missing details are particularly important for an infrastructure evaluation:
- Models and hardware: the summary does not identify the experimental model architectures, parameter counts, GPU models or GPU counts.
- Workload construction: arrival-rate distributions, request-length distributions and request traces are unavailable.
- Serving configuration: exact batch sizes and absolute throughput values are not provided.
- Latency measurements: absolute TTFT, P99 latency and ITL values are unavailable.
- Control costs: scheduling overhead and ablation results for individual feedback signals are not exposed.
- Deployment scope: the material does not establish whether the throughput improvements hold outside serverless workloads.[4]
These omissions do not negate the reported findings. They do mean that a team cannot reproduce the evaluation or map its results reliably to a specific deployment using the summary alone.
The absence of ablations is especially relevant to understanding the mechanism. Without those results, the available evidence does not show how much of the improvement comes from ITL feedback, queue-depth feedback or workload characterization. Likewise, without scheduling-overhead measurements, it is not possible to quantify the cost of running the control loop.[4]
The appropriate next step is verification rather than extrapolation. Teams considering this approach should seek the full methodology, identify the baseline configurations and examine the workload conditions associated with the largest gains. The headline percentages are useful signals of potential, but they are not substitutes for deployment-specific evidence.
7. What this means for teams running their own inference infrastructure
TWP makes admission control worth examining as a first-class performance decision. Its reported results suggest that regulating workload through token-generation feedback can improve throughput while reducing latency instability in variable serverless workloads.[4] For teams operating their own infrastructure, the immediate lesson is to evaluate scheduling behavior alongside model execution efficiency.
A practical assessment should begin with the service objective. Decide whether the deployment is constrained primarily by TTFT, token-delivery consistency, tail latency, throughput or a combination of these. Then assess candidate scheduling policies against those objectives together. A higher throughput number alone should not settle a decision when predictable latency is also required.
Next, use representative workload variation. Because TWP targets differences in request lengths and arrival patterns, an evaluation should reflect the conditions the team expects to operate under. Results from a single workload shape would provide a limited basis for judging a feedback-controlled scheduler.
Finally, measure the outcomes that the available summary leaves unresolved. Record absolute latency and throughput, determine the scheduler's overhead and assess hardware behavior separately from completed work. Cost or energy claims should follow direct measurements rather than assumptions based on throughput gains.
TWP does not establish that every deployment needs token-level pacing, nor does the available evidence justify a universal performance forecast. It does offer a concrete systems hypothesis: admission decisions can become more effective when they respond to the runtime behavior of autoregressive generation.[4]
For infrastructure teams, that is the central takeaway. Before treating unstable latency or limited throughput solely as a need for more compute, examine how work is admitted. Token-level feedback is a promising direction to test, with the final decision grounded in reproducible results for the workload the team actually runs.
Sources
- [1]Fractional Power-of-Two Quantization for Efficient and Effective Multiplier-Free LLM Inference
- [2]Towards Green AI: Evaluating Energy Efficiency for Quantized LLM Inference
- [3]Scaling LLM Inference via Parallelism: Throughput-Latency Trade-off
- [4]Stable Token-level Scheduling for Serverless LLM Inference
- [5]Efficient KV Cache Migration for Geo-Distributed LLM Inference in Collaborative Edge Computing
- [6]Compositional Performance Modeling of LLM Inference Clusters with Hierarchical KV Caching
- [7]SGLang and Miles Add Day-0 Support for Muse Spark Open
- [8]Optimizing AI Deployments with VMware Cloud Foundation ...
- [9]From Long Context to Selective Memory:A Survey of Memory-Centric Compression for Large Language Models
- [10]Multi-Turn Memory, Mixed Precision, and Safer Rollouts
Researched from the sources above and fact-checked against them before publishing.
See what this means for your infrastructure.
Book a discovery call and get a benchmark projection for your hardware and model.
SCHEDULE A CALL