LLM Enhancements
UlaCache and the Case for Unified KV-Cache Addressing
UlaCache unifies GPU and CPU KV-cache addressing, reporting up to 2.51× peak decoding throughput under matched memory budgets.
Long-context inference creates a memory-management problem that persists throughout generation. Each processed token contributes key and value tensors that later attention operations may need. As the context grows, so does this retained KV state. For serving infrastructure, the challenge is not only executing the model, but also keeping its cache available within the memory resources assigned to the workload.
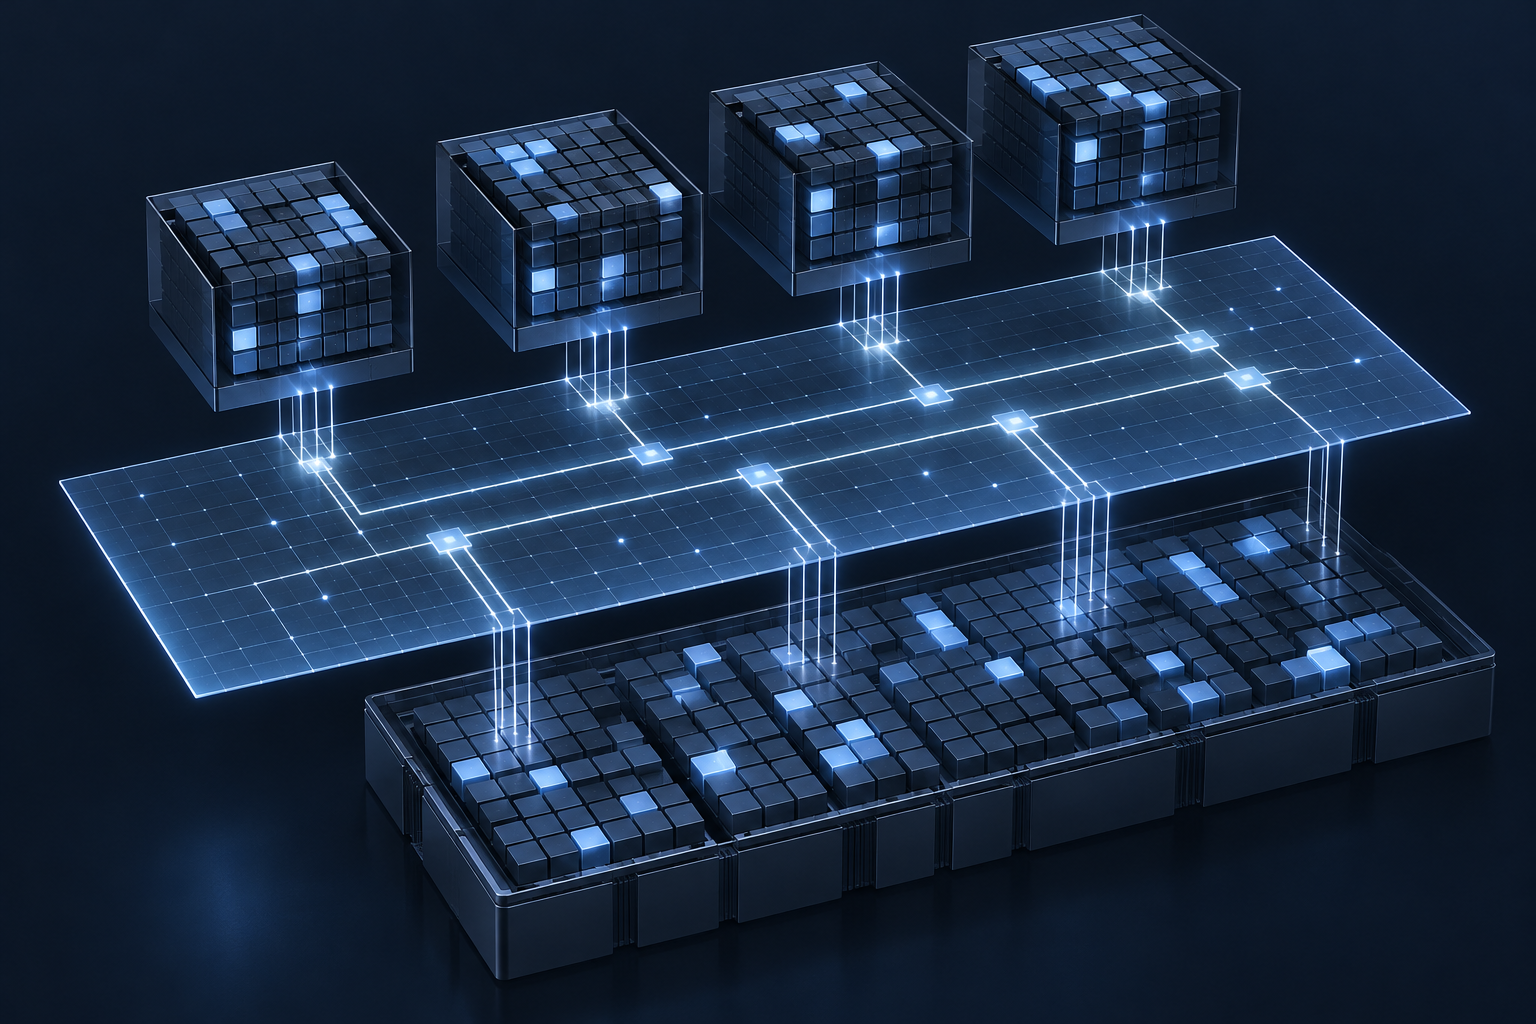
UlaCache approaches that challenge through a unified logical address space spanning GPU KV pools and optional CPU memory. Rather than treating a cached block’s identity as inseparable from its physical location, the system separates those concerns. Its reported results reach 2.51× peak decoding throughput relative to a state-of-the-art baseline, with speculative decoding enabled and CPU and GPU memory budgets matched. [3]
Those conditions are central to understanding the contribution. UlaCache is not presented as a new quantization format or a new attention approximation. It is a cache-management system for sparse LLM serving, with an architectural idea that deserves attention independently of its largest benchmark result.
For engineers and infrastructure buyers, the useful questions are straightforward: what does unified addressing change, what do the measurements establish, and what evidence is still needed before adopting the approach?
1. The problem: KV state grows beyond a simple placement decision
The paper, “UlaCache: Unified Logical Addressing for Sparse LLM Serving,” was submitted to arXiv on October 21, 2026, and updated on October 22, 2026. Its motivation is the memory cost of KV caches in long-context LLM inference. [3]
During autoregressive generation, previously computed keys and values remain available for subsequent attention operations. Longer contexts therefore increase the amount of retained state. That creates a serving-system constraint: the cache must remain usable even as its memory footprint expands.
When KV state spans GPU and CPU memory, capacity is only one part of the problem. The system also needs to track residency, coordinate movement between memory tiers, and maintain the mapping that attention execution depends on. Managing GPU-resident and CPU-resident entries as separate pools introduces coordination work around those responsibilities.
UlaCache’s contribution is to organize that distributed state through one logical address space. GPU KV pools and optional CPU memory become parts of a common cache-management model. [3]
The distinction matters because retaining a block and having it resident on the GPU are different requirements. A logical identity can remain stable while physical placement changes. Conceptually, that allows the serving system to preserve KV state without requiring all of it to occupy GPU memory at the same time.
This does not make placement irrelevant. Instead, it shifts the architectural emphasis toward runtime management: where state resides, which state execution needs, and how the system preserves a usable view of the cache. The available evidence supports that framing, but not a claim that memory movement becomes free or that GPU capacity stops mattering.
2. What unified logical addressing changes
The central idea is straightforward: expose GPU KV pools and optional CPU memory through a single logical address space. A cached block’s logical identity is separated from its current physical location. [3]
That is a management abstraction, not a statement that the underlying memories are physically identical. The paper’s available abstract does not establish equal access behavior across GPU and CPU storage, nor does it describe a mechanism that removes transfer overhead. The supported claim is narrower and more useful: the system provides a unified way to address KV state across those resources.
For serving architecture, the distinction between identity and location provides a different way to organize cache responsibilities. Placement can change without making physical residency the defining identity of the cached state. The logical layer is intended to coordinate distributed residency while preserving the cache’s usability for decoding. [3]
Several implementation questions remain unanswered in the available source:
- What address format identifies a logical block?
- What allocation or page size does the system use?
- How does it choose which state stays on the GPU?
- What metadata connects logical addresses to physical storage?
- How are transfers coordinated with execution?
None of those details should be inferred from the phrase “unified logical addressing.” The abstract does not specify the replacement policy, transfer protocol, or metadata structure. [3]
That boundary is important when comparing UlaCache with an existing serving stack. Architectural similarity is not enough to establish implementation equivalence. Two systems could both separate logical identity from physical location while making different decisions about allocation, movement, and execution coordination. The abstract establishes UlaCache’s organizing principle, not a complete blueprint for reproducing it.
3. Why sparse serving and speculative decoding belong in the story
UlaCache explicitly targets sparse LLM serving. In this setting, the relevant systems problem includes managing the subset of KV state needed by a sparse execution path while supporting GPU and CPU storage. It is not simply a claim about reducing attention operations. [3]
This focus connects cache management to execution behavior. The value of a placement strategy depends on which retained state the execution path needs. A unified logical view is therefore part of a larger serving configuration, rather than an isolated optimization whose benefit can be assumed independently of the workload.
The reported measurements also enable speculative decoding. That qualification needs to travel with every headline speedup because the available evidence does not report the effect of disabling it. CPU and GPU memory budgets are matched between UlaCache and the baseline. [3]
The measured outcome consequently reflects a combination of factors:
- KV-cache placement across GPU and CPU memory.
- Sparse-serving execution.
- Speculative decoding.
- The selected hardware and parallelism configuration.
- Equal CPU and GPU memory budgets for the comparison.
The available abstract does not provide an ablation that separates unified addressing from the other components. It therefore cannot establish how much of the improvement comes from the addressing layer alone. [3]
For engineers, the practical lesson is about attribution. The results support the conclusion that the tested UlaCache configuration improves peak decoding throughput over the reported baseline. They do not support assigning the entire gain to paging, sparse attention, speculative decoding, or any other single mechanism.
That does not diminish the systems result. It defines the level at which the evidence should be interpreted: a serving configuration under stated constraints, not a universal multiplier attached to one abstraction.
4. Reading the throughput results without overstating them
UlaCache reports four peak decoding-throughput speedups relative to a state-of-the-art baseline. The experiments use speculative decoding and matched CPU and GPU memory budgets. [3]
| Hardware | Data parallelism | Tensor parallelism |
|---|---|---|
| H200 | 1.16× | 1.70× |
| B300 | 1.73× | 2.51× |
The largest reported result is 2.51× on B300 with tensor parallelism. B300 data parallelism reaches 1.73×, while the H200 results are 1.16× for data parallelism and 1.70× for tensor parallelism. [3]
Two patterns are visible in these figures. Tensor parallelism shows the larger improvement on both hardware platforms, and B300 shows the larger improvement within each listed parallelism category. Those are observations about the reported comparisons, not explanations of why the differences occur.
The abstract does not establish whether hardware generation, parallel execution strategy, workload characteristics, or interactions among them account for the pattern. It would therefore be premature to claim that tensor-parallel deployments always benefit more, or that a hardware change alone produces the larger gain.
The word “peak” also matters. These are peak decoding-throughput results, not a complete characterization of serving performance. The source does not provide absolute tokens per second, request latency, or performance across a range of operating conditions. [3]
Matched memory budgets strengthen one aspect of the comparison: the reported improvement is not presented as the result of simply assigning UlaCache more CPU or GPU memory. However, the actual budget sizes are not specified in the abstract. [3]
The defensible summary is therefore precise: UlaCache reports 1.16× to 2.51× peak decoding-throughput gains across the listed configurations under matched memory budgets with speculative decoding enabled. Anything broader requires additional measurements.
5. What the available evidence cannot tell infrastructure buyers
A throughput ratio is useful, but it is not a deployment assessment. The available UlaCache source is an arXiv abstract, and several details needed to connect the result to a production workload are absent. [3]
First, the abstract does not identify the evaluated models, their parameter sizes, the tested context lengths, or the sequence-length distributions. Batch sizes are also unavailable. Without those details, a team cannot determine how closely the evaluation resembles its own serving demand.
Second, the state-of-the-art baseline is not named in the available abstract. That leaves an important comparison question open: what exact system and configuration did UlaCache improve upon? The label alone does not establish how the baseline relates to a buyer’s current deployment.
Third, the source does not report CPU-GPU transfer volume or transfer latency. Those measurements would help explain how the design uses the memory hierarchy and what coordination costs accompany the throughput improvement. The absence of those measurements means the speedup cannot be treated as proof that movement between tiers is negligible.
Finally, absolute throughput and request latency are missing. A relative peak-throughput result does not, by itself, establish lower latency, lower energy use, reduced infrastructure cost, or better quality of service. [3]
These omissions do not invalidate the reported comparison. They limit the decisions it can support. The abstract is enough to identify an architectural direction worth investigating and a set of promising benchmark outcomes. It is not enough to calculate deployment economics or commit to a production performance target.
For buyers, the appropriate response is neither dismissal nor extrapolation. It is to request the configuration and measurements that connect the published result to the intended workload.
6. Turning the research into a useful evaluation plan
An evaluation should distinguish two questions: whether a UlaCache-style system improves the target deployment, and why it improves it. The first requires a representative comparison. The second requires measurements that isolate the contributing mechanisms.
Start with workload correspondence. Request the evaluated model configurations, context lengths, sequence distributions, and batch sizes. Then compare those characteristics with the intended deployment. The abstract does not supply them, so they remain prerequisites rather than assumptions. [3]
Next, make the resource comparison explicit. Record the CPU and GPU memory budgets, identify the baseline, and preserve the stated speculative-decoding condition when attempting to reproduce the reported result. A comparison with different resource limits answers a different question from the one summarized in the paper.
Measure more than the best throughput point. Absolute decoding throughput and request latency are necessary to understand whether a relative gain addresses the team’s operating requirements. Keep the reported metric and the deployment objective separate: higher peak decoding throughput is evidence about throughput, not automatically about latency or cost.
For architectural attribution, request cache-placement measurements, CPU-GPU transfer volume and latency, and an ablation separating unified addressing from other UlaCache components. A comparison with speculative decoding disabled would also clarify a condition the available abstract leaves unresolved. [3]
Finally, evaluate the parallelism configuration that matters to the deployment. The published results distinguish data parallelism from tensor parallelism, and the gains differ materially between them. Treating the 2.51× result as representative of every configuration would discard information the paper explicitly provides.
This approach turns an interesting headline into a testable infrastructure hypothesis: unified KV management may improve sparse-serving throughput within a fixed memory envelope, but the magnitude and operational value need to be established for the target environment.
7. What this means for teams running their own inference infrastructure
UlaCache’s most consequential idea is the separation of KV-cache identity from physical residency across GPU pools and optional CPU memory. It reframes long-context cache scaling as a coordinated memory-management problem, rather than only a question of how much state fits on a GPU. [3]
For teams operating their own inference infrastructure, that suggests a useful architectural review. Examine whether the serving stack’s cache model can represent retained state independently of its current tier. Ask where placement decisions live, how residency is tracked, and what evidence is available about the cost of making distributed KV state usable for decoding.
Those questions are worthwhile even before a deployment decision about UlaCache. They focus attention on the management boundary the research targets, without assuming that the abstract provides implementation details it does not contain.
The reported throughput gains make the approach worth evaluating, particularly for the listed tensor-parallel configurations. But the responsible next step is a workload-matched study, not applying the largest multiplier to an existing capacity plan. Model details, memory budgets, baseline configuration, latency measurements, transfer behavior, and ablation results are still needed for a rigorous assessment. [3]
The takeaway is therefore both promising and bounded. UlaCache reports substantial peak decoding-throughput improvements in sparse serving under matched memory budgets with speculative decoding enabled. Its unified logical address space offers a concrete systems direction for managing growing KV state. Teams should investigate that direction while keeping the architectural claim, the benchmark conditions, and the production decision clearly separate.
Sources
- [1]Exploiting the Flexibility of LLM Inference for Frequency Regulation Service
- [2]How Developers Configure LLM Inference: A Large-Scale Study of Real-World Practices
- [3]UlaCache: Unified Logical Addressing for Sparse LLM Serving
- [4]Efficient CPU-GPU collaborative MoE inference via Adaptive Expert Assignment
- [5]Prism Attention: Proposal-Refined Index Sharing Mechanism for Efficient LLMs Inference
- [6]Local Inference of LLMs on Long Contexts: A Data Systems Perspective
- [7]DLite: History-free Speculative Decoding for Agentic AI - alphaXiv
- [8]LLM-assisted federated Bayesian dynamic graph attention network for ...
- [9]EdgeWise: Bringing Long-Horizon Agents to the Edge via ...
- [10]New Co-Design Framework Speeds Up LLM Inference on Mixed Hardware by Taming
Researched from the sources above and fact-checked against them before publishing.
See what this means for your infrastructure.
Book a discovery call and get a benchmark projection for your hardware and model.
SCHEDULE A CALL